Business
Customer Feedback Surveys That Lead to Real Changes

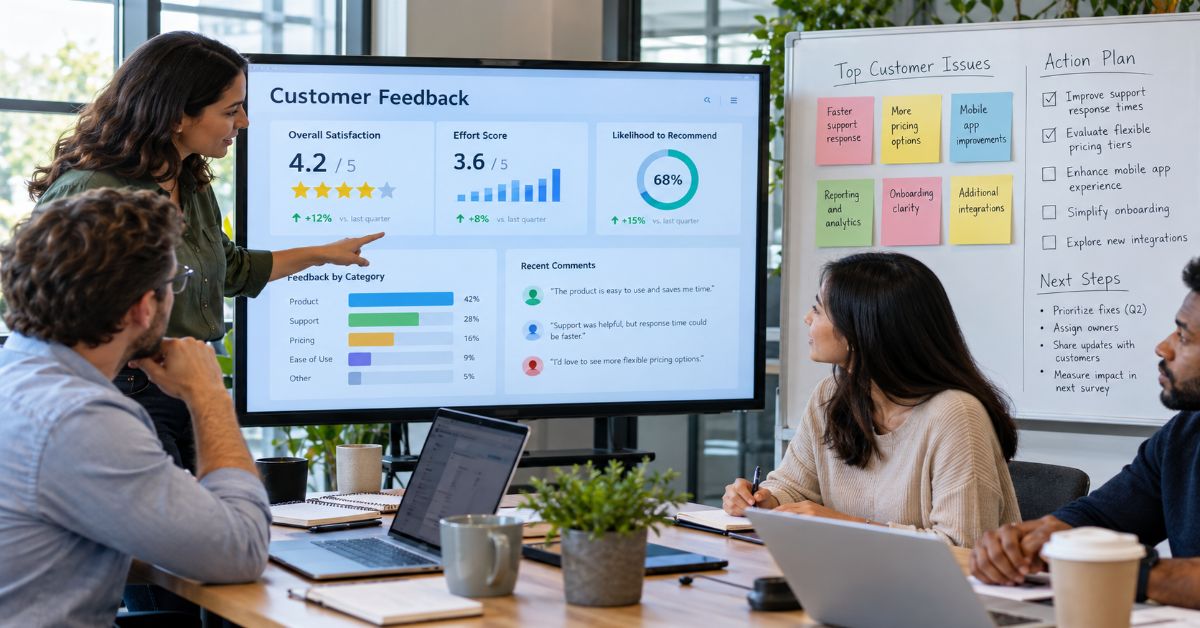
Customer feedback surveys are useful only when the answers can change a real decision. A business can collect hundreds of five-star ratings and still lose customers if nobody identifies recurring friction, assigns responsibility, or checks whether the fix worked. The effective approach is to begin with an action the team is prepared to take, then work backward to the shortest survey capable of informing it.
A customer feedback survey is a structured set of questions about a product, service, purchase, support interaction or relationship. It can measure satisfaction, reveal the cause of a problem or flag a risky customer experience. But it cannot automatically tell a business what caused a change in revenue or retention. The surrounding workflow matters just as much as the form.
Most guides begin with dozens of example questions. That is helpful when wording is the obstacle, but it often skips a more important question: what happens after someone answers? This guide starts there. It maps customer moments to survey types, provides ready-to-adapt templates, explains an analysis process a small team can run in a spreadsheet and shows how to evaluate the resulting change.
Question wording deserves care. Pew Research Center documents how answer options, ordering and pretesting affect survey measurement. Rather than treating survey numbers as objective truth, teams should treat them as signals requiring context and validation (Pew Research Center, n.d.).
Start With the Decision, Not the Questionnaire
The one-decision, one-survey rule
Before writing a question, complete this sentence: “If respondents tell us ___, we will decide whether to ___.” If the second blank cannot be filled, the proposed survey lacks a concrete purpose. A checkout team might decide whether to simplify payment authentication; a support manager might decide whether to rewrite a troubleshooting flow. Brand loyalty and feature requests are different decisions and usually deserve different instruments.
A minimal decision record names five fields: customer moment, intended decision, owner, evidence threshold and outcome metric. That small commitment keeps attractive but irrelevant questions out of the form. It also stops a survey from becoming an inbox for every department’s curiosity.
A six-step feedback-to-action system
- Define the decision and the business metric it could affect.
- Select the customer event closest to that decision.
- Ask the fewest questions needed to explain the behavior.
- Assign each response to a person or team with authority to act.
- Set review and escalation rules before results arrive.
- Make a change, notify customers where appropriate and recheck the outcome.
The model is a working editorial framework, not a validated scientific scoring method. Teams should adapt its thresholds to their volume, severity and risk.
Choose the Survey That Fits the Business Decision
CSAT, NPS and CES answer different questions. Customer Satisfaction Score (CSAT) commonly asks for satisfaction with an interaction; Customer Effort Score (CES) asks how easy a task felt; Net Promoter Score (NPS) asks likelihood to recommend. Qualtrics describes these as complementary measures, not interchangeable diagnoses (Qualtrics, n.d.).
| Decision | Instrument | Best trigger | What to do with it |
| Improve support resolution | CES + resolution check | Soon after ticket closure | Audit handoffs and reopened tickets |
| Repair first-use friction | Milestone micro-survey | After first attempt at key task | Fix blockers in activation flow |
| Reduce purchase abandonment | Exit or abandonment prompt | At exit or follow-up with permission | Inspect payment or shipping barriers |
| Monitor relationship risk | NPS + reason | Periodic relationship review | Segment by account and usage |
| Improve delivery | Post-delivery CSAT | After confirmed delivery | Separate carrier issues from product issues |
| Evaluate feature usability | In-app task survey | After feature use | Check completion and error logs |
Why a score should not become the decision
A rise in CSAT after a change might reflect a different mix of respondents rather than a better experience. NPS can move because of price, public news or competitive alternatives. CES may identify friction without showing why it occurred. Compare relevant behavioral outcomes and consistent customer segments before attributing impact.
For adjacent website journeys, Aperplexity’s practical discussion of navigation and shortcut design illustrates why removing a repeated customer task can matter more than adding another feedback prompt.
Internal reading: quick links and reducing navigation friction
Timing Is Part of Survey Quality
Ask too early and customers cannot assess the outcome; ask too late and details fade. A support survey belongs after the resolution is credible, not necessarily the instant an agent marks a ticket closed. Delivery questions should distinguish ordering, shipping and product use. For a long onboarding journey, a milestone is more informative than an arbitrary “day three” email.
| Moment | Useful prompt | Common timing mistake |
| Support resolved | “How easy was it to get your issue resolved?” | Sending before customer confirms success |
| First successful use | “What nearly stopped you?” | Surveying before the core task |
| Order delivered | “What made delivery difficult, if anything?” | Confusing shipping with product quality |
| Cancellation | “Which factor mattered most?” | Using a generic satisfaction score only |
| Quarterly account review | “What would affect your renewal decision?” | Over-surveying accounts with low activity |
Channel choice matters. An in-app question can capture immediate product friction; an email can invite a considered relationship assessment. Use suppression rules so one customer is not asked about the same journey by three different teams in a week. The exact cooldown should be piloted, not marketed as a universal best practice.
Write Questions That Preserve the Evidence
Ask behavior first and interpretation second
“What were you trying to complete?” anchors the answer in a real task. “What made that step difficult, if anything?” invites a specific observation without presuming failure. By contrast, “Why was checkout so confusing?” builds a negative conclusion into the question. Pew Research Center advises clear, specific wording and response options that do not overlap.
Replace double questions with single decisions
Bad: “Was the agent fast and helpful?” A customer may have received fast but incorrect advice. Better: “Was your problem resolved?” followed by “How easy was it to get help?” These separate outcome from effort. Another bad question is “Did price and delivery meet expectations?”—two topics with potentially opposite answers.
Use a question audit before sending
- Does every question connect to an owner and decision?
- Could a respondent interpret it in two reasonable ways?
- Are answer choices distinct and sufficiently complete?
- Is open text optional when possible?
- Have a few target customers interpreted the questions as intended?
- Can respondents skip or decline sensitive information?
Treat a three-to-seven-question range as a planning heuristic for compact operational surveys, not a universal research standard. Short, event-driven micro-surveys may need only one scored prompt and an optional comment; formal studies may require considerably more.
Three Copy-Ready Customer Feedback Survey Templates
SaaS onboarding: diagnose stalled activation
Trigger: after a user attempts the first meaningful task. Decision: whether to revise setup instructions, permissions or the product flow.
- What were you trying to accomplish today?
- Were you able to complete it? (Yes / Partly / No)
- Which step, if any, slowed you down? (Select one)
- What change would make that step easier? (Optional)
Route “No” answers attached to blocked setup or permissions to product and support. Compare answers with actual activation events; a customer saying setup felt easy does not prove the feature was adopted.
Ecommerce: find preventable purchase friction
Trigger: after a completed order or an eligible abandonment follow-up. Decision: what to test in checkout next.
- Which part of checkout took the most effort?
- Did anything almost stop you from placing the order?
- What, if anything, would make your next order easier? (Optional)
Do not ask post-purchase customers to recall an abandoned purchase they never made. Segment mobile and desktop experiences and inspect actual error logs. Marketing creativity can influence intent, but checkout success requires a functioning customer path, a distinction explored in Aperplexity’s analysis of participation-based campaigns.
Internal reading: marketing campaigns and measurable customer actions
Support: separate courtesy from resolution
Trigger: once a case has reached a meaningful outcome. Decision: whether to update scripts, escalation or staffing.
- Was your issue resolved? (Yes / Partly / No)
- How easy was it to reach a resolution? (Very difficult to very easy)
- Which part of getting help took the most effort? (Optional)
- May our team contact you to clarify the issue? (Optional)
Agent politeness is not equivalent to issue resolution. Monitor repeat contacts and reopened cases alongside survey ratings. If the survey reveals repeated outages, technical service readiness may be more important than revised support language.
Internal reading: status probes and the difference between healthy signals and real service quality
Analyze Responses Without a Data Science Team
Begin with a simple response log: date, touchpoint, segment, score, verbatim comment, theme, severity, owner, status and outcome. Remove personally identifying details that are not needed for the decision. A spreadsheet can support the first several hundred responses if someone maintains consistent tags and reviews uncertainty.
Separate frequency, severity and confidence
A frequent annoyance may cost seconds while a rare billing defect can lose a major account. Give each issue a frequency count, severity rating and confidence note. An optional triage score is frequency × severity, but this is a heuristic: it is not causal proof and it should never outrank an urgent security, accessibility or safety issue.
| Issue (illustrative) | Responses | Severity 1–5 | Triage score | Decision |
| Confusing setup invitation | 12 | 3 | 36 | Rewrite invitation and test activation |
| Incorrect invoice amount | 2 | 5 | 10 | Escalate immediately despite lower score |
| Hard-to-find help link | 9 | 2 | 18 | Test navigation placement |
These figures are hypothetical demonstrations, not results from a conducted survey. If only a few customers respond, call the output a set of leads rather than a representative sample. Review the distribution of who did not answer, and avoid presenting a percentage without its denominator.
Compare groups before approving a fix
Segment by lifecycle, plan, device, region or case type when sample size permits. Consider whether a highly dissatisfied group is overrepresented in the responses. Look for a second signal: funnel data, contact transcripts, refunds, usage logs or interviews. Agreement between sources strengthens the case, although it still does not automatically establish causation.
Create a monthly three-fix review
Produce one page showing the top three fix candidates, customer evidence, expected metric, implementation owner and check-in date. “Improve satisfaction” is not a measurable work item. “Reduce support tickets reopened within seven days after password-reset help” is. The point is to convert sentiment into testable operational changes.
Close the Loop Without Making Empty Promises
Feedback should lead to either an action, a reasoned decision not to act, or a request for more information. Route severe payment and access problems quickly; group minor requests for periodic review. Where contact permission exists, acknowledge the customer’s problem and give a factual update only after a change is shipped.
A useful message is: “You reported difficulty finding invoices. We moved the invoice link into Billing. We are checking whether related support requests fall.” Avoid promising every suggestion will enter the product roadmap. Some requests conflict, and prioritization must consider costs and other affected customers.
Run before-and-after comparisons carefully. If seasonality, pricing or traffic mix changed at the same time, a better outcome cannot be credited to the survey-driven fix without further evidence. A controlled experiment can help when the decision is consequential and volume allows it.
Risks: Selection Bias, Privacy and Survey Fatigue
Customers who answer may differ systematically from those who do not. Treat response rate as an operational health measure, not a magic quality threshold. A 40% response rate from a biased audience can mislead more than a smaller, well-targeted sample. Report invitation count, eligible population, responses and excluded cases.
Be transparent about anonymity. Truly anonymous surveys cannot be reliably used for individualized follow-up. If a response is linked to an account, say so, restrict access and avoid collecting details not needed for the purpose. Health, financial and employee-related feedback can introduce higher privacy and governance demands.
Too many surveys also change behavior: prompts interrupt tasks and can create annoyance. Use a suppression window, allow dismissal and remove survey questions whose answers have not changed a decision in recent review cycles.
The Future of Customer Feedback Surveys in 2027
By 2027, the more useful distinction may be between systems that summarize feedback and systems that can responsibly turn it into work. Survey platforms already offer automated analysis and templates; the harder requirement is preserving evidence, customer context and an accountable owner. That is a direction of travel, not a confirmed prediction about any specific vendor’s roadmap.
Language models can help classify hundreds of free-text answers into themes, but labels can be inconsistent, overlook sarcasm or flatten small but important groups. Human review of high-severity comments and a sampled set of ordinary comments remains necessary. Teams should document how tags are generated and check errors before treating a summary as a product requirement.
As more feedback arrives through in-app prompts, chat, reviews and customer calls, cross-channel deduplication will become more important. The same service failure reported by one account in four channels must not be mistaken for four separate customers. More data does not always mean a better decision; source quality and customer consent remain constraints.
The practical test in 2027 will not be how sophisticated the sentiment dashboard looks. It will be whether a team can trace an observation to a chosen action, a shipped change, and an outcome that was measured honestly.
Key Takeaways
- Choose one decision before choosing a survey template.
- Keep transactional questions close to the customer experience they measure.
- Distinguish satisfaction, effort and recommendation intent.
- Use clear, neutral wording and pretest it with target respondents.
- Rank recurring issues alongside severe exceptions; never ignore a serious rare failure.
- Give every priority issue an owner, a review date and an outcome metric.
- Tell customers what changed, but avoid attributing improvements without evidence.
Conclusion
An effective feedback program is a compact decision process, not a contest to collect the largest number of answers. A team should know why it is sending a survey, which customer moment gives the clearest evidence, and what would happen if the results show a problem. The survey itself can often be short. The discipline after the response is where the work begins.
A sound starting point is one journey, one owner and one business metric. Ask a neutral rating or behavior question, leave room for context, review responses by theme and severity, and choose a small set of fixes. Then measure whether customer behavior changed. If it did not, revisit the explanation rather than celebrating a higher score.
That restraint is valuable for small companies and large teams alike. Some feedback is noisy, some is contradictory, and some requests cannot be met. Customer research becomes trustworthy when those limits remain visible. The best survey is not the one that produces a flattering graph; it is the one that helps a team make a better decision and learn whether that decision worked.
Frequently Asked Questions
What is the difference between CSAT, NPS and CES?
CSAT gauges satisfaction with an experience, NPS asks likelihood to recommend, and CES measures effort associated with a task. They are not substitutes for retention, revenue or actual task completion data.
How many customer feedback survey questions should I ask?
For a brief operational survey, start with one primary question and one optional explanatory field; expand only if each added question informs an action. Three to seven questions is a useful planning range, not a fixed rule.
How can businesses increase customer survey response rates?
Choose a relevant event, place the prompt in the channel customers already use, explain what the answer will influence, make open text optional and avoid repeatedly surveying the same person. Test rather than assume a particular response-rate target.
Should feedback surveys be anonymous?
Use anonymity when candid aggregate feedback is the aim and individualized follow-up is unnecessary. If answers are linked to accounts for action, describe that clearly and limit access to personal information.
What is a good survey response rate?
There is no universally reliable benchmark. A response rate must be interpreted alongside the audience, recruitment channel, eligibility, survey length and nonresponse bias. Publish the denominator and examine who did not respond.
How do you analyze customer feedback survey results?
Tag comments consistently, compare frequency with business severity, segment users, seek confirmation in behavioral data, and assign owners to the most credible issues. Recheck the business metric after making a fix.
Which customer feedback survey questions should be avoided?
Avoid leading questions, two-topic questions, answer options that overlap, unnecessary sensitive details and questions whose answers cannot influence a decision. Pretest unfamiliar wording before a broad launch.
Methodology
Research reviewed ten publicly visible customer-feedback and satisfaction-survey guides dated or updated around 2026, including SurveyMonkey, Formbricks, ShipTell, Pinlyx, Forms Expert, Gorgias, UserInsight, SurveyMonkey UK, eesel AI and Qualtrics, to compare coverage of examples, score types, timing and action. Search rankings vary by location and date, so this is a representative comparison, not a verified universal top-ten ranking.
The article’s decision and triage frameworks are proposed operational tools rather than externally validated models. Question-design claims were checked against Pew Research Center, and measurement distinctions against Qualtrics and SurveyMonkey. No original field experiment, survey response-rate dataset, or hands-on software test was conducted. Sample tables explicitly use hypothetical inputs. A high rating may coexist with poor retention, and a low response count cannot justify population-wide claims.
This article was drafted with AI assistance. Human editorial review, verification of every citation and link, and approval of the final copy are required before publishing. Do not describe that review as completed until it has occurred.
References
Pew Research Center. (n.d.). Writing survey questions.
Qualtrics. (n.d.). How to design a customer experience survey.
SurveyMonkey. (2026, August 5). Customer satisfaction surveys: Tips, templates and examples.

A research dossier for target company decisions is useful only when it can prevent a specific mistake: buying a weak business, pitching the wrong buyer, choosing a risky vendor, or accepting a misleading job offer. A 40-page profile can look thorough while missing the one unresolved fact that should stop the deal.
The better approach starts with a decision and works backward. Every meaningful statement must answer four questions: where is the evidence, when was it checked, how strongly does it support the claim, and what decision would change if the claim were wrong? That method keeps company research from turning into a collection of screenshots, press releases, and unattributed estimates.
Recent guides offer long lists of company information and reusable templates. Those are useful as inventories, but even an evidence log can fail if nobody records conflicting claims or knows when old information needs refreshing. This guide therefore builds a practical decision system around seven layers, a source hierarchy, a copy-ready template, a fast-screen option, and a sample recommendation. The examples are illustrative, not reports about actual companies.
Public-company disclosures, trademarks, hiring signals, customer complaints, and financial statements have different evidentiary value. The skill is not collecting all of them. It is recognizing which ones matter for the decision in front of the reader, while documenting what remains unknown.
Start With the Decision, Not the Company Profile
A dossier is a working intelligence file, not necessarily a polished report. Write the intended decision and the conditions for a yes or no before opening the first browser tab. Otherwise, researchers can spend hours finding facts that do not affect the outcome.
| Decision | Question to resolve | Highest-value evidence |
| Sales | Is there a fit and who can authorize a purchase? | Product stack, pain signals, buyer map, recent initiatives |
| Investment | Can this firm compound value at an acceptable risk? | Financial filings, cash flows, customer concentration, valuation |
| Recruiting | Is the role and employer stable enough? | Role history, management turnover, financial position |
| Partnership | Can this partner deliver without conflicting incentives? | Customer references, channel conflicts, contracts, legal status |
| Acquisition | What could impair value or integration? | Ownership, liabilities, contracts, personnel dependencies |
| Vendor vetting | Can key service and security claims be corroborated? | Legal identity, compliance evidence, service history, references |
Write the stop condition first
Consider a vendor review: “Pause procurement if the legal contracting entity cannot be verified or if a material security claim cannot be documented.” That threshold makes the investigation smaller and sharper. It also stops weak public signals from being mistaken for formal diligence.
The Seven-Layer Decision-First Dossier
Layer 1: Prove the legal entity
Map brand name → official website → contracting or registered legal name → appropriate business registry. Confirm jurisdiction, corporate status, and parent or subsidiary relationships where the records allow. A brand may belong to several legal entities, and a similar company name can point to the wrong business. Registered-agent details or a certificate of good standing should not be read as proof of solvency.
The key output is an entity-match statement: the records support this business identity, or the match remains uncertain. Use the second conclusion rather than quietly assuming the brand and legal entity are identical.
Layer 2: Trace how money enters the business
Describe the economic chain: customer → problem → offering → payment mechanism → renewal or repeat purchase → dependency. For subscription software, ask whether revenue depends on usage, seat counts, one large account, or a single marketplace. For manufacturers, examine buyers, order cycles, service agreements, and essential suppliers. Private-company revenue is often unavailable; pricing pages and customer logos do not establish realized revenue.
For perspective on why revenue must be tested against actual cost structure, compare the site’s Airbnb profit-margin break-even analysis; the broader lesson is that sales volume alone does not establish economic resilience.
Layer 3: Triangulate four kinds of signals
| Signal | Useful records | Interpretation limit |
| Money | SEC filings, financing disclosures, debt records | A financing round does not prove profitability |
| Hiring | Open roles, archived roles, executive changes | Hiring does not establish expansion or financial strength |
| Customers | Case studies, complaints, references, renewals | Testimonials are curated; reviews are self-selected |
| Legal and intellectual property | Court dockets, regulators, trademarks, patents | A filing or application is not proof of misconduct or success |
A conflict between signals is a reason to investigate, not to announce a scandal. A firm might report rising revenue while reducing headcount because it automated work or changed product lines. Record competing explanations and demand evidence before choosing one.
For public U.S. issuers, the SEC EDGAR filing search provides primary company disclosures. The records are a starting point for checking reported financial and risk statements, not independent validation of every management projection.
Layer 4: Grade the evidence, not the company
| Grade | Meaning | Use in decisions |
| A | Direct primary record supports the narrowly stated claim | Can support key findings, with scope and date |
| B | Credible independently reported or corroborated fact | Use with attribution and caveats |
| C | Company statement without independent confirmation | Label as self-reported |
| D | Reasoned inference from indirect observations | Separate from confirmed facts |
| E | Rumor, anonymous assertion, or untraceable claim | Do not use to justify a decision |
This A–E scale is an editorial heuristic, not an audited probability model. Grade each claim individually. An official company brochure is a primary source for “the company says X,” but it is not automatically independent proof that X is true. A first-party financial filing is authoritative evidence of what was disclosed; auditors, accounting standards, reporting periods, and subsequent restatements still matter.
Layer 5: Keep a contradiction log
| Claim | Counter-signal | Likely explanation to test | Status |
| “Rapid expansion” (company statement) | Fewer active vacancies | Growth might be in revenue, not staff | Open; C |
| “Enterprise only” (marketing) | SMB price tiers advertised | Different positioning by segment | Open; C |
| “Stable leadership” (recruiter) | Multiple recent executive departures | Different dates or incomplete claim | Escalate; D |
Classify conflicts as timing differences, mismatched definitions, material disagreements, or audience-dependent positioning. A contradiction is unresolved until the dossier includes an explanation, supporting evidence, and the implication for the decision. Never manufacture numerical trends from a small sample of job postings.
Layer 6: Give evidence an expiry date
A date checked is not enough. Add “review due” to every important fact. Suggested intervals, adjusted to risk: recruitment and product signals every 30–60 days; customer reviews every quarter; leadership every three to six months; legal status every six to twelve months; financial claims after the next filing or financing event. Material litigation and enforcement risks may warrant a fresh check immediately before signing. These are operating defaults, not regulatory requirements.
Layer 7: Publish a one-page decision memo
Finish with one of four calls: proceed, proceed with conditions, pause pending evidence, or do not proceed. Name three reasons, the largest outstanding risk, what would overturn the recommendation, an owner for the next check, and a deadline. Without this final page, a dossier remains a research archive.
Where to Find Records Others Miss
Start with the entity registry and official disclosures. For a U.S. publicly reporting company, EDGAR can show periodic reports, major risk factors, executive information, and exhibit disclosures. Trademark records and patent information can reveal applications or registered rights but rarely show commercial success. Courts and enforcement databases require special care: allegations are not findings.
The USPTO trademark search database provides application and registration records. Search multiple name variations and inspect ownership and status before linking an IP record to a business.
Local business journals, archived website pricing pages, conference speaker lists, app-update histories, procurement documents, and archived job ads can add direction and timing. Ask what each source can actually prove. An executive speaking at a conference establishes appearance on a program, not a partnership or commercial relationship.
When competitor claims involve intellectual property, the site’s AI-generated work and intellectual property explainer offers related context about why ownership claims need careful documentation.
A Copy-Ready Target Company Research Dossier Template
Copy the fields below into a spreadsheet or working document. Enter “not verified” wherever evidence is missing rather than supplying an estimate.
Decision brief
Target company; decision owner; decision and deadline; stop conditions; evidence threshold.
Identity
Brand name; legal name; registration jurisdiction; status; parent/subsidiaries; official domain; registry reference.
Business model
Core offer; customer groups; monetization; channels; customer concentration; supply or platform dependency.
Financial and operating signals
Filings or funding; cash/debt evidence; hiring changes; launches; customer evidence; period covered.
People and position
Leadership; relevant buyer; tenure; competitors; pricing position; strategic dependence.
Claim ledger
Claim; exact source; source date; checked date; grade A–E; review due; action relevance.
Conflicts and open questions
Conflicting claims; type of discrepancy; impact; source needed; research owner; due date.
Decision memo
Recommendation; three reasons; largest risk; conditions; evidence that would change the call; next action.
A Worked Example: Evaluating a Software Partner
Illustrative scenario only: a midsize company is considering a workflow software partner. The prospective partner lists major customer logos and advertises rapid deployment. A registry confirms the legal entity (A for identity), but public case studies only establish that the company claims named customer relationships (C until confirmed). Open engineering roles suggest continuing product investment (D for growth inference). A former customer review flags integrations as difficult (E without independent corroboration).
The resulting decision is “proceed with conditions”: ask for two current customer references, a written implementation plan, the contracting entity’s details, and operational security evidence relevant to the service. The dossier does not infer revenue, profitability, or platform reliability from logos and hiring. This is the crucial distinction between collecting signals and judging them.
The practical discipline resembles turning customer feedback into action rather than assuming that repeated opinions are reliable causal evidence.
Fast Screen or Deep Diligence?
A 15-minute first pass
In a quick sales or recruiting screen, record identity, decision objective, two high-value signals, two unknowns, and the next verification step. Keep the output to one page. It should decide whether the company deserves more research, not whether it is definitively safe.
A five-hour focused investigation
For a meaningful partnership review, allocate time to entity matching, primary records, revenue dependencies, customers, legal risks, contradiction checks, and a short memo. Five hours is an illustrative planning budget, not enough for a regulated procurement approval, audited valuation, or full M&A diligence. Escalate material issues to qualified legal, financial, or security reviewers.
Researching Private Companies Without Public Financials
Private entities may disclose little financial detail. Do not infer annual revenue from employee counts, website traffic, or investment announcements without a defensible model and clearly marked assumptions. Focus instead on observable operating claims and request evidence directly: financial references, customer retention support, signed contracts, supplier concentration, or management explanations. The refusal to provide an appropriate document can be relevant to risk, but confidentiality can also explain legitimate limits.
Keep alternative interpretations visible. A new patent application may reflect exploration rather than a product roadmap. A leadership change may be routine rather than a warning. An isolated negative review should prompt questions, not a finding. When risk is high and evidence weak, a conditional or paused decision is more defensible than a forced yes-or-no verdict.
Using AI Without Inventing Company Facts
Use AI to structure questions and extract information from documents that have already been collected. Do not rely on an unsourced AI-generated company summary as the evidentiary foundation. Ask the system for exact supporting language, document section, period, and gaps, then check those excerpts against the originals.
Copy-ready prompt: “Using only the attached records, identify each material financial, legal, leadership, operational, and customer claim. For each item, provide an exact supporting excerpt, page or section, evidence date, suggested confidence grade, and an additional independent check. Mark missing or contradictory information explicitly. Do not infer undisclosed revenue, customers, legal outcomes, or causal relationships.”
For a related discussion of privacy risks when compiling personal data, read the fast people-search accuracy and privacy guide.
Decision-Ready Quality Check
Score the dossier one point for each item completed: named decision; stop condition; verified entity; source for each material claim; reporting period; claim grade; contradiction review; review-due dates; stated unknowns; signed-off next action. A 9/10 score can still hide a fatal missing fact; treat the checklist as a completeness aid, never as a safety certification.
The Future of Target Company Dossiers in 2027
Company research is likely to become faster at extracting text from filings, tracking website changes, and spotting mismatches across records. The operational challenge will shift toward source identity, document versions, data rights, and proof that an apparent contradiction is real. Automated alerts can make evidence fresher, but also create false urgency when routine changes look dramatic.
The likely advantage in 2027 is not a longer data room generated by AI. It is a narrower chain from claim to primary record to decision: one that makes uncertainties visible and supports accountable review. That forecast is analytical, not a verified projection of adoption rates or tooling capabilities. Organizations should audit AI-assisted extraction and set review cycles according to materiality, not assume automation replaces diligence.
Key Takeaways
- The decision and stop conditions belong on page one.
- An entity match prevents researching a brand while contracting with a different company.
- A–E grades describe the evidence behind individual claims, not an overall trust score.
- Contradictions and review-due dates deserve dedicated fields.
- Public filings and trademark records have specific limits; they do not validate every marketing claim.
- The useful final artifact is a conditional decision with named next checks.
Conclusion
A target-company dossier succeeds when it reduces uncertainty around a real choice. Gathering every available fact is neither possible nor necessary. A better document proves whom the research concerns, isolates what would alter the decision, gives each material claim a defensible source, and exposes conflicts that an attractive company profile would overlook.
The greatest risk is false certainty. A public filing can be dated; a private firm may not disclose its numbers; a customer review may reflect only one experience. Naming those limitations is a sign of disciplined research, not a weakness. A decision-first framework makes it possible to proceed conditionally, ask for the right documents, or stop before an avoidable commitment. Keep the dossier short enough to use, detailed enough to audit, and current enough to trust.
Frequently Asked Questions
What is a target company research dossier?
It is an evidence-backed record of a company created for a defined decision. Unlike a general profile, it includes a claim-source trail, confidence labels, timestamps, contradictions, unresolved questions, and a recommended next step.
Is a company research dossier template the same as due diligence?
No. A template organizes work; due diligence is the substantive verification appropriate to the decision. Complex acquisitions, regulated vendors, and financial commitments can require professional legal, technical, financial, or compliance reviews.
Can a dossier rely only on public records?
Yes for some initial screens, but not for conclusions that require private financials, references, contracts, or internal controls. Mark unavailable information and make further review a condition of moving ahead.
How often should a business research dossier be updated?
Update material facts when new disclosures, leadership changes, operational signals, or legal events occur. Pre-set review dates help, but the expected decision date and consequence of error should determine urgency.
How should conflicting company information be handled?
Preserve both claims and their original dates. Check whether they refer to different entities, periods, or definitions, then seek stronger evidence. If the disagreement remains material, present it as unresolved.
What belongs in a vendor due diligence dossier?
Verify the contracting entity, service scope, customer references, security and compliance evidence, support capacity, financial dependencies, and important legal risks. The necessary depth depends on service criticality and access to systems or data.
Methodology
This guide draws on publicly accessible primary U.S. government search resources and a comparative review of current company-dossier guides. Its confidence grades, freshness intervals, quality checklist, and examples are proposed editorial methods, not empirically validated scoring systems. The sample business is fictional. No confidential company data or first-hand testing was used. References below should be checked again during human editorial review.
This article was drafted with AI assistance. Human editorial review and independent verification of all claims, citations, and links are required before publication. Do not represent those steps as completed unless they are actually completed.
References
U.S. Securities and Exchange Commission. (n.d.). Search filings. https://www.sec.gov/search-filings
United States Patent and Trademark Office. (n.d.). Trademark search. https://tmsearch.uspto.gov/
Google. (n.d.). Searching — Google Patents Help. https://support.google.com/faqs/answer/7049475?hl=en
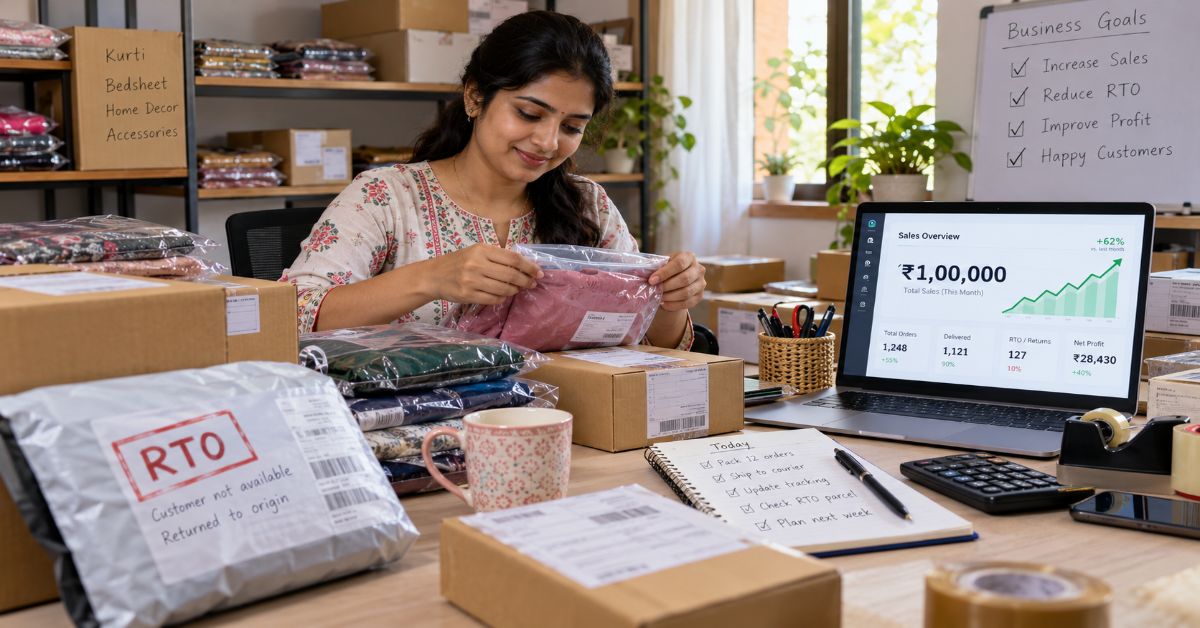
A Meesho Seller can reach ₹1 lakh in monthly sales and still make very little money: the gap is usually hidden in shipping, returned parcels, packaging, paid visibility and the cost of inventory that does not sell. Meesho advertises zero commission and a seven-day payment cycle after delivery, but neither promise makes a ₹399 order automatically profitable (Meesho, n.d.).
The useful question is not merely how to sell on Meesho. It is how to choose products that people actually accept, set prices that absorb predictable failures, and identify catalogs worth replenishing. Registration matters, but most sellers can finish it long before they understand their real order economics.
This guide uses a model ₹399 product to show the difference between gross revenue and contribution. It then proposes a return-to-origin (RTO) diagnostic, a product-selection screen, and a 30-day operating rhythm. The target of ₹1 lakh refers to monthly delivered merchandise sales, not guaranteed earnings. Every price, rate and proposed margin threshold in the worked examples is illustrative; seller-specific statements must be checked against the live Supplier Panel and settlement reports.
The approach is intentionally narrow. Instead of uploading hundreds of unrelated items or buying ads before a product is proven, start with a buyer problem, track a small group of SKUs and fix the cause of losses. A repeatable catalog is built from evidence, not from an impressive listing count.
The Profit Equation That Zero Commission Does Not Solve
Calculate contribution per delivered order
Net contribution per delivered order = realized selling price − product cost − packaging − allocated forward logistics − expected return/RTO loss − advertising − other transaction costs. This is a management estimate, not an income-tax profit figure; add storage, staff, damaged inventory, taxes and fixed overhead to estimate business profit. Do not double-count shipping if the settlement already includes it.
Meesho’s official supplier guidance describes zero commission, catalog management and a payment cycle tied to delivered orders. Its price-recommendation and quality tools can help sellers evaluate competitive pricing and customer return reasons (Meesho, n.d.). The actual applicable fees and deductions remain seller- and transaction-specific.
| Illustrative ₹399 order | Amount (₹) | Interpretation |
| Realized selling price | 399 | Assumes delivered and paid |
| Product landed cost | 180 | Include supplier freight |
| Packaging | 15 | Outer and inner protection |
| Shipping/logistics allocation | 60 | Example only; confirm settlement |
| Expected returns/RTO loss | 35 | Average provision across all orders |
| Promotion allocation | 20 | Spend divided by attributed deliveries |
| Illustrative contribution | 89 | 22.3% of realized price |
The ₹89 result is not a verified average Meesho seller profit. It is a worked calculation: 399 − 180 − 15 − 60 − 35 − 20 = 89. A seller who omits the ₹35 return reserve would overstate this example’s contribution by nearly 40%.
Set a break-even return threshold before setting an ad budget
Suppose a product yields ₹124 contribution before the expected returns reserve, and each failed shipment creates ₹175 in unrecoverable cost. A simplified loss-only threshold is 124 ÷ (124 + 175) = about 41.5% failed orders. That is not a safe target: it ignores fixed overhead, cash delays, damaged stock and customer returns after delivery. A business should set a much lower internal intervention threshold based on its own recent SKU history.
For better control, separate completed deliveries, pre-delivery RTO, and post-delivery returns. A refund after delivery may require product inspection and reverse movement; a COD refusal may never become a sale. They must not share the same denominator when calculating profit.
RTO Is a Diagnosis, Not Just a Percentage
Track the reason alongside the SKU
Return-to-origin means a shipment comes back before successful delivery. Failed customer contact, an inaccurate address, refusal on delivery and delivery attempts can contribute. A customer-initiated return after delivery is a separate event. The same product may suffer both, but each needs a different operational fix.
| Track per SKU | Calculation or field | Management use |
| Dispatched orders | Count of parcels sent | Defines shipment cohort |
| RTO rate | RTO parcels ÷ dispatched parcels | Detect delivery failure |
| Post-delivery return rate | Returned deliveries ÷ delivered orders | Detect expectation/quality gap |
| Reason code | Address / refusal / fit / damage / other | Choose the remedy |
| Net ₹ contribution | Receipts − all allocable costs | Decide whether to scale |
| Packaging version | Bag A / carton B | Test damage-related interventions |
A seller with 50 dispatched units and 11 RTOs has a 22% RTO rate. If revised listing details and delivery practices produce 9 RTOs out of the next 100 dispatched, that is 9%—but it is a hypothetical illustration, not a documented case study. Different time periods, customer mixes and courier conditions can create apparent improvements; compare like with like.
Apply controls that match the failure mode
For wrong-product expectations, replace edited or deceptive images with accurate photos, show dimensions and colors clearly, and write material and fit details in plain language. For apparel, include garment measurements and a model-size reference when available. For breakage, improve inner cushioning, outer packaging and tamper-evident seals. For inventory mismatch, reconcile stock before promising dispatch.
For permitted customer communications, follow Meesho’s actual messaging workflow and privacy rules. Do not assume an independent seller can call or WhatsApp every buyer: platform restrictions and access to customer details may prevent it. Instead, use in-panel support and fulfillment tools where available, and escalate recurring delivery failures with order-level evidence.
A disciplined returns investigation resembles a customer-experience feedback loop: customer feedback surveys tied to concrete decisions can help distinguish a vague complaint from a fixable packaging, sizing or delivery problem.
Design a Catalog Around One Buying Job
Why 20–40 related SKUs can beat 500 random ones
A tight catalog is easier to photograph accurately, pack consistently and measure. The 20–40-SKU starting range is a proposed pilot size, not an official platform recommendation. It could mean daily-wear cotton kurtis within a clear size band, practical kitchen-storage sets, or affordable desk-organizing items. Start with a customer use case and then test colors, sizes, bundles and price points without creating uncontrolled variation.
The catalog ladder below is a decision tool. “Premium” does not mean luxury; it might simply mean a better material or useful multi-pack. Margin ranges should be earned from actual sales rather than imposed as promises.
| SKU role | Purpose | Decision rule |
| Entry / traffic | Compete on a specific basic need | Keep only if contribution remains non-negative |
| Core | Meet repeated, proven demand | Replenish after stable delivery and margin |
| Improved / bundle | Offer measurable added utility | Show what changed and verify costs |
| Seasonal | Capture time-limited demand | Limit stock until sell-through is visible |
Select products with a return-risk filter
Search Meesho as a buyer and record visible price bands, pack quantities, review themes, imagery quality and missing product details. Do not infer sales volume from search position alone. Before purchasing stock, estimate landed cost, breakage risk, variant complexity and the cost to process one failed parcel.
Lightweight, non-fragile and non-size-sensitive items often simplify a new operator’s logistics, but demand and competition still determine whether those items can earn a margin. A small manufacturer with strong sizing and quality control may perform better in apparel than an inexperienced trader selling generic accessories.
Reliable physical inventory records matter as much as visible listings. The site’s inventory management systems guide explains why returns, reservations and physical stock must stay consistent; the same control problem applies to a Meesho catalog.
Listing Changes That Prevent Expensive Misunderstandings
Show what the buyer will actually receive
Use a clean, accurate hero image, followed by scale, material, color and pack-content views. A photographed item is not enough if a buyer cannot tell whether the order includes one piece or a pair. Describe washable status, capacity, exact dimensions, inclusions and limitations only when substantiated. For clothing, avoid vague “perfect fit” claims and provide garment measurements.
Keyword relevance matters, but images and attributes also need to prevent the wrong buyer from ordering. Write a descriptive product name, fill applicable category attributes and match colors and sizes to real inventory. Do not repeatedly edit successful listings simply to chase a ranking theory. Meesho has not published a complete public formula that establishes a universal weighting for click-through, ratings, price and delivery performance.
Accurate imagery is a business control, not decoration. The related discussion of e-commerce product photography standards explains why consistent product photographs must represent the item being sold.
Run one-variable listing experiments
For a weak listing, first diagnose whether the problem is discovery, clicks, conversion, refusal or post-delivery returns. If people see the item but rarely open it, test the lead photo. If clicks are healthy but delivery complaints mention size, improve measurements instead of lowering the price. Record the edit date and compare sufficiently similar order cohorts. Changes to price, photo, description and ads at the same time destroy useful attribution.
A ₹1 Lakh Monthly Sales Plan That Survives Arithmetic
At a ₹399 realized selling price, ₹100,000 in delivered merchandise value requires approximately 251 delivered units per month, or 8.4 per day. At 15% pre-delivery RTO, reaching 251 deliveries requires roughly 296 dispatched shipments if all other dispatches deliver; those extra shipments can create cost without revenue. Neither figure estimates demand or guarantees achievable traffic.
If the illustrative ₹89 contribution holds for 251 delivered units, the subtotal is ₹22,339 before fixed costs, other losses and tax. But the ₹35 return reserve in the model must already reflect RTO and returns across the relevant shipment base; otherwise the calculation double-counts. A seller should reconcile actual cash receipts and deductions before treating the estimate as earnings.
The first 30 days: build a trustworthy cohort
| Period | Main action | Evidence to retain |
| Week 1 | Choose one need, source samples, price 20–30 SKUs | Cost sheet, measurements, photos, pack tests |
| Week 2 | Publish accurate catalogs and validate fulfillment | Impressions if available, orders, stock accuracy |
| Week 3 | Investigate weak images, sizing and refusal reasons | Change log and order cohorts |
| Week 4 | Reconcile settlements and RTO/return reasons | SKU-level contribution and reorder decision |
Weekly reviews should use both unit economics and operations. A high-sales SKU that erodes contribution is not a winner. A slower SKU with stable deliveries may provide a better foundation for reinvestment. The goal is to move from listing activity to evidence-based replenishment.
Meesho Versus Other Marketplaces: Compare the Right Variables
Platform fees, shipping options, policies and seller eligibility change. A like-for-like ₹300 product comparison cannot be responsibly priced without the seller’s category, fulfillment choices, weight and active fee schedules. Use the following decision matrix rather than invented marketplace charges.
| Decision factor | Meesho | Amazon India / Flipkart |
| Seller onboarding | Official supplier flow; eligible non-GST route is restricted | Check current seller and GST eligibility individually |
| Commission headline | Official supplier pages advertise 0% commission | Category-dependent programs and fee schedules |
| True unit cost | Review seller-panel logistics, returns and promotion | Model referral, fulfillment, shipping and returns |
| Best-fit product | Depends on competition and cost control | Depends on demand, fees and delivery promises |
The zero-commission claim is a feature of Meesho’s published seller proposition, not a proof that it wins every ₹300 product comparison. Evaluate actual settlement data and conversion in each marketplace before choosing a primary channel.
Paid promotions only make sense after the catalog’s offer and delivery experience are sound. The site’s analysis of campaigns tied to measurable customer actions provides a useful parallel: attention is not the same thing as profitable customer behavior.
The Future of Meesho Selling in 2027
The direction of marketplace retail is toward more operational measurement, better catalog information and tighter cost discipline, but specific 2027 Meesho ranking, shipping or fee changes cannot be predicted from current public documentation. Sellers should not plan around rumors of algorithm updates or supposed guaranteed visibility hacks.
More automation in catalog uploads and inventory feeds may make it cheaper to publish a large product range. That creates a counterpressure: when listings are easy to produce, inaccurate product descriptions and unreliable stock can become more costly, not less. A seller with consistent SKU identifiers, genuine photos and return-reason data can respond faster to defects than someone relying on product count alone.
What is durable for 2027 is a practical capability, not a forecast: know landed cost, separate RTO from post-delivery returns, reconcile each settlement, and test product improvements with comparable cohorts. Platform tools will change; the arithmetic of profitable deliveries will not.
Key Takeaways
- Zero commission describes one fee line, not the total cost of delivering an order.
- Use delivered revenue, not dispatched order value, when setting a monthly sales target.
- Track pre-delivery RTO and post-delivery returns separately with reason codes.
- A focused SKU pilot gives cleaner learning than undifferentiated catalog expansion.
- Measure images and product detail by their effect on wrong-expectation returns as well as clicks.
- Reconcile current seller-panel deductions before allocating advertising or reorder budgets.
Conclusion
The strongest Meesho businesses are unlikely to be the ones that upload the greatest number of products first. They are the ones that can answer a less exciting question: after a real parcel is delivered—or comes back—what money actually remains? That requires accurate product information, reliable inventory, a sensible landed-cost model and a willingness to stop selling an attractive but unprofitable SKU.
A ₹1 lakh monthly sales target is useful as a planning exercise because it makes the order requirement concrete. It should not be mistaken for a ₹1 lakh income target, or as proof that demand exists. Start with a small cohort, identify where failed deliveries arise, and improve only what evidence supports. When a product repeatedly produces positive contribution, scale gradually enough that supply and fulfillment remain dependable.
The essential advantage is not a secret ranking factor. It is an operating system that makes bad assumptions visible before more money is committed to them.
Frequently Asked Questions
Is Meesho really commission-free for sellers?
Meesho’s official supplier materials advertise 0% commission. Sellers can still face shipping, promotional, tax-related or return-related costs depending on the current arrangement. Check the applicable agreement and actual settlement.
What documents are needed for Meesho seller registration?
Official onboarding describes a mobile number, email, bank details and either the relevant GSTIN or an eligible non-GST Enrolment ID/UIN. Pickup address and store details are also required. Eligibility can depend on seller status and geography.
Can I sell on Meesho without GST?
Meesho’s official onboarding states that eligible non-GST sellers can use an Enrolment ID/UIN and generally sell within their state. This is not an unrestricted exemption from all tax or marketplace obligations; verify eligibility before registering.
How do I reduce RTO on Meesho?
Break RTO down by SKU and reason first. Improve misleading photos, missing dimensions, packaging and inventory accuracy, then review delivery exceptions through approved seller-support channels. A single store-wide RTO number rarely identifies the cause.
How can I calculate actual Meesho seller profit?
Start from settled delivered-order receipts and subtract product cost, packaging, attributable logistics, actual return losses, ads and overhead. Separate inventory investment from expense recognition, and reconcile the result to platform settlements.
How does Meesho decide which product listings appear first?
Its complete ranking formula is not public. Competitive pricing and accurate catalogs may help shoppers make decisions, but no universal weighting of price, clicks, ratings or fulfillment can be verified. Focus on controllable product quality and economics.
Which products are best for a new Meesho seller?
Products with verifiable demand, affordable landed costs, simple packaging and manageable returns are reasonable candidates. Lightweight home items can simplify a pilot, while apparel can work for operators who know sizing and quality control.
Methodology and Editorial Limits
Research reviewed ten high-visibility 2026 guides for the “meesho seller” and “how to sell on Meesho” search intent: Zane Marketing, Dhanaay, SnapSeller, RegisterKaro, SW Cybernetics (multiple pages), EcomSarthi, The India Post, Limpo and MSMETOOLS. This is a non-personalized research sample, not a verified universal Google top-ten ranking. Most entries emphasize onboarding, zero commission and basic listings; several discuss margin and returns, so the topic is not wholly neglected. The differentiation here is operational measurement and explicit sample arithmetic rather than a claim of exclusive discovery.
Official Meesho supplier documentation was used for its stated commission, onboarding requirements, payout cycle, supplier tools and fulfillment descriptions. The numerical margin model and catalog cohort sizes are editorial illustrations, not platform measurements. No seller account was tested, no source was interviewed and no original performance study was conducted. Marketplace programs can change; the live Seller Panel and seller agreement take priority.
AI-assisted draft. A human editor must verify all citations, fees, calculations, link status and seller eligibility against current primary sources before publication; no completed human review is claimed.
References
Meesho. (n.d.). How to sell on Meesho. Official supplier information.
Meesho. (n.d.). Sell shirts online: Supplier tools, pricing and quality dashboard.
MSMETOOLS. (2026, October 9). How to sell on Meesho in 2026: GST, fees, returns and real margins.
Stock futures show where traders currently price future equity-index exposure, but an overnight drop does not guarantee a lower stock-market close. The important distinction is between a market that is repricing new information and a forecast that is certain to come true.
Consider a hypothetical Thursday night: an unexpected inflation release pushes bond yields higher, and S&P 500 futures fall 1% while the New York Stock Exchange is shut. That futures move matters. It tells investors that sellers were willing to transact at a lower price. Yet by Friday morning, a second data point, changed rate expectations or simply more buyers can move the contract back up. Neither the overnight percentage nor the eventual opening print is a prophecy.
Financial headlines often summarize the Dow, Nasdaq and S&P contracts as one arrow: green means a good day, red means a bad one. That shortcut hides the mechanics. Futures have an expiration month, a contract multiplier and a theoretical relationship to the cash index. They can move on thin overnight order books, and their price can change even when the economic outlook barely does.
The useful question is not “Are futures up?” It is “What changed, how strong is the evidence, and what risk would a trade actually create?” This guide turns that question into an approach that works whether the reader plans to trade futures, manage an equity portfolio or just interpret the morning news. All numerical trade illustrations are hypothetical, not live quotes or performance evidence.
What the ticker really represents
Index exposure without buying 500 shares
A futures contract is a standardized exchange-traded agreement tied to an underlying asset or benchmark and a specified expiration. In market broadcasts, “stock futures” usually refers to index contracts linked to the S&P 500, Nasdaq-100, Dow Jones Industrial Average or Russell 2000, rather than a future on one company. Major U.S. equity-index futures are generally cash settled, not settled by handing over hundreds of stocks.
A trader buying one E-mini S&P 500 contract (ES) receives long index exposure; one selling it receives short exposure. The ES multiplier is $50 per index point, so a 10-point change means $500 in profit or loss per contract before fees. Its Micro E-mini counterpart (MES) has a $5 multiplier. Smaller contract size reduces dollar exposure, but it does not make an unplanned trade safe.
CME Group explains the benchmark and contract family in its E-mini S&P 500 product overview; actual requirements, trading hours and specifications should be checked for the specific expiry.
Settlement, expiry and the contract month
A ticker typically refers to a particular expiration month, not a permanent share holding. Contracts are marked to market, with gains and losses reflected in account equity. Traders who want continuing exposure may close an expiring contract and open a later one, a process called rolling. Different contract months can trade at different prices, so comparing a new front month with yesterday’s expiring quote can create a false apparent jump.
Fair value: the missing bridge between futures and cash
Futures are not supposed to be identical to the index’s last cash-market reading. Carry costs and expected dividends create a theoretical basis. CME’s simplified fair-value relationship is: cash index × [1 + interest rate × (days to expiration / 360)] − dividends expected before expiration. It is an approximation; live markets incorporate funding conditions and trading frictions.
Illustration only: suppose a cash index stands at 5,000, annual financing is 4%, expiry is 90 days away, and expected dividends equal 12 index points. Fair value is approximately 5,000 × [1 + 0.04 × (90/360)] − 12 = 5,038. A future quoted at 5,040 would be roughly two points above this simplified fair-value estimate, not forty points of unexplained market optimism.
The formula and the arbitrage logic are documented in CME’s fair-value explanation. The traded price can remain away from the estimate when supply, demand, fees and market conditions intervene.
Three numbers to separate
| Reading | Question it answers | Likely mistake |
| Change versus prior futures settlement | How much did this contract reprice? | Treating it as cash-index return |
| Futures minus current cash index | What is the observed basis? | Calling the entire basis optimism |
| Futures minus estimated fair value | Is the quote rich or cheap versus a model? | Assuming model mispricing must close instantly |
Before the U.S. cash market opens, the “current” index level may itself be stale. Comparing live overnight futures with yesterday’s cash close without the basis adjustment can make the move look larger or smaller than the actual change in implied equities.
Seven overnight signals that can mislead
A directional move becomes more informative when several independent clues support it. The following table distinguishes the visible price from the inference readers sometimes make too quickly.
| Signal | Tempting conclusion | Better verification |
| Futures fall 1% | Stocks must crash | Check catalyst, duration, volume and rates |
| An instant news spike | The new trend is certain | See whether the move holds as volume improves |
| Futures green at 8 a.m. | A positive close is ahead | Separate gap direction from all-day return |
| Gap sharply lower | Automatic bargain | Ask whether earnings/rates alter valuations |
| Move without headline | It is noise | Check foreign equities, FX, yields and liquidity |
| Pre-open recovery | All downside risk is gone | Observe cash-market breadth and opening auction |
| Futures lead cash prices | Futures caused the move | Both may respond to shared information and arbitrage |
Signal one: size without participation
A 1% change in a deep, active book is different from the same change during a quiet holiday session. The percentage measures price; trading volume, spread and depth help describe how easily that price could change. Volume is not a guarantee of truth, and very high volume during a panic can still produce unstable prices.
Signal two: the first reaction is not the final reaction
An economic release can trigger automated orders in milliseconds. A first price jump may reflect surprise rather than a settled view of its meaning. The follow-through after related assets update—particularly Treasury yields and the dollar—often gives richer context than the first candle.
Signal three: an opening gap is not a full-day forecast
A future can correctly indicate a weak open and still fail as a guide to the day’s close. Cash-market participation adds overnight limit orders, portfolio rebalancing and discretionary trading. Calling the gap direction is a different task from predicting the next six and a half trading hours.
Signals four through seven: valuation, hidden catalysts, reversal and causality
A dip is not automatically cheap when the news changes expected earnings or interest rates. A move with no obvious headline may follow currency, bond or overseas equity repricing. A rebound before 9:30 a.m. Eastern Time does not erase the catalyst, and futures do not simply “make” stocks rise: interconnected markets transmit information through arbitrage, hedging and inventory changes.
Read the entire overnight auction, not one index
Cross-market confirmation helps distinguish a narrow move from a broad change in risk appetite. The S&P 500 represents large-cap U.S. exposure; Nasdaq-100 futures often reflect growth and technology sensitivity; Russell 2000 contracts can react differently to borrowing costs and domestic growth expectations. The Dow uses a different index construction. Divergence can be more revealing than four matching arrows.
Bond yields, the dollar and energy prices can change the likely interpretation. For example, tech-heavy futures falling as bond yields rise may point toward a discount-rate concern; oil rising sharply alongside falling stock futures might indicate inflation or geopolitical concerns. These are hypotheses to test, not one-to-one laws.
For background on keeping headline-driven decisions separate from long-term allocation, see Aperplexity’s investment strategies guide. It covers goal, risk capacity and portfolio maintenance rather than short-term predictions.
A reproducible premarket decision process
A practical process should finish with a decision that can be “do nothing.” Watching is not an instruction to trade. This sequence makes assumptions visible before capital is exposed.
- Identify the contract and expiry. Confirm whether the quote is ES, MES, NQ or another product.
- Record time and comparison baseline. Note the quote time, prior futures settlement and cash-index reference.
- State the catalyst. Distinguish confirmed data from a rumor or an unexplained move.
- Compare cross-market evidence. Inspect other index futures, Treasury yields, the dollar and major overseas markets.
- Check execution conditions. Look at spread, depth, headline calendar and whether trading is unusually thin.
- Write the invalidation point. Define what would prove the proposed trade thesis wrong.
- Choose the exposure—or skip it. Calculate potential dollar loss and compare it with capital genuinely available for risk.
There is no evidence that waiting exactly 15 or 30 minutes after the opening bell makes trades profitable. Such a pause can reduce exposure to an unusually hectic opening, but it can also miss a move. The point is to understand the trade-off rather than turn a rule of thumb into a guarantee.
Risk is set by exposure, not by the margin deposit
Calculate the dollars before considering leverage
Suppose ES is bought at 5,100 and sold at 5,060. The 40-point loss × $50 per point equals $2,000 for one contract, before commission and slippage. On MES the same 40-point movement equals $200. A stop order does not guarantee those losses are capped: fast markets can skip prices or deliver worse fills. Broker margin requirements can also change.
The key distinction is notional exposure versus the money posted as collateral. At 5,100, an ES contract represents about $255,000 of index exposure; one MES represents about $25,500. Posting a much smaller margin amount does not transform the maximum loss into the margin balance. Futures losses can exceed the initial deposit.
A commonly discussed 0.5% or 1% account-risk limit is an example of a budgeting convention, not a proven universal safe threshold. If a strategy needs a 20-point stop, the theoretical planned loss on ES is $1,000 per contract before slippage and costs. For an account that cannot absorb this without harming necessary expenses, the better choice may be fewer contracts, a smaller product or no position.
Schwab’s futures introduction and risk discussion details the leverage and account requirements. Brokerage approval and risk disclosures matter more than a headline about easy access.
Stocks, index futures and options are different tools
| Feature | Stocks / ETFs | Index futures | Long listed options |
| What you hold | Shares or fund units | Expiring derivative contract | Contractual right |
| Up-front financing | Usually full purchase; margin possible | Performance bond / futures margin | Premium paid |
| Expiration | Normally none | Yes | Yes |
| Risk profile | Market loss; margin increases risk | Leveraged losses may exceed deposit | Long option generally risks premium paid |
| Main complication | Concentration and valuation | Mark-to-market, leverage and roll | Time decay, volatility and strike |
The comparison does not mean options are always safer. Selling uncovered options introduces substantially different and potentially extreme risks. Nor does cash settlement make futures harmless. For long-term investors, broad funds and diversified holdings often better match a goal of building wealth without constant risk monitoring.
The site’s purchasing-power analysis provides another useful distinction: nominal market gains do not necessarily translate into gains in real purchasing power after inflation.
Two hypothetical mornings, two very different choices
Morning A: a shock with consistent confirmation
Suppose S&P 500 and Russell futures both decline, yields rise, the dollar strengthens and an unexpected inflation report is clearly documented. That alignment supports a risk-off interpretation, although the size and duration of the selloff remain unknowable. A disciplined investor might review equity exposure and risk limits without placing any overnight leveraged trade.
Morning B: a thin move that reverses
Suppose futures dip 0.7% during an illiquid hour, with little movement in rates or other stock-index contracts. By the U.S. opening they recover most of the drop. The initial headline “stocks set to plunge” would have overstated what the available evidence could support. This example illustrates uncertainty; it is not a measured backtest or a claim about usual reversal rates.
Both situations call for context, but neither produces a mechanical buy or sell instruction. Market reading improves when it distinguishes a plausible explanation from evidence of a repeatable edge.
The Future of Stock Futures in 2027
The strongest evidence-based direction is greater granularity in equity exposure, rather than a promise of more accurate overnight forecasting. CME’s 2026 educational material discusses new equity-factor products, while its product documentation also describes smaller index contracts. These developments may give market participants more precise tools for hedging index size, factor exposure and contract notional value.
But product choice creates its own cost: each contract may have different liquidity, tick size and spread. A small contract is not automatically economical if poor liquidity raises execution costs. Any potential 2027 rollout, adoption rate or market-share outcome remains uncertain. Traders should verify exchange specifications and actual observed volume rather than assume every new product will become liquid.
A parallel shift is the speed at which global data reaches prices. Faster dissemination may shorten the window between a public report and its immediate futures reaction, but that does not establish that a retail trader can profit from the reaction. The future advantage for ordinary readers is likely to be better interpretation and controls, not faster guessing.
Key Takeaways
- Futures are live prices for exposure, not reliable forecasts of the stock market’s eventual close.
- Contract expiry, fair value and the comparison baseline can change the meaning of a displayed percentage.
- Volume, depth and other markets provide important context for overnight moves.
- An opening gap and a profitable trade are different outcomes.
- Dollar exposure is the contract multiplier times index movement; initial margin is not the loss ceiling.
- No trade is a legitimate result of a premarket checklist.
Conclusion
The biggest mistake with stock futures is not misunderstanding the definition. It is asking a quoted number to answer more questions than it can. A price can show that investors became more defensive overnight. It cannot reveal how far the market will travel once cash trading starts, whether a move will reverse, or what any individual trader should risk.
A better method starts with the exact contract and its prior settlement, adjusts the comparison to the cash index for fair value, identifies the catalyst and checks whether liquidity and other markets support the story. Then it translates a contemplated position into actual dollars at risk, including the possibility of a worse-than-expected exit.
This process will not remove uncertainty. It makes that uncertainty visible, which is a more durable advantage than treating a green or red futures screen as a trading instruction. For many investors, the appropriate response is to learn what the market is pricing, preserve an existing long-term plan and avoid adding leverage merely because the overnight headline sounds decisive.
Frequently Asked Questions
What are stock futures?
They are exchange-traded derivative contracts linked to an asset or stock index and a specified expiration. Market-news references usually mean index futures, including the S&P 500 and Nasdaq-100. They do not give the holder ownership of index constituents.
Do stock market futures predict the opening bell?
They may indicate the direction and approximate scale of overnight equity repricing, but the result is not certain. News, liquidity and order flow can change between the quote and the cash-market open.
Why do S&P 500 futures move after hours?
They trade through much of the overnight period while investors react to overseas markets, earnings, economic data, monetary policy and news. Contract-specific trading hours and exchange maintenance breaks apply.
What does fair value mean for index futures?
It is a model-based futures price derived from the cash index, financing costs and expected dividends through expiration. Actual quotes can differ because of supply, demand and trading frictions.
How much money is needed to trade futures?
It depends on the specific contract, broker, prevailing margin requirement, fees and account approval. Margin is not the full capital at risk; a trader should also be able to absorb possible losses beyond the initial deposit.
Are Micro E-mini futures safe for beginners?
They have smaller dollar exposure per index point than E-mini contracts, but still involve leverage, volatility and potential margin calls. Smaller size changes the exposure; it does not guarantee safety.
What is the difference between single-stock and index futures?
Single-stock futures reference an individual share and have market-specific availability and rules. Index futures reference a basket benchmark and commonly use cash settlement; they are the contracts most often discussed in U.S. premarket headlines.
Methodology
This guide was developed by comparing publicly available explainers and exchange/brokerage educational documentation available in October 2026. Primary validation relied on CME Group’s fair-value and index-contract material and Charles Schwab’s futures descriptions; examples were independently calculated from stated hypothetical assumptions. No live trading test, proprietary market dataset, return forecast or predictive backtest was performed. Some broker requirements and exchange specifications may change after publication. Reader interpretation should be distinguished from personalized investment advice.
References
CME Group. (n.d.). Calculating fair value. https://www.cmegroup.com/trading/equity-index/fairvalue.html
CME Group. (n.d.). E-mini S&P 500 futures overview. https://www.cmegroup.com/markets/equities/sp/e-mini-sandp500.html
Charles Schwab. (n.d.). What are futures contracts? https://international.schwab.com/investment-products/what-are-futures-contracts
Charles Schwab. (2026, September 28). Investing basics: Futures. https://www.schwabworkplaceservices.com/story/investing-basics-futures
CME Group. (2026). Navigating 2026 and beyond with new E-mini equity factor futures. https://www.cmegroup.com/articles/2026/navigating-2026-and-beyond-with-new-e-mini-equity-factor-futures.html
-
 Technology2 months ago
Hitomi la in 2026: Domain Status, Safety and Risks
-

 Technology1 month ago
Scrolller in 2026: How It Works, Risks and Alternatives
-

 General2 months ago
Voozon.com: What It Is and How the Platform Works
-

 Technology2 months ago
ThomsonKids.com: Website Guide, Topics & Trust Check
-

 Business2 months ago
incabizgrowth.com Review: Content, Trust & Use
-
 Technology1 month ago
Filetype:pdf Windows Update: Find Better Microsoft Guides
-

 General1 month ago
Elizabeth Fraley Kinder Ready Court Case: What the Public Record Supports
-

 Technology2 months ago
thesindi com Review: What TheSindi.com Really Offers