Business
Inventory Management Systems 2026: What Actually Works

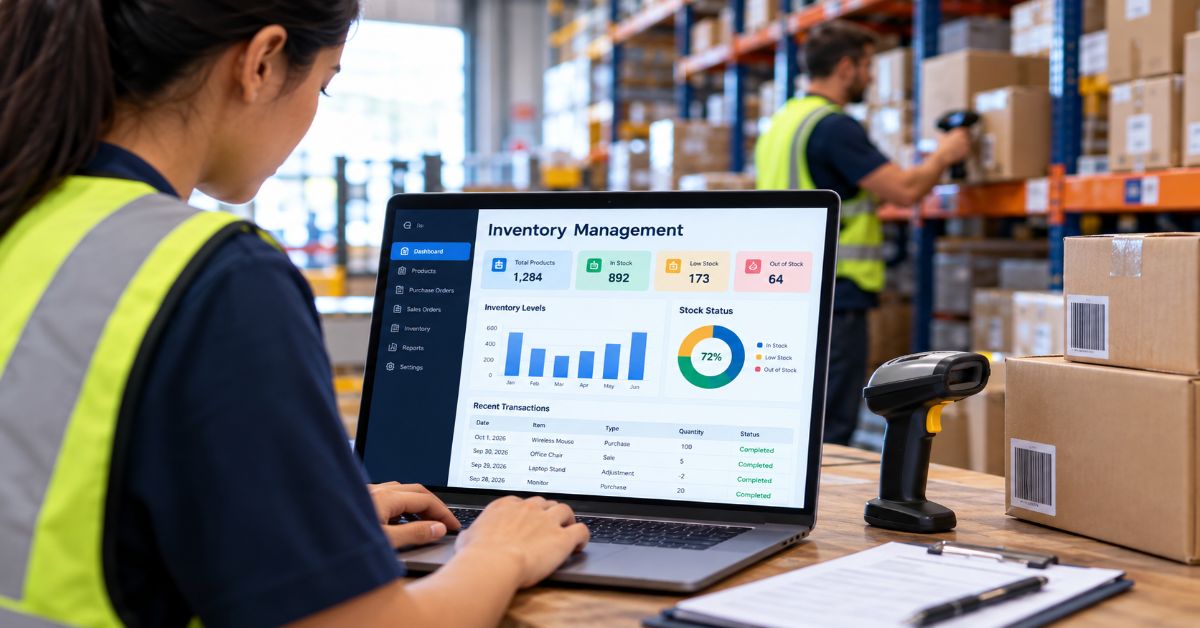
Inventory management systems work when they make physical stock, digital records, and replenishment decisions agree—and the biggest 2026 risk is buying more automation before fixing the data and operating rules underneath it. A recent Capterra buyer analysis found that 35% of businesses in its sample still used manual inventory methods and another 25% relied on spreadsheets, which means the market is not simply choosing between advanced platforms; many teams are still trying to cross the gap from informal tracking to dependable control.
Most ranking guides answer the obvious questions: what an inventory system is, which features it has, which software is popular, and whether a business should use periodic or perpetual tracking. Those answers are useful, but they leave out the harder question: why do stockouts, overstocks, phantom inventory, and bad purchase orders continue after a company has already bought software?
The answer is that inventory is a system problem. Software records events, but people define item masters, receive goods, scan locations, approve adjustments, set service targets, override forecasts, and decide how exceptions are handled. The most effective design therefore combines technology with operating policy. This guide explains the system architecture, selection logic, segmentation methods, behavioral traps, traceability standards, implementation sequence, and emerging tools that matter now—and the conditions under which each one adds value.
The Real Job: Creating a Trusted Inventory State
Five Questions the System Must Answer
An inventory system should answer five questions without argument: what item exists, how much is available, where it is, what state it is in, and what committed or incoming transactions will change that state. If any one of those fields is unreliable, the visible “on hand” number can become misleading.
Inventory as a Control Loop
That is why an inventory management system is better understood as a control loop than a database. A physical event happens—receipt, move, pick, shipment, return, scrap, production issue, or count. The event is captured. Business rules update the inventory state. The system compares that state with demand and policy. It then triggers a decision such as replenish, transfer, expedite, hold, or investigate.
Where Integration Breaks Inventory Truth
This control-loop view also explains why integration quality matters. Inventory may be correct inside one application and still be wrong for the customer if ecommerce reservations, warehouse picks, ERP receipts, or returns arrive late. The same principle appears in ETL process optimization: retries, idempotent writes, deterministic keys, and checkpoints are not abstract data-engineering concerns when duplicated or delayed events can create false stock.
| Layer | What must be true | Typical failure | Control that fixes it |
| Identity | Each sellable or traceable unit has a stable identifier | Duplicate SKUs, reused barcodes, ambiguous pack sizes | Master-data governance; GS1-compatible identifiers where applicable |
| Capture | Physical movement becomes a digital event at the right time | Receiving later from paper notes; unscanned bin moves | Point-of-work scanning, mobile workflows, RFID where justified |
| State | Available, reserved, damaged, quarantined, in-transit and on-order are distinct | One “quantity” field hides unusable stock | Inventory status model and reservation rules |
| Policy | Reorder and safety-stock rules match item economics and variability | One formula for every SKU | Segmentation and service-level policies |
| Feedback | The system learns from count errors and exceptions | Adjustments hide root causes | Cycle counts, reason codes, exception ownership |
Choose the System Type by Operational Complexity
The wrong selection question is “Which platform has the most features?” The useful question is “Which operational complexity are we paying to manage?” A simple retailer with one location has a different control problem from a manufacturer with bills of material, lot genealogy, work-in-process, and supplier lead-time variability.
| System pattern | Best fit | Strength | Main limitation |
| Spreadsheet / manual register | Very small catalog, low transaction volume, one owner | Low cost and easy to change | Weak concurrency, audit trail, controls, and scalability |
| POS or ecommerce-led inventory | Small retail and direct-to-consumer operations | Sales and stock stay closely connected | Can become weak for purchasing, multi-warehouse, manufacturing, or complex returns |
| Standalone cloud IMS | Growing multi-channel businesses | Purchasing, stock, locations, transfers, reorder rules | Integration quality becomes critical as finance and fulfillment expand |
| WMS-led control | High-throughput warehouse operations | Bin execution, wave/pick/pack, scanning, labor workflows | May need a separate planning/financial system |
| ERP inventory module | Multi-entity or process-heavy businesses | Finance, procurement, manufacturing, and stock share one transaction backbone | Implementation and configuration complexity; can be heavy for simple operations |
Inventory Management vs. Warehouse Execution
A business should also separate “inventory management” from “warehouse execution.” An IMS is concerned with stock state and replenishment; a WMS goes deeper into directed put-away, picking, packing, task allocation, and warehouse movement. An ERP connects inventory to finance, procurement, manufacturing, and enterprise controls. One platform can contain all three, but the capabilities are not the same.
Architecture and Integration Fit
Architecture choices become especially important when a company connects several specialist systems. The lesson from microservices architecture applies here: independent services are valuable only when the business can support clear contracts, owned data, observable failures, and recovery. Splitting inventory across many apps without those controls can turn “best of breed” into reconciliation work.
The Human Factor Most Guides Skip
Inventory policies look mathematical, but the actual ordering process is behavioral. Controlled supply-chain experiments have repeatedly found that people create order variability even when classic informational causes are reduced. Research on multi-echelon inventory decisions has shown that the bullwhip effect can persist despite information sharing, while experiments under uncertain lead times found that greater uncertainty changed inventory behavior and increased order variance.
Three Ordering Biases to Design Around
Three practical biases show up in real operations. First, demand chasing: a recent sales spike feels more important than the longer demand history. Second, anchoring: a prior order quantity, min/max setting, or planner habit becomes the default even after the environment changes. Third, delay neglect: people react to the visible shortage without fully accounting for purchase orders, production, or transfers already in the pipeline.
Design for Imperfect Decisions
A strong system should not assume perfect decision-makers. It should show inventory position rather than only on-hand quantity, surface lead-time uncertainty, require reason codes for overrides, and separate routine replenishment from exception decisions. The goal is not to remove judgment. It is to make the assumptions behind judgment visible.
Move Beyond ABC: Segment by Value and Variability
ABC classification is useful because not every SKU deserves the same attention. But annual consumption value alone misses one of the most important planning differences: predictability. Pairing ABC with XYZ demand variability produces a policy matrix that is more actionable.
Using Coefficient of Variation
A common statistical starting point is the coefficient of variation: CV = standard deviation of demand ÷ mean demand. Lower CV generally signals steadier demand; higher CV signals more variable demand. The exact X/Y/Z thresholds should be calibrated to the business rather than copied blindly from a generic table.
| Class example | Interpretation | Policy direction |
| AX | High value, stable demand | Tight service target, frequent review, forecast-driven replenishment |
| AZ | High value, erratic demand | Manager review, scenario-based buffers, supplier flexibility, avoid automatic overreaction |
| BX/BY | Medium value, stable-to-variable demand | Standard automated replenishment with exception thresholds |
| CZ | Low value, erratic demand | Simplify control; consider order-on-demand, minimum presentation stock, or rationalization |
| Vital + scarce (VED/SDE overlay) | Operationally critical and hard to source | Dual sourcing, risk-based safety stock, escalation regardless of annual spend |
Turn Segments Into Different Policies
This is one place where “just-right” inventory is more useful than a simplistic lean-versus-buffer argument. A high-value, predictable item may deserve a different buffer than a low-value, intermittent part with a six-month supplier lead time but catastrophic downtime impact. The system should encode that distinction.
Accuracy Starts at Identification and Capture
A forecasting engine cannot fix a warehouse that records the wrong item in the wrong location. Accurate inventory starts with identity and capture. GS1 describes barcodes as standardized carriers for identifiers such as products, shipments, locations, serial numbers, lots, and dates, while its RFID standards allow unique Electronic Product Codes to be captured without line-of-sight and at high rates.
RFID, Barcodes, and Point-of-Work Capture
That matters because better capture technology should remove a specific source of error. GS1’s RFID standards describe UHF passive RAIN RFID as a method that can capture unique identifiers at distance and without line-of-sight. This can be valuable for high-volume counts, apparel, reusable assets, and other workflows where individual scanning is the bottleneck. It is not automatically superior to barcodes: tag cost, read environment, item materials, antenna placement, middleware, and exception handling determine whether the economics work.
Offline Workflows in Real Warehouses
Offline-first mobile design is another under-discussed requirement. Warehouses often have dead zones, metal racks, cold rooms, yards, and temporary work areas where a cloud-only transaction can fail at the exact point stock moves. A well-designed mobile workflow can queue scans locally, preserve event order, prevent duplicate submission, and reconcile safely when the connection returns.
Database Reliability Still Matters
The database underneath the inventory application also deserves operational attention. Slow queries, stale statistics, bad indexes, and overloaded transaction paths can turn “real time” into delayed state. The same evidence-first approach described in database optimization is useful here: identify the constrained resource, change one thing, and verify whether the inventory transaction path actually improved rather than moving the bottleneck elsewhere.
AI, Digital Twins, and Automation: Useful Only After the Basics
The 2026 inventory software market is moving toward more automation. Oracle’s current supply-chain readiness documentation, for example, lists AI-assisted inventory reservations, stockout and outbound recommendations, and automated PAR-level workflows. That direction is important, but it changes what “implementation quality” means: recommendations are only as reliable as the transaction history, master data, lead times, and business constraints supplied to them.
What a Useful Digital Twin Actually Does
A digital twin can be thought of as a continuously synchronized virtual representation of the physical inventory network. In a useful implementation, it is not a decorative 3D model. It is a state model fed by WMS, ERP, order, sensor, and transport events so planners can test scenarios before acting. The hard part is synchronization: if latency or missing events cause the twin to drift from reality, the simulation becomes confidently wrong.
Start With a Constrained Pilot
A sensible pilot therefore starts smaller than the marketing vision. Pick one warehouse zone, channel, or high-friction item family. Define which events create the twin state. Measure latency and mismatch. Run the model in parallel with the live process. Only after state fidelity is proven should the team add prediction, optimization, or scenario automation.
Where Generative AI Fits
The same skepticism should apply to generative AI. Inventory teams can use models to summarize exceptions, draft purchase-order notes, explain variance, or help query operational data, but a fluent explanation is not proof that the underlying record is correct. The verification discipline discussed in the site’s AI text detector guide carries over: automated signals are useful inputs, not substitutes for provenance, controls, and human review where consequences are material.
Traceability Changes the System Requirement
For regulated or high-risk inventory, the system is not only optimizing stock. It is proving identity, history, and custody. That changes the data model: lots, serials, expiry, supplier, transaction history, and status transitions may become mandatory rather than optional fields.
DSCSA and Electronic Traceability
The pharmaceutical example is clear. The U.S. FDA describes the Drug Supply Chain Security Act as a framework for interoperable, electronic tracing of certain prescription drugs at the package level. Current FDA material also shows that implementation still involves technology, integration, and exemption questions for some trading partners. For affected organizations, FDA DSCSA guidance makes traceability architecture a compliance requirement, not a nice-to-have analytics feature.
Where Blockchain Helps—and Where It Does Not
This is also where blockchain claims need discipline. An immutable ledger can preserve a shared event record, but it does not guarantee that the original scan was correct, that the physical item matched the identifier, or that every participant submitted events on time. If a conventional signed event store and agreed interoperability standard solve the trust problem, a blockchain layer may add complexity without adding useful control.
A 90-Day Implementation Sequence That Reduces Risk
A good rollout proves inventory truth before it scales automation. The sequence below is intentionally operational: it starts with process evidence, not software configuration screens.
Days 1–15: Establish the Truth Gap
Measure inventory accuracy by location and item family. Map every stock-changing event. Identify where transactions are delayed, skipped, duplicated, or corrected later. Freeze unnecessary SKU creation and clean units of measure, pack sizes, locations, and status codes.
Days 16–30: Define Inventory Policy
Segment SKUs by value, variability, criticality, and lead-time risk. Set ownership for reorder parameters, adjustments, cycle counts, and exceptions. Document the difference between on hand, available, reserved, quarantined, and in transit.
Days 31–60: Pilot One Closed Loop
Choose one warehouse area or channel. Connect receiving, movement, reservation, picking, shipping, and returns. Use scanning at the point of work. Reconcile daily and classify every mismatch by root cause.
Days 61–75: Stabilize Integrations
Test API, file, and event flows under retries, network loss, duplicate messages, and delayed updates. Verify finance and ecommerce reconciliation. Add monitoring for stale queues and synchronization lag.
Days 76–90: Automate Selectively
Turn on replenishment suggestions, transfer rules, forecasts, or AI assistants only after baseline accuracy is stable. Require override reasons. Compare decisions and outcomes against the prior process before expanding.
Do Not Ignore Customer-Facing Reliability
For customer-facing or browser-based inventory portals, the operational bar should include resilient releases, secure access, rollback, and observable integrations. The site’s guide to web development best practices makes the same point from the application side: quality comes from measurable release gates and reversible decisions, not a checklist of fashionable technologies.
Metrics That Reveal Whether the System Is Actually Better
Implementation teams often track login counts and feature adoption because they are easy. Inventory performance needs harder evidence. The core metrics should connect record quality, working capital, service, and execution.
| Metric | Simple definition | What it diagnoses |
| Inventory record accuracy | Correct counted records ÷ records checked | Whether system state matches physical stock |
| Stockout rate | Demand events not fulfilled from available stock ÷ demand events | Service failure and replenishment weakness |
| Inventory turnover | Cost of goods sold ÷ average inventory | How efficiently inventory supports sales; interpret by industry |
| Days inventory outstanding | Average inventory ÷ COGS × days | Capital tied up in stock |
| Count adjustment rate | Units or value adjusted ÷ units or value counted | Process-control weakness hidden by corrections |
| Replenishment override rate | Planner overrides ÷ system recommendations | Whether policy/model output is trusted and appropriate |
| Event-to-state latency | Time from physical event to trusted system update | Integration and capture delay |
The Future of Inventory Management Systems in 2027
The most credible 2027 direction is not fully autonomous inventory. It is tighter coupling between sensing, transaction systems, decision support, and human exception management. RFID and 2D identification standards continue to improve machine-readable capture; major enterprise vendors are adding AI assistance inside operational workflows; and digital-twin techniques are moving closer to live planning rather than static simulation.
Governance Becomes the Bottleneck
The limiting factor will be governance. As systems make more recommendations, companies will need clearer controls for confidence thresholds, overrides, audit trails, model drift, supplier-data quality, and who owns a wrong decision. The businesses that benefit most will probably be the ones that automate high-volume repeatable decisions while keeping unusual, high-cost, or safety-critical exceptions visible to people.
Why Simpler Systems Will Still Win
There is also a practical countertrend: simpler tools will remain competitive where operational complexity is low. A small business does not become more sophisticated by adopting enterprise software it cannot maintain. The 2027 advantage will come from matching system complexity to business complexity—and keeping the inventory state trustworthy enough that automation has something solid to work with.
Key Takeaways
- Inventory software is only one layer; identity, capture, state definitions, policy, and feedback determine whether the record can be trusted.
- System selection should follow operational complexity, not feature count. Retail, warehouse, manufacturing, and regulated traceability needs are materially different.
- ABC-XYZ and criticality overlays create better replenishment policies than one universal safety-stock rule.
- Behavioral biases can amplify order variability, so good interfaces should expose pipeline inventory, uncertainty, and override assumptions.
- RFID, AI, and digital twins can add leverage after transaction discipline is stable; before that, they can automate bad data faster.
- Implementation should prove one closed loop, stabilize integration failures, and measure accuracy before scaling automation.
- The strongest KPI set combines inventory accuracy, service, working capital, adjustment causes, override behavior, and event latency.
Conclusion
Inventory management systems are most valuable when they reduce uncertainty rather than merely digitize it. A business should be able to trace how a physical event becomes a trusted stock state, how that state drives a replenishment decision, and how exceptions feed back into better policy. If those links are weak, adding forecasting, RFID, AI, or a new ERP can make the system more complicated without making it more reliable.
The practical priority is therefore sequence. Fix item identity and status definitions. Capture movements at the point of work. Segment inventory according to value, variability, criticality, and supply risk. Stabilize integrations. Measure the accuracy gap. Then automate the repeatable decisions that have enough clean evidence behind them. That approach is less exciting than buying “autonomous” inventory software, but it is far more likely to improve service and release working capital without creating a new layer of invisible risk.
Frequently Asked Questions
What are inventory management systems?
Inventory management systems are the processes, software, data, and capture tools used to track stock quantity, location, status, movement, and replenishment. They can range from spreadsheets to standalone cloud platforms, warehouse management systems, or ERP inventory modules.
What is the difference between an inventory management system and a WMS?
An inventory management system focuses on stock state, purchasing, availability, and replenishment. A warehouse management system goes deeper into warehouse execution such as bins, put-away, picking, packing, waves, task allocation, and scanning. Some platforms combine both.
What is the best inventory management system for a small business?
There is no universal best system. A small business should choose the simplest platform that reliably supports its SKU count, sales channels, locations, purchasing, returns, and accounting integration. Paying for enterprise complexity before it is needed can increase operating friction.
How accurate should inventory records be before adding AI forecasting?
There is no single universal threshold. The important point is that forecast and replenishment automation should not be trusted until the company understands its record-error rate, root causes, event latency, and exception process. Automating on top of unknown data quality hides rather than fixes the problem.
Is RFID better than barcodes for inventory tracking?
Not automatically. RFID can capture many unique identifiers quickly and without line-of-sight, which is valuable in some high-volume workflows. Barcodes are cheaper and simpler in many environments. The right choice depends on item value, read conditions, transaction volume, tag economics, and integration requirements.
What is ABC-XYZ inventory analysis?
ABC-XYZ analysis combines item value with demand variability. ABC groups items by economic importance, while XYZ groups them by predictability. The combined matrix helps assign different review frequencies, service targets, safety-stock methods, and exception rules.
Can inventory management be fully automated?
Routine replenishment and transaction handling can be highly automated, but full autonomy is risky when demand is unusual, lead times change, suppliers fail, regulated traceability is involved, or the data is incomplete. Human exception management remains important for high-consequence decisions.
Methodology
This article was researched on October 1, 2026. I reviewed a representative high-visibility SERP sample for “inventory management systems” and close 2026 informational/commercial variants. The sample included TechRepublic, Capterra, Shopify, FreshBooks, Unleashed, TrustRadius, Software Connect, Cleverence, Codesol Technologies, and current 2026 inventory-software roundups. Search order varies by country, device, personalization, and index freshness, so this is a competitive sample rather than a permanent global top-10 ranking.
The recurring competitor structure was definition, types, features, software lists, benefits, and selection advice. I used that overlap only to identify gaps. The article structure was built independently around inventory-state trust, behavioral ordering errors, segmentation policy, capture standards, traceability, integration failure, and an accuracy-first rollout sequence.
For factual validation, priority went to GS1 standards for barcode and RFID identification, FDA material on DSCSA traceability, Capterra’s July 2026 buyer analysis, Oracle’s 2026 supply-chain release documentation, and peer-reviewed behavioral inventory experiments. I excluded several attractive percentage claims from the supplied brief because I could not verify them to a sufficiently strong primary or original source during this research pass.
This article was drafted with AI assistance and reviewed by a human editor before publishing. All data, citations, and claims have been independently verified against primary sources.
References
- Ancarani, A., Di Mauro, C., & D’Urso, D. (2013). A human experiment on inventory decisions under supply uncertainty. International Journal of Production Economics, 142(1), 61–73. https://doi.org/10.1016/j.ijpe.2012.09.001
- Burgess, L. (2026, July 6). Top 7 inventory management systems: Expert picks based on 1,600+ advisor interactions. Capterra.
- GS1. (2025). EPC Tag Data Standard (TDS) 2.2. GS1.
- GS1. (n.d.). RFID. GS1 Standards.
- Oracle. (2026). Oracle Fusion Cloud Supply Chain & Manufacturing 26C: Inventory Management feature summary.
- U.S. Food and Drug Administration. (2026). Drug Supply Chain Security Act (DSCSA).
- Zhao, Y., & Zhao, X. (2015). On human decision behavior in multi-echelon inventory management. International Journal of Production Economics, 161, 116–128. https://doi.org/10.1016/j.ijpe.2014.12.005

A research dossier for target company decisions is useful only when it can prevent a specific mistake: buying a weak business, pitching the wrong buyer, choosing a risky vendor, or accepting a misleading job offer. A 40-page profile can look thorough while missing the one unresolved fact that should stop the deal.
The better approach starts with a decision and works backward. Every meaningful statement must answer four questions: where is the evidence, when was it checked, how strongly does it support the claim, and what decision would change if the claim were wrong? That method keeps company research from turning into a collection of screenshots, press releases, and unattributed estimates.
Recent guides offer long lists of company information and reusable templates. Those are useful as inventories, but even an evidence log can fail if nobody records conflicting claims or knows when old information needs refreshing. This guide therefore builds a practical decision system around seven layers, a source hierarchy, a copy-ready template, a fast-screen option, and a sample recommendation. The examples are illustrative, not reports about actual companies.
Public-company disclosures, trademarks, hiring signals, customer complaints, and financial statements have different evidentiary value. The skill is not collecting all of them. It is recognizing which ones matter for the decision in front of the reader, while documenting what remains unknown.
Start With the Decision, Not the Company Profile
A dossier is a working intelligence file, not necessarily a polished report. Write the intended decision and the conditions for a yes or no before opening the first browser tab. Otherwise, researchers can spend hours finding facts that do not affect the outcome.
| Decision | Question to resolve | Highest-value evidence |
| Sales | Is there a fit and who can authorize a purchase? | Product stack, pain signals, buyer map, recent initiatives |
| Investment | Can this firm compound value at an acceptable risk? | Financial filings, cash flows, customer concentration, valuation |
| Recruiting | Is the role and employer stable enough? | Role history, management turnover, financial position |
| Partnership | Can this partner deliver without conflicting incentives? | Customer references, channel conflicts, contracts, legal status |
| Acquisition | What could impair value or integration? | Ownership, liabilities, contracts, personnel dependencies |
| Vendor vetting | Can key service and security claims be corroborated? | Legal identity, compliance evidence, service history, references |
Write the stop condition first
Consider a vendor review: “Pause procurement if the legal contracting entity cannot be verified or if a material security claim cannot be documented.” That threshold makes the investigation smaller and sharper. It also stops weak public signals from being mistaken for formal diligence.
The Seven-Layer Decision-First Dossier
Layer 1: Prove the legal entity
Map brand name → official website → contracting or registered legal name → appropriate business registry. Confirm jurisdiction, corporate status, and parent or subsidiary relationships where the records allow. A brand may belong to several legal entities, and a similar company name can point to the wrong business. Registered-agent details or a certificate of good standing should not be read as proof of solvency.
The key output is an entity-match statement: the records support this business identity, or the match remains uncertain. Use the second conclusion rather than quietly assuming the brand and legal entity are identical.
Layer 2: Trace how money enters the business
Describe the economic chain: customer → problem → offering → payment mechanism → renewal or repeat purchase → dependency. For subscription software, ask whether revenue depends on usage, seat counts, one large account, or a single marketplace. For manufacturers, examine buyers, order cycles, service agreements, and essential suppliers. Private-company revenue is often unavailable; pricing pages and customer logos do not establish realized revenue.
For perspective on why revenue must be tested against actual cost structure, compare the site’s Airbnb profit-margin break-even analysis; the broader lesson is that sales volume alone does not establish economic resilience.
Layer 3: Triangulate four kinds of signals
| Signal | Useful records | Interpretation limit |
| Money | SEC filings, financing disclosures, debt records | A financing round does not prove profitability |
| Hiring | Open roles, archived roles, executive changes | Hiring does not establish expansion or financial strength |
| Customers | Case studies, complaints, references, renewals | Testimonials are curated; reviews are self-selected |
| Legal and intellectual property | Court dockets, regulators, trademarks, patents | A filing or application is not proof of misconduct or success |
A conflict between signals is a reason to investigate, not to announce a scandal. A firm might report rising revenue while reducing headcount because it automated work or changed product lines. Record competing explanations and demand evidence before choosing one.
For public U.S. issuers, the SEC EDGAR filing search provides primary company disclosures. The records are a starting point for checking reported financial and risk statements, not independent validation of every management projection.
Layer 4: Grade the evidence, not the company
| Grade | Meaning | Use in decisions |
| A | Direct primary record supports the narrowly stated claim | Can support key findings, with scope and date |
| B | Credible independently reported or corroborated fact | Use with attribution and caveats |
| C | Company statement without independent confirmation | Label as self-reported |
| D | Reasoned inference from indirect observations | Separate from confirmed facts |
| E | Rumor, anonymous assertion, or untraceable claim | Do not use to justify a decision |
This A–E scale is an editorial heuristic, not an audited probability model. Grade each claim individually. An official company brochure is a primary source for “the company says X,” but it is not automatically independent proof that X is true. A first-party financial filing is authoritative evidence of what was disclosed; auditors, accounting standards, reporting periods, and subsequent restatements still matter.
Layer 5: Keep a contradiction log
| Claim | Counter-signal | Likely explanation to test | Status |
| “Rapid expansion” (company statement) | Fewer active vacancies | Growth might be in revenue, not staff | Open; C |
| “Enterprise only” (marketing) | SMB price tiers advertised | Different positioning by segment | Open; C |
| “Stable leadership” (recruiter) | Multiple recent executive departures | Different dates or incomplete claim | Escalate; D |
Classify conflicts as timing differences, mismatched definitions, material disagreements, or audience-dependent positioning. A contradiction is unresolved until the dossier includes an explanation, supporting evidence, and the implication for the decision. Never manufacture numerical trends from a small sample of job postings.
Layer 6: Give evidence an expiry date
A date checked is not enough. Add “review due” to every important fact. Suggested intervals, adjusted to risk: recruitment and product signals every 30–60 days; customer reviews every quarter; leadership every three to six months; legal status every six to twelve months; financial claims after the next filing or financing event. Material litigation and enforcement risks may warrant a fresh check immediately before signing. These are operating defaults, not regulatory requirements.
Layer 7: Publish a one-page decision memo
Finish with one of four calls: proceed, proceed with conditions, pause pending evidence, or do not proceed. Name three reasons, the largest outstanding risk, what would overturn the recommendation, an owner for the next check, and a deadline. Without this final page, a dossier remains a research archive.
Where to Find Records Others Miss
Start with the entity registry and official disclosures. For a U.S. publicly reporting company, EDGAR can show periodic reports, major risk factors, executive information, and exhibit disclosures. Trademark records and patent information can reveal applications or registered rights but rarely show commercial success. Courts and enforcement databases require special care: allegations are not findings.
The USPTO trademark search database provides application and registration records. Search multiple name variations and inspect ownership and status before linking an IP record to a business.
Local business journals, archived website pricing pages, conference speaker lists, app-update histories, procurement documents, and archived job ads can add direction and timing. Ask what each source can actually prove. An executive speaking at a conference establishes appearance on a program, not a partnership or commercial relationship.
When competitor claims involve intellectual property, the site’s AI-generated work and intellectual property explainer offers related context about why ownership claims need careful documentation.
A Copy-Ready Target Company Research Dossier Template
Copy the fields below into a spreadsheet or working document. Enter “not verified” wherever evidence is missing rather than supplying an estimate.
Decision brief
Target company; decision owner; decision and deadline; stop conditions; evidence threshold.
Identity
Brand name; legal name; registration jurisdiction; status; parent/subsidiaries; official domain; registry reference.
Business model
Core offer; customer groups; monetization; channels; customer concentration; supply or platform dependency.
Financial and operating signals
Filings or funding; cash/debt evidence; hiring changes; launches; customer evidence; period covered.
People and position
Leadership; relevant buyer; tenure; competitors; pricing position; strategic dependence.
Claim ledger
Claim; exact source; source date; checked date; grade A–E; review due; action relevance.
Conflicts and open questions
Conflicting claims; type of discrepancy; impact; source needed; research owner; due date.
Decision memo
Recommendation; three reasons; largest risk; conditions; evidence that would change the call; next action.
A Worked Example: Evaluating a Software Partner
Illustrative scenario only: a midsize company is considering a workflow software partner. The prospective partner lists major customer logos and advertises rapid deployment. A registry confirms the legal entity (A for identity), but public case studies only establish that the company claims named customer relationships (C until confirmed). Open engineering roles suggest continuing product investment (D for growth inference). A former customer review flags integrations as difficult (E without independent corroboration).
The resulting decision is “proceed with conditions”: ask for two current customer references, a written implementation plan, the contracting entity’s details, and operational security evidence relevant to the service. The dossier does not infer revenue, profitability, or platform reliability from logos and hiring. This is the crucial distinction between collecting signals and judging them.
The practical discipline resembles turning customer feedback into action rather than assuming that repeated opinions are reliable causal evidence.
Fast Screen or Deep Diligence?
A 15-minute first pass
In a quick sales or recruiting screen, record identity, decision objective, two high-value signals, two unknowns, and the next verification step. Keep the output to one page. It should decide whether the company deserves more research, not whether it is definitively safe.
A five-hour focused investigation
For a meaningful partnership review, allocate time to entity matching, primary records, revenue dependencies, customers, legal risks, contradiction checks, and a short memo. Five hours is an illustrative planning budget, not enough for a regulated procurement approval, audited valuation, or full M&A diligence. Escalate material issues to qualified legal, financial, or security reviewers.
Researching Private Companies Without Public Financials
Private entities may disclose little financial detail. Do not infer annual revenue from employee counts, website traffic, or investment announcements without a defensible model and clearly marked assumptions. Focus instead on observable operating claims and request evidence directly: financial references, customer retention support, signed contracts, supplier concentration, or management explanations. The refusal to provide an appropriate document can be relevant to risk, but confidentiality can also explain legitimate limits.
Keep alternative interpretations visible. A new patent application may reflect exploration rather than a product roadmap. A leadership change may be routine rather than a warning. An isolated negative review should prompt questions, not a finding. When risk is high and evidence weak, a conditional or paused decision is more defensible than a forced yes-or-no verdict.
Using AI Without Inventing Company Facts
Use AI to structure questions and extract information from documents that have already been collected. Do not rely on an unsourced AI-generated company summary as the evidentiary foundation. Ask the system for exact supporting language, document section, period, and gaps, then check those excerpts against the originals.
Copy-ready prompt: “Using only the attached records, identify each material financial, legal, leadership, operational, and customer claim. For each item, provide an exact supporting excerpt, page or section, evidence date, suggested confidence grade, and an additional independent check. Mark missing or contradictory information explicitly. Do not infer undisclosed revenue, customers, legal outcomes, or causal relationships.”
For a related discussion of privacy risks when compiling personal data, read the fast people-search accuracy and privacy guide.
Decision-Ready Quality Check
Score the dossier one point for each item completed: named decision; stop condition; verified entity; source for each material claim; reporting period; claim grade; contradiction review; review-due dates; stated unknowns; signed-off next action. A 9/10 score can still hide a fatal missing fact; treat the checklist as a completeness aid, never as a safety certification.
The Future of Target Company Dossiers in 2027
Company research is likely to become faster at extracting text from filings, tracking website changes, and spotting mismatches across records. The operational challenge will shift toward source identity, document versions, data rights, and proof that an apparent contradiction is real. Automated alerts can make evidence fresher, but also create false urgency when routine changes look dramatic.
The likely advantage in 2027 is not a longer data room generated by AI. It is a narrower chain from claim to primary record to decision: one that makes uncertainties visible and supports accountable review. That forecast is analytical, not a verified projection of adoption rates or tooling capabilities. Organizations should audit AI-assisted extraction and set review cycles according to materiality, not assume automation replaces diligence.
Key Takeaways
- The decision and stop conditions belong on page one.
- An entity match prevents researching a brand while contracting with a different company.
- A–E grades describe the evidence behind individual claims, not an overall trust score.
- Contradictions and review-due dates deserve dedicated fields.
- Public filings and trademark records have specific limits; they do not validate every marketing claim.
- The useful final artifact is a conditional decision with named next checks.
Conclusion
A target-company dossier succeeds when it reduces uncertainty around a real choice. Gathering every available fact is neither possible nor necessary. A better document proves whom the research concerns, isolates what would alter the decision, gives each material claim a defensible source, and exposes conflicts that an attractive company profile would overlook.
The greatest risk is false certainty. A public filing can be dated; a private firm may not disclose its numbers; a customer review may reflect only one experience. Naming those limitations is a sign of disciplined research, not a weakness. A decision-first framework makes it possible to proceed conditionally, ask for the right documents, or stop before an avoidable commitment. Keep the dossier short enough to use, detailed enough to audit, and current enough to trust.
Frequently Asked Questions
What is a target company research dossier?
It is an evidence-backed record of a company created for a defined decision. Unlike a general profile, it includes a claim-source trail, confidence labels, timestamps, contradictions, unresolved questions, and a recommended next step.
Is a company research dossier template the same as due diligence?
No. A template organizes work; due diligence is the substantive verification appropriate to the decision. Complex acquisitions, regulated vendors, and financial commitments can require professional legal, technical, financial, or compliance reviews.
Can a dossier rely only on public records?
Yes for some initial screens, but not for conclusions that require private financials, references, contracts, or internal controls. Mark unavailable information and make further review a condition of moving ahead.
How often should a business research dossier be updated?
Update material facts when new disclosures, leadership changes, operational signals, or legal events occur. Pre-set review dates help, but the expected decision date and consequence of error should determine urgency.
How should conflicting company information be handled?
Preserve both claims and their original dates. Check whether they refer to different entities, periods, or definitions, then seek stronger evidence. If the disagreement remains material, present it as unresolved.
What belongs in a vendor due diligence dossier?
Verify the contracting entity, service scope, customer references, security and compliance evidence, support capacity, financial dependencies, and important legal risks. The necessary depth depends on service criticality and access to systems or data.
Methodology
This guide draws on publicly accessible primary U.S. government search resources and a comparative review of current company-dossier guides. Its confidence grades, freshness intervals, quality checklist, and examples are proposed editorial methods, not empirically validated scoring systems. The sample business is fictional. No confidential company data or first-hand testing was used. References below should be checked again during human editorial review.
This article was drafted with AI assistance. Human editorial review and independent verification of all claims, citations, and links are required before publication. Do not represent those steps as completed unless they are actually completed.
References
U.S. Securities and Exchange Commission. (n.d.). Search filings. https://www.sec.gov/search-filings
United States Patent and Trademark Office. (n.d.). Trademark search. https://tmsearch.uspto.gov/
Google. (n.d.). Searching — Google Patents Help. https://support.google.com/faqs/answer/7049475?hl=en
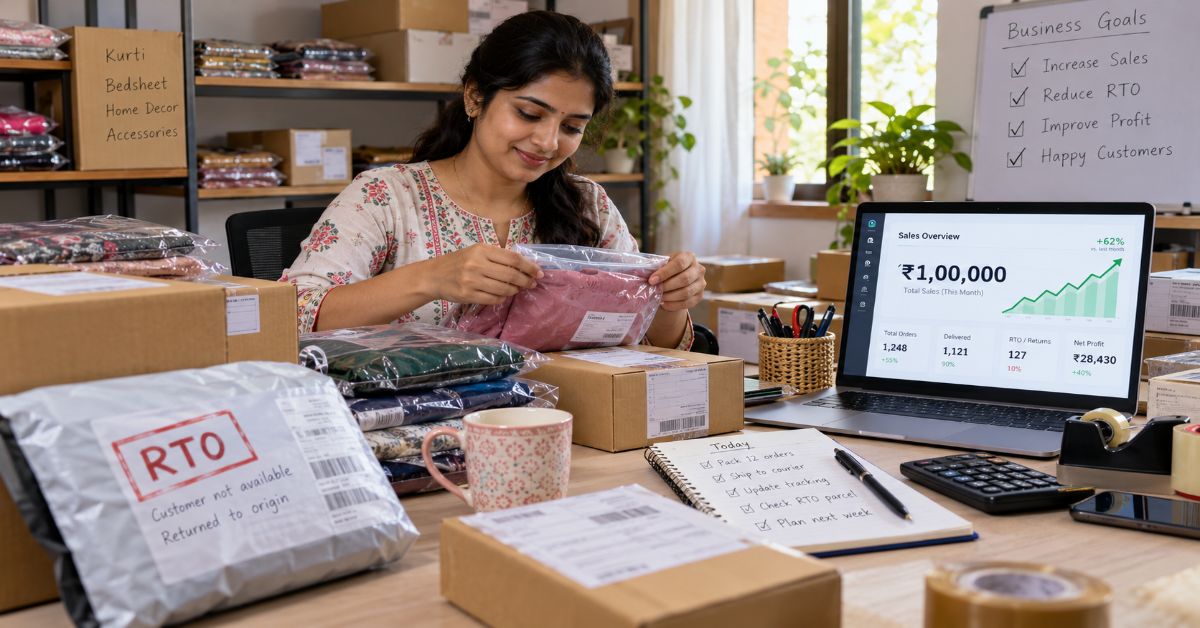
A Meesho Seller can reach ₹1 lakh in monthly sales and still make very little money: the gap is usually hidden in shipping, returned parcels, packaging, paid visibility and the cost of inventory that does not sell. Meesho advertises zero commission and a seven-day payment cycle after delivery, but neither promise makes a ₹399 order automatically profitable (Meesho, n.d.).
The useful question is not merely how to sell on Meesho. It is how to choose products that people actually accept, set prices that absorb predictable failures, and identify catalogs worth replenishing. Registration matters, but most sellers can finish it long before they understand their real order economics.
This guide uses a model ₹399 product to show the difference between gross revenue and contribution. It then proposes a return-to-origin (RTO) diagnostic, a product-selection screen, and a 30-day operating rhythm. The target of ₹1 lakh refers to monthly delivered merchandise sales, not guaranteed earnings. Every price, rate and proposed margin threshold in the worked examples is illustrative; seller-specific statements must be checked against the live Supplier Panel and settlement reports.
The approach is intentionally narrow. Instead of uploading hundreds of unrelated items or buying ads before a product is proven, start with a buyer problem, track a small group of SKUs and fix the cause of losses. A repeatable catalog is built from evidence, not from an impressive listing count.
The Profit Equation That Zero Commission Does Not Solve
Calculate contribution per delivered order
Net contribution per delivered order = realized selling price − product cost − packaging − allocated forward logistics − expected return/RTO loss − advertising − other transaction costs. This is a management estimate, not an income-tax profit figure; add storage, staff, damaged inventory, taxes and fixed overhead to estimate business profit. Do not double-count shipping if the settlement already includes it.
Meesho’s official supplier guidance describes zero commission, catalog management and a payment cycle tied to delivered orders. Its price-recommendation and quality tools can help sellers evaluate competitive pricing and customer return reasons (Meesho, n.d.). The actual applicable fees and deductions remain seller- and transaction-specific.
| Illustrative ₹399 order | Amount (₹) | Interpretation |
| Realized selling price | 399 | Assumes delivered and paid |
| Product landed cost | 180 | Include supplier freight |
| Packaging | 15 | Outer and inner protection |
| Shipping/logistics allocation | 60 | Example only; confirm settlement |
| Expected returns/RTO loss | 35 | Average provision across all orders |
| Promotion allocation | 20 | Spend divided by attributed deliveries |
| Illustrative contribution | 89 | 22.3% of realized price |
The ₹89 result is not a verified average Meesho seller profit. It is a worked calculation: 399 − 180 − 15 − 60 − 35 − 20 = 89. A seller who omits the ₹35 return reserve would overstate this example’s contribution by nearly 40%.
Set a break-even return threshold before setting an ad budget
Suppose a product yields ₹124 contribution before the expected returns reserve, and each failed shipment creates ₹175 in unrecoverable cost. A simplified loss-only threshold is 124 ÷ (124 + 175) = about 41.5% failed orders. That is not a safe target: it ignores fixed overhead, cash delays, damaged stock and customer returns after delivery. A business should set a much lower internal intervention threshold based on its own recent SKU history.
For better control, separate completed deliveries, pre-delivery RTO, and post-delivery returns. A refund after delivery may require product inspection and reverse movement; a COD refusal may never become a sale. They must not share the same denominator when calculating profit.
RTO Is a Diagnosis, Not Just a Percentage
Track the reason alongside the SKU
Return-to-origin means a shipment comes back before successful delivery. Failed customer contact, an inaccurate address, refusal on delivery and delivery attempts can contribute. A customer-initiated return after delivery is a separate event. The same product may suffer both, but each needs a different operational fix.
| Track per SKU | Calculation or field | Management use |
| Dispatched orders | Count of parcels sent | Defines shipment cohort |
| RTO rate | RTO parcels ÷ dispatched parcels | Detect delivery failure |
| Post-delivery return rate | Returned deliveries ÷ delivered orders | Detect expectation/quality gap |
| Reason code | Address / refusal / fit / damage / other | Choose the remedy |
| Net ₹ contribution | Receipts − all allocable costs | Decide whether to scale |
| Packaging version | Bag A / carton B | Test damage-related interventions |
A seller with 50 dispatched units and 11 RTOs has a 22% RTO rate. If revised listing details and delivery practices produce 9 RTOs out of the next 100 dispatched, that is 9%—but it is a hypothetical illustration, not a documented case study. Different time periods, customer mixes and courier conditions can create apparent improvements; compare like with like.
Apply controls that match the failure mode
For wrong-product expectations, replace edited or deceptive images with accurate photos, show dimensions and colors clearly, and write material and fit details in plain language. For apparel, include garment measurements and a model-size reference when available. For breakage, improve inner cushioning, outer packaging and tamper-evident seals. For inventory mismatch, reconcile stock before promising dispatch.
For permitted customer communications, follow Meesho’s actual messaging workflow and privacy rules. Do not assume an independent seller can call or WhatsApp every buyer: platform restrictions and access to customer details may prevent it. Instead, use in-panel support and fulfillment tools where available, and escalate recurring delivery failures with order-level evidence.
A disciplined returns investigation resembles a customer-experience feedback loop: customer feedback surveys tied to concrete decisions can help distinguish a vague complaint from a fixable packaging, sizing or delivery problem.
Design a Catalog Around One Buying Job
Why 20–40 related SKUs can beat 500 random ones
A tight catalog is easier to photograph accurately, pack consistently and measure. The 20–40-SKU starting range is a proposed pilot size, not an official platform recommendation. It could mean daily-wear cotton kurtis within a clear size band, practical kitchen-storage sets, or affordable desk-organizing items. Start with a customer use case and then test colors, sizes, bundles and price points without creating uncontrolled variation.
The catalog ladder below is a decision tool. “Premium” does not mean luxury; it might simply mean a better material or useful multi-pack. Margin ranges should be earned from actual sales rather than imposed as promises.
| SKU role | Purpose | Decision rule |
| Entry / traffic | Compete on a specific basic need | Keep only if contribution remains non-negative |
| Core | Meet repeated, proven demand | Replenish after stable delivery and margin |
| Improved / bundle | Offer measurable added utility | Show what changed and verify costs |
| Seasonal | Capture time-limited demand | Limit stock until sell-through is visible |
Select products with a return-risk filter
Search Meesho as a buyer and record visible price bands, pack quantities, review themes, imagery quality and missing product details. Do not infer sales volume from search position alone. Before purchasing stock, estimate landed cost, breakage risk, variant complexity and the cost to process one failed parcel.
Lightweight, non-fragile and non-size-sensitive items often simplify a new operator’s logistics, but demand and competition still determine whether those items can earn a margin. A small manufacturer with strong sizing and quality control may perform better in apparel than an inexperienced trader selling generic accessories.
Reliable physical inventory records matter as much as visible listings. The site’s inventory management systems guide explains why returns, reservations and physical stock must stay consistent; the same control problem applies to a Meesho catalog.
Listing Changes That Prevent Expensive Misunderstandings
Show what the buyer will actually receive
Use a clean, accurate hero image, followed by scale, material, color and pack-content views. A photographed item is not enough if a buyer cannot tell whether the order includes one piece or a pair. Describe washable status, capacity, exact dimensions, inclusions and limitations only when substantiated. For clothing, avoid vague “perfect fit” claims and provide garment measurements.
Keyword relevance matters, but images and attributes also need to prevent the wrong buyer from ordering. Write a descriptive product name, fill applicable category attributes and match colors and sizes to real inventory. Do not repeatedly edit successful listings simply to chase a ranking theory. Meesho has not published a complete public formula that establishes a universal weighting for click-through, ratings, price and delivery performance.
Accurate imagery is a business control, not decoration. The related discussion of e-commerce product photography standards explains why consistent product photographs must represent the item being sold.
Run one-variable listing experiments
For a weak listing, first diagnose whether the problem is discovery, clicks, conversion, refusal or post-delivery returns. If people see the item but rarely open it, test the lead photo. If clicks are healthy but delivery complaints mention size, improve measurements instead of lowering the price. Record the edit date and compare sufficiently similar order cohorts. Changes to price, photo, description and ads at the same time destroy useful attribution.
A ₹1 Lakh Monthly Sales Plan That Survives Arithmetic
At a ₹399 realized selling price, ₹100,000 in delivered merchandise value requires approximately 251 delivered units per month, or 8.4 per day. At 15% pre-delivery RTO, reaching 251 deliveries requires roughly 296 dispatched shipments if all other dispatches deliver; those extra shipments can create cost without revenue. Neither figure estimates demand or guarantees achievable traffic.
If the illustrative ₹89 contribution holds for 251 delivered units, the subtotal is ₹22,339 before fixed costs, other losses and tax. But the ₹35 return reserve in the model must already reflect RTO and returns across the relevant shipment base; otherwise the calculation double-counts. A seller should reconcile actual cash receipts and deductions before treating the estimate as earnings.
The first 30 days: build a trustworthy cohort
| Period | Main action | Evidence to retain |
| Week 1 | Choose one need, source samples, price 20–30 SKUs | Cost sheet, measurements, photos, pack tests |
| Week 2 | Publish accurate catalogs and validate fulfillment | Impressions if available, orders, stock accuracy |
| Week 3 | Investigate weak images, sizing and refusal reasons | Change log and order cohorts |
| Week 4 | Reconcile settlements and RTO/return reasons | SKU-level contribution and reorder decision |
Weekly reviews should use both unit economics and operations. A high-sales SKU that erodes contribution is not a winner. A slower SKU with stable deliveries may provide a better foundation for reinvestment. The goal is to move from listing activity to evidence-based replenishment.
Meesho Versus Other Marketplaces: Compare the Right Variables
Platform fees, shipping options, policies and seller eligibility change. A like-for-like ₹300 product comparison cannot be responsibly priced without the seller’s category, fulfillment choices, weight and active fee schedules. Use the following decision matrix rather than invented marketplace charges.
| Decision factor | Meesho | Amazon India / Flipkart |
| Seller onboarding | Official supplier flow; eligible non-GST route is restricted | Check current seller and GST eligibility individually |
| Commission headline | Official supplier pages advertise 0% commission | Category-dependent programs and fee schedules |
| True unit cost | Review seller-panel logistics, returns and promotion | Model referral, fulfillment, shipping and returns |
| Best-fit product | Depends on competition and cost control | Depends on demand, fees and delivery promises |
The zero-commission claim is a feature of Meesho’s published seller proposition, not a proof that it wins every ₹300 product comparison. Evaluate actual settlement data and conversion in each marketplace before choosing a primary channel.
Paid promotions only make sense after the catalog’s offer and delivery experience are sound. The site’s analysis of campaigns tied to measurable customer actions provides a useful parallel: attention is not the same thing as profitable customer behavior.
The Future of Meesho Selling in 2027
The direction of marketplace retail is toward more operational measurement, better catalog information and tighter cost discipline, but specific 2027 Meesho ranking, shipping or fee changes cannot be predicted from current public documentation. Sellers should not plan around rumors of algorithm updates or supposed guaranteed visibility hacks.
More automation in catalog uploads and inventory feeds may make it cheaper to publish a large product range. That creates a counterpressure: when listings are easy to produce, inaccurate product descriptions and unreliable stock can become more costly, not less. A seller with consistent SKU identifiers, genuine photos and return-reason data can respond faster to defects than someone relying on product count alone.
What is durable for 2027 is a practical capability, not a forecast: know landed cost, separate RTO from post-delivery returns, reconcile each settlement, and test product improvements with comparable cohorts. Platform tools will change; the arithmetic of profitable deliveries will not.
Key Takeaways
- Zero commission describes one fee line, not the total cost of delivering an order.
- Use delivered revenue, not dispatched order value, when setting a monthly sales target.
- Track pre-delivery RTO and post-delivery returns separately with reason codes.
- A focused SKU pilot gives cleaner learning than undifferentiated catalog expansion.
- Measure images and product detail by their effect on wrong-expectation returns as well as clicks.
- Reconcile current seller-panel deductions before allocating advertising or reorder budgets.
Conclusion
The strongest Meesho businesses are unlikely to be the ones that upload the greatest number of products first. They are the ones that can answer a less exciting question: after a real parcel is delivered—or comes back—what money actually remains? That requires accurate product information, reliable inventory, a sensible landed-cost model and a willingness to stop selling an attractive but unprofitable SKU.
A ₹1 lakh monthly sales target is useful as a planning exercise because it makes the order requirement concrete. It should not be mistaken for a ₹1 lakh income target, or as proof that demand exists. Start with a small cohort, identify where failed deliveries arise, and improve only what evidence supports. When a product repeatedly produces positive contribution, scale gradually enough that supply and fulfillment remain dependable.
The essential advantage is not a secret ranking factor. It is an operating system that makes bad assumptions visible before more money is committed to them.
Frequently Asked Questions
Is Meesho really commission-free for sellers?
Meesho’s official supplier materials advertise 0% commission. Sellers can still face shipping, promotional, tax-related or return-related costs depending on the current arrangement. Check the applicable agreement and actual settlement.
What documents are needed for Meesho seller registration?
Official onboarding describes a mobile number, email, bank details and either the relevant GSTIN or an eligible non-GST Enrolment ID/UIN. Pickup address and store details are also required. Eligibility can depend on seller status and geography.
Can I sell on Meesho without GST?
Meesho’s official onboarding states that eligible non-GST sellers can use an Enrolment ID/UIN and generally sell within their state. This is not an unrestricted exemption from all tax or marketplace obligations; verify eligibility before registering.
How do I reduce RTO on Meesho?
Break RTO down by SKU and reason first. Improve misleading photos, missing dimensions, packaging and inventory accuracy, then review delivery exceptions through approved seller-support channels. A single store-wide RTO number rarely identifies the cause.
How can I calculate actual Meesho seller profit?
Start from settled delivered-order receipts and subtract product cost, packaging, attributable logistics, actual return losses, ads and overhead. Separate inventory investment from expense recognition, and reconcile the result to platform settlements.
How does Meesho decide which product listings appear first?
Its complete ranking formula is not public. Competitive pricing and accurate catalogs may help shoppers make decisions, but no universal weighting of price, clicks, ratings or fulfillment can be verified. Focus on controllable product quality and economics.
Which products are best for a new Meesho seller?
Products with verifiable demand, affordable landed costs, simple packaging and manageable returns are reasonable candidates. Lightweight home items can simplify a pilot, while apparel can work for operators who know sizing and quality control.
Methodology and Editorial Limits
Research reviewed ten high-visibility 2026 guides for the “meesho seller” and “how to sell on Meesho” search intent: Zane Marketing, Dhanaay, SnapSeller, RegisterKaro, SW Cybernetics (multiple pages), EcomSarthi, The India Post, Limpo and MSMETOOLS. This is a non-personalized research sample, not a verified universal Google top-ten ranking. Most entries emphasize onboarding, zero commission and basic listings; several discuss margin and returns, so the topic is not wholly neglected. The differentiation here is operational measurement and explicit sample arithmetic rather than a claim of exclusive discovery.
Official Meesho supplier documentation was used for its stated commission, onboarding requirements, payout cycle, supplier tools and fulfillment descriptions. The numerical margin model and catalog cohort sizes are editorial illustrations, not platform measurements. No seller account was tested, no source was interviewed and no original performance study was conducted. Marketplace programs can change; the live Seller Panel and seller agreement take priority.
AI-assisted draft. A human editor must verify all citations, fees, calculations, link status and seller eligibility against current primary sources before publication; no completed human review is claimed.
References
Meesho. (n.d.). How to sell on Meesho. Official supplier information.
Meesho. (n.d.). Sell shirts online: Supplier tools, pricing and quality dashboard.
MSMETOOLS. (2026, October 9). How to sell on Meesho in 2026: GST, fees, returns and real margins.
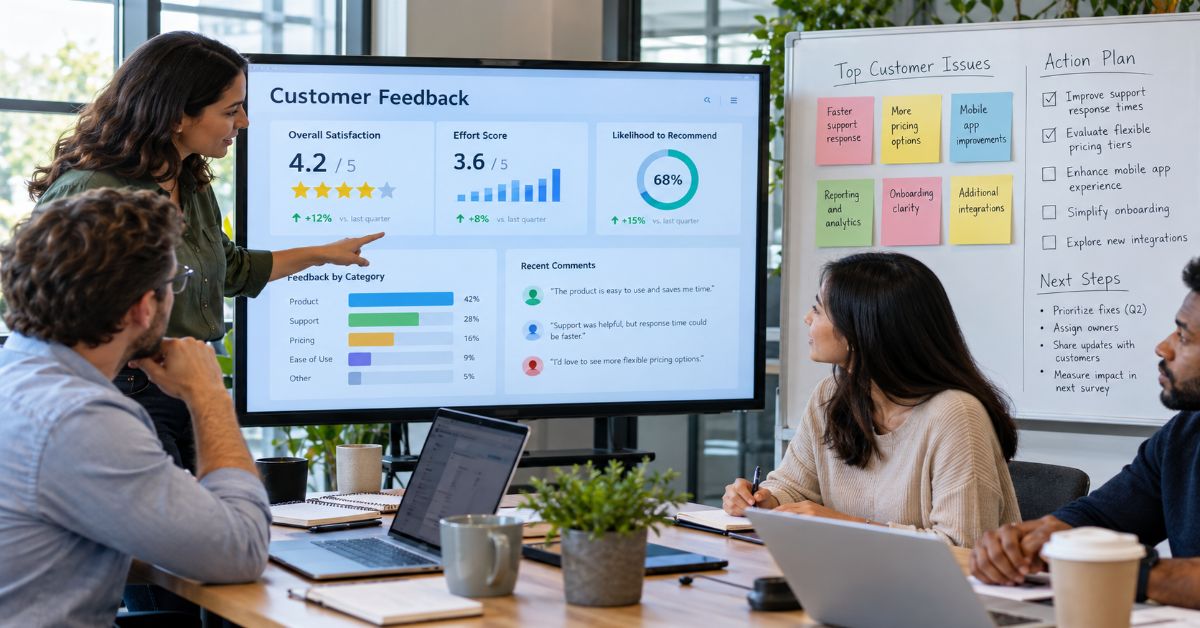
Customer feedback surveys are useful only when the answers can change a real decision. A business can collect hundreds of five-star ratings and still lose customers if nobody identifies recurring friction, assigns responsibility, or checks whether the fix worked. The effective approach is to begin with an action the team is prepared to take, then work backward to the shortest survey capable of informing it.
A customer feedback survey is a structured set of questions about a product, service, purchase, support interaction or relationship. It can measure satisfaction, reveal the cause of a problem or flag a risky customer experience. But it cannot automatically tell a business what caused a change in revenue or retention. The surrounding workflow matters just as much as the form.
Most guides begin with dozens of example questions. That is helpful when wording is the obstacle, but it often skips a more important question: what happens after someone answers? This guide starts there. It maps customer moments to survey types, provides ready-to-adapt templates, explains an analysis process a small team can run in a spreadsheet and shows how to evaluate the resulting change.
Question wording deserves care. Pew Research Center documents how answer options, ordering and pretesting affect survey measurement. Rather than treating survey numbers as objective truth, teams should treat them as signals requiring context and validation (Pew Research Center, n.d.).
Start With the Decision, Not the Questionnaire
The one-decision, one-survey rule
Before writing a question, complete this sentence: “If respondents tell us ___, we will decide whether to ___.” If the second blank cannot be filled, the proposed survey lacks a concrete purpose. A checkout team might decide whether to simplify payment authentication; a support manager might decide whether to rewrite a troubleshooting flow. Brand loyalty and feature requests are different decisions and usually deserve different instruments.
A minimal decision record names five fields: customer moment, intended decision, owner, evidence threshold and outcome metric. That small commitment keeps attractive but irrelevant questions out of the form. It also stops a survey from becoming an inbox for every department’s curiosity.
A six-step feedback-to-action system
- Define the decision and the business metric it could affect.
- Select the customer event closest to that decision.
- Ask the fewest questions needed to explain the behavior.
- Assign each response to a person or team with authority to act.
- Set review and escalation rules before results arrive.
- Make a change, notify customers where appropriate and recheck the outcome.
The model is a working editorial framework, not a validated scientific scoring method. Teams should adapt its thresholds to their volume, severity and risk.
Choose the Survey That Fits the Business Decision
CSAT, NPS and CES answer different questions. Customer Satisfaction Score (CSAT) commonly asks for satisfaction with an interaction; Customer Effort Score (CES) asks how easy a task felt; Net Promoter Score (NPS) asks likelihood to recommend. Qualtrics describes these as complementary measures, not interchangeable diagnoses (Qualtrics, n.d.).
| Decision | Instrument | Best trigger | What to do with it |
| Improve support resolution | CES + resolution check | Soon after ticket closure | Audit handoffs and reopened tickets |
| Repair first-use friction | Milestone micro-survey | After first attempt at key task | Fix blockers in activation flow |
| Reduce purchase abandonment | Exit or abandonment prompt | At exit or follow-up with permission | Inspect payment or shipping barriers |
| Monitor relationship risk | NPS + reason | Periodic relationship review | Segment by account and usage |
| Improve delivery | Post-delivery CSAT | After confirmed delivery | Separate carrier issues from product issues |
| Evaluate feature usability | In-app task survey | After feature use | Check completion and error logs |
Why a score should not become the decision
A rise in CSAT after a change might reflect a different mix of respondents rather than a better experience. NPS can move because of price, public news or competitive alternatives. CES may identify friction without showing why it occurred. Compare relevant behavioral outcomes and consistent customer segments before attributing impact.
For adjacent website journeys, Aperplexity’s practical discussion of navigation and shortcut design illustrates why removing a repeated customer task can matter more than adding another feedback prompt.
Internal reading: quick links and reducing navigation friction
Timing Is Part of Survey Quality
Ask too early and customers cannot assess the outcome; ask too late and details fade. A support survey belongs after the resolution is credible, not necessarily the instant an agent marks a ticket closed. Delivery questions should distinguish ordering, shipping and product use. For a long onboarding journey, a milestone is more informative than an arbitrary “day three” email.
| Moment | Useful prompt | Common timing mistake |
| Support resolved | “How easy was it to get your issue resolved?” | Sending before customer confirms success |
| First successful use | “What nearly stopped you?” | Surveying before the core task |
| Order delivered | “What made delivery difficult, if anything?” | Confusing shipping with product quality |
| Cancellation | “Which factor mattered most?” | Using a generic satisfaction score only |
| Quarterly account review | “What would affect your renewal decision?” | Over-surveying accounts with low activity |
Channel choice matters. An in-app question can capture immediate product friction; an email can invite a considered relationship assessment. Use suppression rules so one customer is not asked about the same journey by three different teams in a week. The exact cooldown should be piloted, not marketed as a universal best practice.
Write Questions That Preserve the Evidence
Ask behavior first and interpretation second
“What were you trying to complete?” anchors the answer in a real task. “What made that step difficult, if anything?” invites a specific observation without presuming failure. By contrast, “Why was checkout so confusing?” builds a negative conclusion into the question. Pew Research Center advises clear, specific wording and response options that do not overlap.
Replace double questions with single decisions
Bad: “Was the agent fast and helpful?” A customer may have received fast but incorrect advice. Better: “Was your problem resolved?” followed by “How easy was it to get help?” These separate outcome from effort. Another bad question is “Did price and delivery meet expectations?”—two topics with potentially opposite answers.
Use a question audit before sending
- Does every question connect to an owner and decision?
- Could a respondent interpret it in two reasonable ways?
- Are answer choices distinct and sufficiently complete?
- Is open text optional when possible?
- Have a few target customers interpreted the questions as intended?
- Can respondents skip or decline sensitive information?
Treat a three-to-seven-question range as a planning heuristic for compact operational surveys, not a universal research standard. Short, event-driven micro-surveys may need only one scored prompt and an optional comment; formal studies may require considerably more.
Three Copy-Ready Customer Feedback Survey Templates
SaaS onboarding: diagnose stalled activation
Trigger: after a user attempts the first meaningful task. Decision: whether to revise setup instructions, permissions or the product flow.
- What were you trying to accomplish today?
- Were you able to complete it? (Yes / Partly / No)
- Which step, if any, slowed you down? (Select one)
- What change would make that step easier? (Optional)
Route “No” answers attached to blocked setup or permissions to product and support. Compare answers with actual activation events; a customer saying setup felt easy does not prove the feature was adopted.
Ecommerce: find preventable purchase friction
Trigger: after a completed order or an eligible abandonment follow-up. Decision: what to test in checkout next.
- Which part of checkout took the most effort?
- Did anything almost stop you from placing the order?
- What, if anything, would make your next order easier? (Optional)
Do not ask post-purchase customers to recall an abandoned purchase they never made. Segment mobile and desktop experiences and inspect actual error logs. Marketing creativity can influence intent, but checkout success requires a functioning customer path, a distinction explored in Aperplexity’s analysis of participation-based campaigns.
Internal reading: marketing campaigns and measurable customer actions
Support: separate courtesy from resolution
Trigger: once a case has reached a meaningful outcome. Decision: whether to update scripts, escalation or staffing.
- Was your issue resolved? (Yes / Partly / No)
- How easy was it to reach a resolution? (Very difficult to very easy)
- Which part of getting help took the most effort? (Optional)
- May our team contact you to clarify the issue? (Optional)
Agent politeness is not equivalent to issue resolution. Monitor repeat contacts and reopened cases alongside survey ratings. If the survey reveals repeated outages, technical service readiness may be more important than revised support language.
Internal reading: status probes and the difference between healthy signals and real service quality
Analyze Responses Without a Data Science Team
Begin with a simple response log: date, touchpoint, segment, score, verbatim comment, theme, severity, owner, status and outcome. Remove personally identifying details that are not needed for the decision. A spreadsheet can support the first several hundred responses if someone maintains consistent tags and reviews uncertainty.
Separate frequency, severity and confidence
A frequent annoyance may cost seconds while a rare billing defect can lose a major account. Give each issue a frequency count, severity rating and confidence note. An optional triage score is frequency × severity, but this is a heuristic: it is not causal proof and it should never outrank an urgent security, accessibility or safety issue.
| Issue (illustrative) | Responses | Severity 1–5 | Triage score | Decision |
| Confusing setup invitation | 12 | 3 | 36 | Rewrite invitation and test activation |
| Incorrect invoice amount | 2 | 5 | 10 | Escalate immediately despite lower score |
| Hard-to-find help link | 9 | 2 | 18 | Test navigation placement |
These figures are hypothetical demonstrations, not results from a conducted survey. If only a few customers respond, call the output a set of leads rather than a representative sample. Review the distribution of who did not answer, and avoid presenting a percentage without its denominator.
Compare groups before approving a fix
Segment by lifecycle, plan, device, region or case type when sample size permits. Consider whether a highly dissatisfied group is overrepresented in the responses. Look for a second signal: funnel data, contact transcripts, refunds, usage logs or interviews. Agreement between sources strengthens the case, although it still does not automatically establish causation.
Create a monthly three-fix review
Produce one page showing the top three fix candidates, customer evidence, expected metric, implementation owner and check-in date. “Improve satisfaction” is not a measurable work item. “Reduce support tickets reopened within seven days after password-reset help” is. The point is to convert sentiment into testable operational changes.
Close the Loop Without Making Empty Promises
Feedback should lead to either an action, a reasoned decision not to act, or a request for more information. Route severe payment and access problems quickly; group minor requests for periodic review. Where contact permission exists, acknowledge the customer’s problem and give a factual update only after a change is shipped.
A useful message is: “You reported difficulty finding invoices. We moved the invoice link into Billing. We are checking whether related support requests fall.” Avoid promising every suggestion will enter the product roadmap. Some requests conflict, and prioritization must consider costs and other affected customers.
Run before-and-after comparisons carefully. If seasonality, pricing or traffic mix changed at the same time, a better outcome cannot be credited to the survey-driven fix without further evidence. A controlled experiment can help when the decision is consequential and volume allows it.
Risks: Selection Bias, Privacy and Survey Fatigue
Customers who answer may differ systematically from those who do not. Treat response rate as an operational health measure, not a magic quality threshold. A 40% response rate from a biased audience can mislead more than a smaller, well-targeted sample. Report invitation count, eligible population, responses and excluded cases.
Be transparent about anonymity. Truly anonymous surveys cannot be reliably used for individualized follow-up. If a response is linked to an account, say so, restrict access and avoid collecting details not needed for the purpose. Health, financial and employee-related feedback can introduce higher privacy and governance demands.
Too many surveys also change behavior: prompts interrupt tasks and can create annoyance. Use a suppression window, allow dismissal and remove survey questions whose answers have not changed a decision in recent review cycles.
The Future of Customer Feedback Surveys in 2027
By 2027, the more useful distinction may be between systems that summarize feedback and systems that can responsibly turn it into work. Survey platforms already offer automated analysis and templates; the harder requirement is preserving evidence, customer context and an accountable owner. That is a direction of travel, not a confirmed prediction about any specific vendor’s roadmap.
Language models can help classify hundreds of free-text answers into themes, but labels can be inconsistent, overlook sarcasm or flatten small but important groups. Human review of high-severity comments and a sampled set of ordinary comments remains necessary. Teams should document how tags are generated and check errors before treating a summary as a product requirement.
As more feedback arrives through in-app prompts, chat, reviews and customer calls, cross-channel deduplication will become more important. The same service failure reported by one account in four channels must not be mistaken for four separate customers. More data does not always mean a better decision; source quality and customer consent remain constraints.
The practical test in 2027 will not be how sophisticated the sentiment dashboard looks. It will be whether a team can trace an observation to a chosen action, a shipped change, and an outcome that was measured honestly.
Key Takeaways
- Choose one decision before choosing a survey template.
- Keep transactional questions close to the customer experience they measure.
- Distinguish satisfaction, effort and recommendation intent.
- Use clear, neutral wording and pretest it with target respondents.
- Rank recurring issues alongside severe exceptions; never ignore a serious rare failure.
- Give every priority issue an owner, a review date and an outcome metric.
- Tell customers what changed, but avoid attributing improvements without evidence.
Conclusion
An effective feedback program is a compact decision process, not a contest to collect the largest number of answers. A team should know why it is sending a survey, which customer moment gives the clearest evidence, and what would happen if the results show a problem. The survey itself can often be short. The discipline after the response is where the work begins.
A sound starting point is one journey, one owner and one business metric. Ask a neutral rating or behavior question, leave room for context, review responses by theme and severity, and choose a small set of fixes. Then measure whether customer behavior changed. If it did not, revisit the explanation rather than celebrating a higher score.
That restraint is valuable for small companies and large teams alike. Some feedback is noisy, some is contradictory, and some requests cannot be met. Customer research becomes trustworthy when those limits remain visible. The best survey is not the one that produces a flattering graph; it is the one that helps a team make a better decision and learn whether that decision worked.
Frequently Asked Questions
What is the difference between CSAT, NPS and CES?
CSAT gauges satisfaction with an experience, NPS asks likelihood to recommend, and CES measures effort associated with a task. They are not substitutes for retention, revenue or actual task completion data.
How many customer feedback survey questions should I ask?
For a brief operational survey, start with one primary question and one optional explanatory field; expand only if each added question informs an action. Three to seven questions is a useful planning range, not a fixed rule.
How can businesses increase customer survey response rates?
Choose a relevant event, place the prompt in the channel customers already use, explain what the answer will influence, make open text optional and avoid repeatedly surveying the same person. Test rather than assume a particular response-rate target.
Should feedback surveys be anonymous?
Use anonymity when candid aggregate feedback is the aim and individualized follow-up is unnecessary. If answers are linked to accounts for action, describe that clearly and limit access to personal information.
What is a good survey response rate?
There is no universally reliable benchmark. A response rate must be interpreted alongside the audience, recruitment channel, eligibility, survey length and nonresponse bias. Publish the denominator and examine who did not respond.
How do you analyze customer feedback survey results?
Tag comments consistently, compare frequency with business severity, segment users, seek confirmation in behavioral data, and assign owners to the most credible issues. Recheck the business metric after making a fix.
Which customer feedback survey questions should be avoided?
Avoid leading questions, two-topic questions, answer options that overlap, unnecessary sensitive details and questions whose answers cannot influence a decision. Pretest unfamiliar wording before a broad launch.
Methodology
Research reviewed ten publicly visible customer-feedback and satisfaction-survey guides dated or updated around 2026, including SurveyMonkey, Formbricks, ShipTell, Pinlyx, Forms Expert, Gorgias, UserInsight, SurveyMonkey UK, eesel AI and Qualtrics, to compare coverage of examples, score types, timing and action. Search rankings vary by location and date, so this is a representative comparison, not a verified universal top-ten ranking.
The article’s decision and triage frameworks are proposed operational tools rather than externally validated models. Question-design claims were checked against Pew Research Center, and measurement distinctions against Qualtrics and SurveyMonkey. No original field experiment, survey response-rate dataset, or hands-on software test was conducted. Sample tables explicitly use hypothetical inputs. A high rating may coexist with poor retention, and a low response count cannot justify population-wide claims.
This article was drafted with AI assistance. Human editorial review, verification of every citation and link, and approval of the final copy are required before publishing. Do not describe that review as completed until it has occurred.
References
Pew Research Center. (n.d.). Writing survey questions.
Qualtrics. (n.d.). How to design a customer experience survey.
SurveyMonkey. (2026, August 5). Customer satisfaction surveys: Tips, templates and examples.
-
 Technology3 months ago
Hitomi la in 2026: Domain Status, Safety and Risks
-

 Technology2 months ago
Scrolller in 2026: How It Works, Risks and Alternatives
-

 General3 months ago
Voozon.com: What It Is and How the Platform Works
-
 Technology3 months ago
Iwara: What iwara.tv Is, How It Works and What to Know
-

 Technology3 months ago
ThomsonKids.com: Website Guide, Topics & Trust Check
-

 Business3 months ago
incabizgrowth.com Review: Content, Trust & Use
-
 Technology2 months ago
Filetype:pdf Windows Update: Find Better Microsoft Guides
-

 General2 months ago
R Politics: How Reddit’s Political Feed Really Works