Technology
Couldn’t Verify Mi Account – Invalid Username or Password

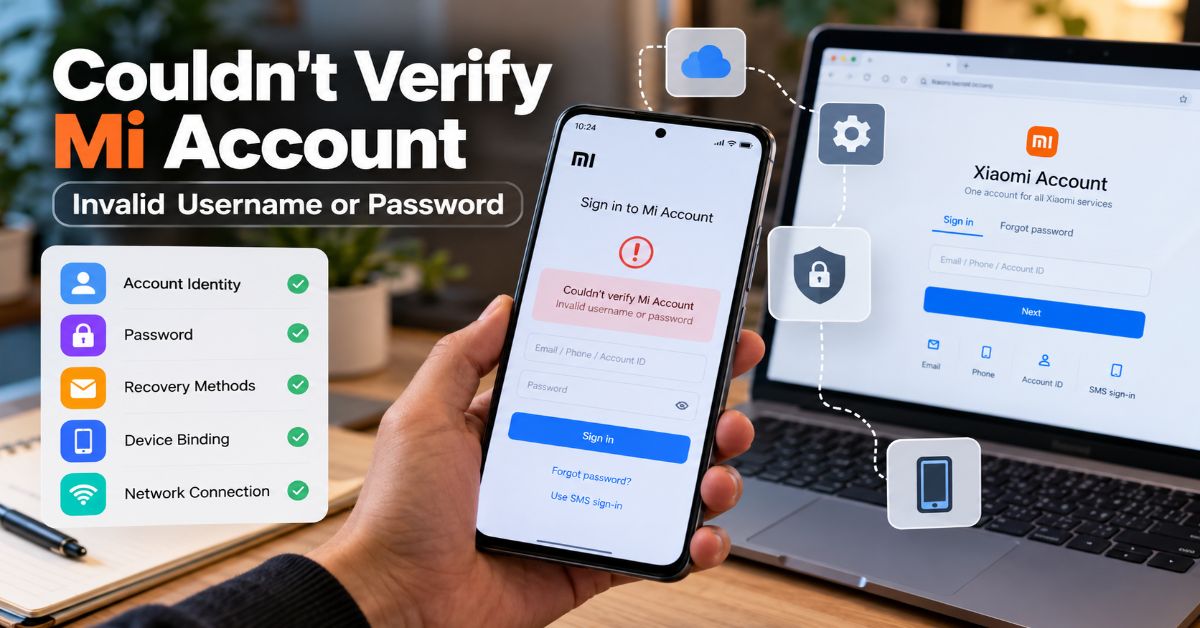
Couldn’t Verify Mi Account – Invalid Username or Password does not always mean the password is wrong. The same screen can appear when Xiaomi cannot match the identifier being entered, when the phone cannot complete an authentication request, when the account is temporarily restricted, or when a reset phone is asking for the Xiaomi Account that was previously bound to it. That is why simply changing the password again and again can waste time without changing the result.
The useful question is not “Which password should I try next?” It is “Which layer is failing?” Xiaomi treats the account identity, password, recovery methods, device binding, and network connection as separate parts of the sign-in process. A clean troubleshooting process tests those parts one at a time and avoids destructive steps until the account itself has been proven to work.
Xiaomi’s current account manual says a user can sign in with a recovery email, recovery phone, or Xiaomi Account ID. Official Xiaomi sign-in guidance also allows SMS sign-in and password recovery. That detail matters because many “invalid username” cases are identity mismatches rather than password failures.
This guide therefore separates three problems that many search results mix together: an account problem, a phone/network problem, and a post-reset ownership-verification problem. That structure also makes it easier to decide what not to do, especially when a phone contains data that has not been backed up.
The Three Failure Modes to Identify First
Before changing settings, classify the situation. The table below is the shortest route to the right branch of troubleshooting.
| What you see | What it usually points to | Best first test |
| Login fails in browser and on phone | Wrong identifier, wrong password, lost recovery method, or account restriction | Use the official recovery flow and verify the exact account identity |
| Browser login works, phone login fails | Phone session, network, time, region, device binding, or software issue | Restart, change network, set automatic time, then retry the same verified account |
| Error appears after reset or on a used phone | Previously bound Xiaomi Account / device activation | Recover the original linked account or use official ownership support |
| SMS code never arrives | Wrong number format, old number, carrier delay, region mismatch, or delivery issue | Confirm country code and try another official recovery method |
| Error followed many failed attempts | Temporary anti-abuse restriction | Stop retrying; wait before using official recovery again |
1. Confirm Which Xiaomi Account the Phone Actually Wants
Xiaomi Account ID, email, phone number, and IMEI are not interchangeable
A Xiaomi Account ID is an account identifier. A recovery email and recovery phone can also act as usernames. An IMEI, by contrast, identifies a device and cannot be substituted for the Xiaomi Account username. This distinction matters after a reset because a phone may display a masked account ID or phone number that does not match the account a user just recovered.
Try the known identities separately: the full recovery email, the recovery phone with the correct international country code, and the Xiaomi Account ID. If the account was originally created through a supported third-party provider, use the same provider where Xiaomi offers that option. Check old Xiaomi emails, SMS messages, cloud sign-ins, and any other Xiaomi device that is still logged in before assuming the account is lost.
For a broader example of why identity systems can fail even when a password is correct, see Aperplexity’s NCEdCloud login and MFA guide. The underlying lesson is the same: a login depends on the account identity and the authentication state, not on the password alone.
Check phone-number formatting before resetting anything
A recovery phone should be entered in the format Xiaomi expects for the registered account. A Pakistani number, for example, may need the +92 country code rather than a local leading zero, depending on the screen. If Xiaomi cannot find the account under one form, do not immediately conclude that the password is invalid. Test the registered email and Xiaomi Account ID as separate identifiers.
2. Use the Browser Test Before Touching the Phone
If the browser login also fails
Open Xiaomi’s official account site and use Forgot password. Xiaomi’s support documentation says the reset flow can use the Xiaomi Account number, bound email, or mobile number, followed by a verification code. If the bound phone is unavailable, the recovery flow can offer another verification method or recovery-info reset where supported.
Do not keep guessing. Xiaomi’s account help says too many incorrect attempts can temporarily block sign-in and recommends trying again later. A temporary restriction can make a correct new password look ineffective if the user immediately repeats the same failed workflow.
If the browser login works but the phone still rejects it
This is one of the most important diagnostic results. A successful browser login proves that Xiaomi recognizes the account credentials at the web layer. The remaining problem is more likely to involve the phone’s connectivity, cached account state, time settings, device binding, region, or activation state. It does not prove which of those is wrong, but it sharply narrows the search.
This “verified account, failing client” distinction also appears in other login systems. Aperplexity’s Availity provider portal guide separates credential recovery from portal and permission problems, which is a useful troubleshooting habit for Xiaomi as well.
3. Fix the Connection Path Without Erasing Data
Prove that the phone can actually reach Xiaomi
A Wi-Fi icon is not proof of working internet. Captive portals, filtered networks, broken DNS, VPNs, private DNS settings, router problems, or an incorrect clock can stop authentication even while the phone appears connected. Xiaomi’s official sign-in FAQ lists lack of internet access as a sign-in failure cause.
- Open a normal website if the browser is available.
- Switch between Wi-Fi and mobile data.
- Temporarily disable VPN or private DNS.
- Try a different trusted network.
- Set date and time to automatic.
- Restart the phone and router before retrying.
The order matters. These checks are reversible and do not delete data. A factory reset is not a sensible response to a network-level authentication failure, especially because a reset can trigger device activation and make the phone require the previously bound Xiaomi Account again.
4. Recover the Account Through Xiaomi, Not a Bypass Tool
Password reset when the recovery phone or email still works
If Xiaomi recognizes the account and you still control its recovery phone or email, use the official password-reset flow. Complete the verification code step, create the new password, and sign in successfully in a browser before returning to the phone. This avoids confusing a failed phone session with a failed password change.
Recovery-info reset when the old phone number is gone
If the bound number is no longer active, Xiaomi provides recovery-info reset paths in its account system. The exact screen can vary by region and account history. Xiaomi may ask for historical account and device information during review, so the useful preparation is evidence, not repeated password attempts.
Xiaomi’s official password recovery instructions describe recovery by SMS, secure email, and an account-appeal route when normal verification is unavailable.
5. Understand Why Factory Reset Changes the Problem
Normal account login vs. device activation
A normal Xiaomi Account sign-in asks whether a person knows valid account credentials. Post-reset device activation asks a different question: whether the person can verify the Xiaomi Account previously associated with the phone. Creating a new Xiaomi Account does not normally replace that ownership relationship.
Xiaomi’s account manual says a locked device can require the username and password, password recovery, recovery-method reset, or an appeal when the account is not the user’s. This is why a phone that works perfectly before a wipe can become unusable after the reset if Find device or account binding was still active.
Second-hand phones need the previous owner or proof of ownership
If a used phone asks for someone else’s Xiaomi Account, the cleanest solution is for the previous owner to remove the device from the relevant Xiaomi account or complete the official ownership process. If that cannot be done, contact Xiaomi support with proof of purchase. A seller who cannot provide the account or ownership proof is not a technical puzzle to solve with a random APK; it is an ownership problem.
Xiaomi explains the official route in its locked-device appeal guidance, including cases where a device was marked lost or flashed while Find device was enabled.
6. Clear Temporary Account State Only After the Account Is Verified
Restart first; clear cache second
If the verified account works in a browser and the phone is accessible, restart the device, install pending system updates, and retry on a stable network. Only then consider clearing cache for relevant Xiaomi account services. Cache clearing should be treated as a secondary device-side step, not as account recovery.
Avoid clearing all app data or resetting the phone simply because a cache option exists. Clearing data can remove sessions and local state without repairing the underlying account or ownership binding. On a device that is already difficult to verify, destructive troubleshooting can make the situation worse.
Aperplexity’s Quick Links guide makes a related point about authentication flows: stable account destinations matter more than transient session screens. For Xiaomi recovery, return to the canonical account portal instead of trusting a stale recovery tab or third-party link.
A Safer Decision Tree
Use this sequence from top to bottom. It deliberately postpones anything destructive.
| Step | Question | Action |
| 1 | Have there been many failed attempts? | Stop retrying and wait before the next official sign-in attempt. |
| 2 | Do you know the exact Xiaomi Account identity? | Test email, recovery phone with country code, and Xiaomi Account ID separately. |
| 3 | Does the account work in a web browser? | If no, recover the account. If yes, move to phone/network checks. |
| 4 | Can the phone reach the internet reliably? | Change network, disable VPN/private DNS temporarily, and enable automatic time. |
| 5 | Did the problem start after a reset or on a used phone? | Treat it as device activation/ownership verification, not a normal login. |
| 6 | Do you still control the recovery phone/email? | Use official password reset or SMS/email verification. |
| 7 | Are recovery methods unavailable? | Use Xiaomi recovery-info reset, support, or the official appeal path. |
| 8 | Are you being offered an unofficial bypass? | Do not provide credentials or install unknown APKs; return to official recovery. |
What Not to Do
Do not install unknown Mi Account bypass APKs
Search results for locked Xiaomi phones often lead to bypass utilities, modified APKs, remote-unlock services, or flashing instructions. Those tools can ask for passwords, SMS codes, payment, USB debugging access, or software installation from unknown sources. Even when a tool claims success, it can introduce malware, leave the phone unstable, or undermine later support.
Aperplexity’s BOMBitUP safety guide explains why sideloaded Android software and verification-code flows deserve extra scrutiny. The same security rule applies here: never trade an account lock for an unverified app with deeper device access.
Do not share passwords, SMS codes, or the full IMEI publicly
A repair shop or seller may legitimately need the device in hand, but they should not need to know a reusable Xiaomi password or SMS verification code. Treat those as account secrets. An IMEI may be requested by official support for ownership verification, but posting the full number publicly is unnecessary.
For the broader credential-security principle, Aperplexity’s defensive guide to exposed login logs shows why passwords, tokens, and session identifiers should not be exposed simply because a troubleshooting workflow asks for “proof.”
Symptoms, Likely Causes, and Next Actions
This table maps common user reports to the most useful next step without pretending that one symptom has only one cause.
| Symptom | Likely explanation | Next action |
| Password fails everywhere | Wrong password, wrong account, or restriction | Use official recovery and stop repeated guesses |
| Browser works, phone fails | Phone session, network, time, region, or device binding | Restart, change network, automatic time, then retry |
| SMS code never arrives | Wrong number format, old number, carrier delay, or region mismatch | Confirm country code; use recovery email or alternate verification |
| Error starts after factory reset | Previously linked Xiaomi Account required | Recover the original account or contact Xiaomi |
| Used phone asks for another account | Previous owner binding | Ask seller/owner to remove it or provide proof of purchase to support |
| Correct password gives “Couldn’t unlock” | Activation or device-side problem rather than simple password rejection | Verify the same account on web, then follow device/ownership path |
| Password changed recently | Phone may have stale account state | Confirm web sign-in, restart, and retry on a trusted network |
What Xiaomi May Ask for During Manual Recovery
Manual recovery is easier when the account history is consistent. Xiaomi’s older and current support material indicates that review can involve account and device history. Prepare the information you actually know rather than inventing details.
- Original receipt or invoice
- IMEI or serial number
- Recovery email and phone number
- Approximate country or region of account registration
- Previous passwords you genuinely remember
- Xiaomi, Redmi, or POCO devices previously used with the account
- A screenshot or exact transcription of the error
- Other proof that the device belongs to you
Not every case will require every item. The goal is to give Xiaomi enough consistent information to distinguish an owner who lost access from someone trying to remove another person’s account protection.
Why Current Search Results Still Miss the Core Diagnostic Split
A current SERP sample for this error includes dedicated recovery explainers, general Xiaomi lock articles, forum threads, Reddit reports, and videos. Many pages move quickly from the error message to a password reset, or from a reset phone directly to “unlock” methods. That skips the most useful evidence: whether the account works outside the phone and whether the screen is ordinary sign-in or device activation.
The search results also contain anecdotal fixes such as removing a device from Find device, changing network state, or retrying after a delay. Those reports can be useful clues, but they should not be promoted to universal fixes without official support. The safer editorial rule is to use community reports to identify failure patterns and Xiaomi documentation to define the recovery path.
The Future of Xiaomi Account Recovery in 2027
The likely direction in 2027 is stronger separation between identity recovery and device ownership verification, not weaker protection. Xiaomi already exposes several recovery layers: password reset, recovery-phone or email methods, recovery-info reset, and a device-unlock appeal. As device theft protections become more important across mobile platforms, reset-based ownership checks are unlikely to disappear.
What may improve is the clarity of the workflow. The most frustrating cases today are those in which a valid password works on the web but the phone does not explain whether it is failing network authentication, account synchronization, Find device state, or activation. Better error codes and clearer account-binding status would reduce unnecessary resets and support contacts. Xiaomi has not published a universal 2027 roadmap for this specific error, so that is an analytical expectation rather than a confirmed product promise.
Key Takeaways
- Treat the error as a diagnostic problem, not automatic proof of a wrong password.
- Verify the exact Xiaomi Account identity before changing the password again.
- Use a browser sign-in to separate an account problem from a phone problem.
- Check network, VPN/private DNS, and automatic time before destructive steps.
- After a factory reset, expect the previously linked Xiaomi Account to matter.
- For second-hand devices, ownership resolution is more important than technical bypasses.
- Use Xiaomi’s official recovery and appeal paths; avoid unknown bypass tools and credential-sharing services.
Conclusion
The fastest way to solve Couldn’t Verify Mi Account – Invalid Username or Password is to stop treating every instance as the same password error. First identify the account Xiaomi expects. Then prove whether those credentials work in a browser. If they do, move to network, time, session, and device-binding checks. If the problem appeared after a reset, treat it as ownership verification rather than ordinary sign-in.
That sequence protects two things at once: the user’s data and the integrity of the account. It also prevents the most common escalation mistake—resetting, flashing, or installing a bypass tool before the account itself has been verified. When normal recovery is unavailable, Xiaomi’s recovery-info and locked-device appeal processes are the appropriate next step, supported by proof of ownership rather than another round of password guessing.
Frequently Asked Questions
Why does Xiaomi say invalid username or password when the password is correct?
The phone may be using the wrong account identifier, failing to reach Xiaomi reliably, holding stale account state, or asking for a previously linked account during device activation. Test the same account in a browser first. If web sign-in works, the password itself is less likely to be the problem.
How do I fix Couldn’t Verify Mi Account – Invalid Username or Password after a reset?
Recover the Xiaomi Account that was linked to the phone before the reset. Verify it on Xiaomi’s official account website, then use the same account for device activation. If recovery phone and email access are gone, use Xiaomi’s recovery-info or official device-unlock appeal process.
Can I use my phone number instead of the Xiaomi Account ID?
Yes, if it is the recovery phone registered to the account. Xiaomi also accepts a recovery email or Xiaomi Account ID for password sign-in. Use the correct country code and test each known identifier separately.
Why does my Xiaomi Account work on the website but not on the phone?
That result points away from a simple password problem. Check the phone’s internet connection, VPN or private DNS, automatic date and time, current system software, cached account state, region, and whether the phone is in a device-activation flow.
Will another factory reset remove the Mi Account lock?
Normally, no. A reset can erase local data but it does not prove ownership of the previously linked Xiaomi Account. Repeated resets may leave the phone at the same activation screen while creating more risk for unsaved data.
What if I bought the Xiaomi phone second-hand?
Ask the previous owner to remove the phone from the relevant Xiaomi account and Find device relationship. If that is not possible, use Xiaomi support and provide valid proof of purchase. A new Xiaomi Account usually cannot replace the prior ownership binding.
Are Mi Account bypass tools safe?
They should not be treated as a normal recovery method. Unknown APKs, flashing tools, remote-unlock services, and credential-sharing requests can expose account secrets, introduce malware, or leave the phone unstable. Official Xiaomi recovery and ownership verification are safer.
Methodology
Research for this article was completed on October 1, 2026. The competitive review used a current search sample around the exact error and close variants, including Xiaomi’s own help pages, Octopis, iMobie, Wondershare/Dr.Fone, MagFone, XDA, Reddit threads, an Android forum, and video results. Search order varies by country, device, personalization, and index freshness, so the sample is used to identify recurring coverage and gaps rather than to claim a permanent ranking order.
Primary factual validation relied on Xiaomi Account Help Center and Xiaomi Global Support pages covering sign-in methods, incorrect passwords, failed sign-in, password reset, account recovery, and locked-device appeals. Community reports were used only as evidence of recurring user scenarios, such as a web login working while device activation still fails; they were not treated as universal technical fixes.
References
- Xiaomi. (2026). How do I sign in to my Xiaomi Account? Xiaomi Account User Manual.
- Xiaomi. (2026). Why am I notified that my username or password is incorrect? Xiaomi Account User Manual.
- Xiaomi. (2026). Why can’t I sign in to my account? Xiaomi Account User Manual.
- Xiaomi. (2026). Recover or reset the password of Mi account. Xiaomi Global Support.
- Xiaomi. (2026). How do appeals work? Xiaomi Account User Manual.
Now.gg is a cloud gaming platform that can turn a modest browser device into an Android gaming endpoint, but the important 2026 story is no longer simply “play Roblox without downloading.” The service has matured into a wider mobile-cloud distribution layer, while the search results around it have not matured at the same speed. Some current guides still present old game-specific launch paths as permanent. Newer checks show that individual listings can disappear or redirect, which means the platform should be judged by its architecture and current catalog—not by a stale URL.
That distinction matters because now.gg solves a very specific problem well: it moves game execution away from the user’s phone, Chromebook, laptop, or desktop and into remote infrastructure. The browser receives a live stream and sends inputs back. The result can remove download size, storage pressure, operating-system friction, and much of the local CPU/GPU burden. now.gg’s own platform description frames this as a distributed Android system rather than a conventional installed emulator.
The trade is equally specific. Hardware constraints become network constraints. Local installation risk is reduced, but cloud-session telemetry and account data still exist. Free access may be ad-supported, while nowPremium adds ad-free fullscreen play and proxy/VPN support in supported regions for $0.99 per day. And a game that was available last year may not be available next month.
This guide evaluates now.gg as it exists in 2026: how the stack works, how it differs from local emulation, what the developer economics actually mean, what the privacy policy says, where latency and availability become deal-breakers, and what the platform’s “Infinity Phone” vision could realistically mean for 2027.
The Architecture Is the Product
From local Android emulation to distributed Android
A local Android emulator such as BlueStacks or LDPlayer runs the Android environment on the user’s own machine. That means the PC still needs enough CPU, GPU, RAM, storage, and driver stability to produce a good experience. now.gg reverses that model. The Android workload is hosted remotely, then streamed to the device through the browser.
The technical distinction is more than marketing language. now.gg describes nowCloudOS as a distributed Android architecture that can use heterogeneous cloud nodes and adapt the workload around endpoint capability, bandwidth, and latency. An earlier launch announcement also described Arm-native execution on AWS Graviton2 instances, avoiding the architectural translation problem that can appear when Android workloads are forced through mismatched server environments.
In plain English, the flow looks like this:
- The game runs inside a remote Android environment.
- The cloud renders each frame and encodes the output as a stream.
- The browser receives the stream instead of rendering the full game locally.
- Keyboard, touch, mouse, or controller input travels back to the remote session.
- The platform adapts the session to network and endpoint conditions.
That browser-centric model also makes general web quality relevant. Aperplexity’s web development quality guide explains why interaction latency, accessibility, stable rendering, and security are release concerns—not cosmetic extras. In cloud gaming, those browser-layer details sit on top of an already latency-sensitive streaming loop.
now.gg vs Local Emulator vs General Cloud Gaming
The clearest way to understand the service is to compare where the computation happens and what bottleneck remains.
| Model | Where game runs | Local hardware demand | Network sensitivity | Typical strength |
| now.gg | Remote Android cloud session | Low to moderate | High | Instant browser access to supported mobile titles |
| Local Android emulator | User’s PC | Moderate to high | Low after download | Broad local control and predictable installed access |
| General cloud gaming | Remote PC/console-class server | Low to moderate | High | Streaming larger PC/console libraries |
The practical insight is that now.gg is not “an emulator in a browser.” It is closer to remote Android execution. That makes it unusually useful on machines where installing software is impossible, storage is tight, or the hardware is weak. It also explains why a fast local computer does not fix cloud latency: the slow part may be outside the device entirely.
The 100 Million User Headline Needs Context
On March 20, 2024, now.gg announced that it had passed 100 million registered users across iOS, Android, PC, Mac, and TV. That is a meaningful top-of-funnel scale claim, but it should not be rewritten as 100 million monthly active gamers, paying users, or simultaneous cloud sessions. The public announcement did not establish those measures.
This distinction is one of the easiest ways to improve on the current SERP. Several pages use the milestone as proof of current dominance without separating registered accounts from engagement. For a player, the number says little about queue time or title availability. For a developer, it says little about payer conversion, retention, customer acquisition cost, or whether now.gg adds new users rather than shifting existing ones.
Developer Economics: The 95% Cut Is Only the First Line
now.gg currently advertises a 95% developer share on cloud in-app purchases. Its 2024 announcement described a 5% platform fee for in-game transactions and a 0% now.gg platform fee for purchases through now.gg-powered webshops. The headline comparison is attractive because mainstream mobile stores have historically been associated with higher commissions, but a platform fee is not the same thing as net margin.
| Purchase route | Published now.gg platform fee | Advertised developer share | What still needs verification |
| In-game cloud purchase | 5% in 2024 announcement | 95% | Processing, tax, refunds, chargebacks, hosting, settlement terms |
| now.gg-powered webshop | 0% now.gg platform fee in 2024 announcement | Up to 100% before other costs | Payment costs, taxes, contract eligibility, region and method limits |
| Native app-store purchase | Varies by store/program | Varies | Store rules, reduced-fee programs, payment restrictions |
The useful question for an indie studio is not “Is 5% lower than 30%?” It is “Does this route produce incremental profitable users after every cost and constraint?” A five-point platform fee can be excellent and still produce weak economics if cloud hosting, paid acquisition, fraud, chargebacks, or low retention absorb the difference.
There is also a distribution advantage that store-fee comparisons miss. A link can collapse the path from an ad, creator post, community page, or message into a playable session. That can reduce install friction. But the lift should be measured as incremental conversion, not assumed from the existence of a cloud link.
Privacy and Security: Safer Device, Centralized Session
now.gg’s security model has a real advantage: the Android game is executed remotely, so the user’s device does not need to download and execute the game package locally. The company also says credentials entered inside a game’s login prompt remain inside that app’s security envelope rather than being exposed to now.gg.
That does not mean the service is data-free. In its Terms and Privacy policy, now.gg says mobile numbers are used to send authentication codes for login verification and are not shared for marketing. Its cookie policy describes analytical and third-party cookies used to understand site use, measure advertising, and support personalization. For users covered by its GDPR notice, the policy says personal data is retained while the account is open and for 12 months after closure, with longer retention possible where legally required.
This creates the real privacy trade: fewer permissions and less local execution on the endpoint, but a cloud operator necessarily observes enough session and account context to deliver, secure, measure, and monetize the service.
The same separation between transport security and trust appears in other browser services. Aperplexity’s third-party viewer privacy analysis makes a useful general point: an active HTTPS site can still require a separate judgment about tracking, data retention, upstream dependencies, and account behavior.
The Weakest Link Is Usually the Network
Cloud gaming converts a hardware problem into a round-trip-time problem. A local game can react to input almost immediately after the device processes it. A cloud game must send the input to a remote system, process it, render a frame, encode it, transmit it back, decode it, and display it. Each stage can be fast, but the chain is only as strong as the slowest segment.
This is why action-heavy games are less forgiving than slower genres. A turn-based title can hide tens of milliseconds. A competitive shooter, rhythm game, or precision platformer exposes them.
| Condition | Likely effect | Best response |
| Stable low-latency connection | Responsive play | Use nearest practical network path and wired/Wi-Fi 6 where available |
| High jitter or packet loss | Stutter, input inconsistency, stream degradation | Fix network stability before upgrading the device |
| High base latency to cloud region | Persistent input delay | Cloud play may be a poor fit regardless of local hardware |
| Congested shared Wi-Fi | Intermittent quality drops | Reduce competing traffic or switch network |
5G helps only when the whole path helps. now.gg’s Infinity Phone concept depends on high bandwidth and low latency, but current network research continues to show that a “5G” label alone does not guarantee lower end-to-end latency. Edge placement, routing, device power management, and network load still matter.
Game Availability Is a Feature, Not a Constant
Many now.gg articles are written as if a game page is permanent. It is safer to treat the catalog as negotiated inventory. Publishers, licensing arrangements, technical compatibility, regional policy, and platform priorities can change.
The Roblox example is useful because it exposes the difference between the service and the catalog. Historical now.gg articles still describe a direct Roblox browser flow. Yet current 2026 checks by multiple publishers report that the old Roblox app URL redirects to the now.gg homepage and that Roblox may not appear in current listings. The right instruction is therefore: search the current catalog first. Do not assume an old app URL still represents a supported launch path.
That is also a general navigation lesson. Aperplexity’s Quick Links guide argues for durable canonical destinations rather than temporary session or deep links. For now.gg readers, the platform’s live catalog is a safer destination than bookmarking a years-old game-specific route.
Who Benefits Most—and Who Should Avoid It
Best fit
- Users on low-end hardware who can run a modern browser but struggle with local Android games.
- Chromebook, Linux, Mac, or shared-computer users who cannot install a local Android emulator.
- Players who want to try a supported title before committing storage or a large download.
- Developers testing link-based acquisition and lower-friction cloud distribution.
Poor fit
- Competitive players who are sensitive to small input-delay changes.
- Users with unstable, congested, or high-latency connections.
- Anyone who needs offline play or guaranteed long-term access to a specific title.
- Users who prefer local control over files, mods, graphics settings, or deterministic installed performance.
The decision rule is simple: choose now.gg when the local device is the bottleneck and the network is good. Choose local execution when the network is the bottleneck or when control and predictability matter more than instant access.
Sustainability: Less Hardware Pressure Does Not Mean Less Energy
Cloud gaming can extend the useful life of weak devices because the user does not need to buy a stronger GPU or phone just to execute the game locally. That can reduce pressure for hardware turnover. But the computation does not disappear; it moves into a data center and adds network delivery.
Research summarized by Lawrence Berkeley National Laboratory’s Green Gaming project found cloud gaming used substantially more total energy than comparably powerful local equipment in its test scenarios, reaching roughly three times as much in the most extreme cases it evaluated. The exact result depends on device class, server efficiency, network path, utilization, and electricity mix, so it should not be converted into one universal “carbon per now.gg session” number.
The balanced conclusion is that now.gg may reduce the need for a hardware upgrade for a particular user while increasing the energy consumed to deliver each hour of play. Those two effects operate at different layers and should not be collapsed into a single green-or-not label.
The Future of now.gg in 2027
The most interesting 2027 question is whether now.gg remains mainly a convenient gaming portal or becomes a broader execution layer for mobile apps. The company’s public roadmap language points toward the second idea. nowCloudOS is described as compatible with existing Android apps while being designed for cloud-native and hybrid edge applications, and the Infinity Phone concept imagines apps and user data moving transparently between device and cloud.
Three constraints will decide whether that vision becomes more than a platform page. First, latency has to be low and predictable, not merely fast in ideal 5G conditions. Second, publishers need economics that justify cloud hosting and distribution. Third, users need trust: clear privacy terms, consistent account behavior, and enough catalog stability that cloud access feels dependable.
The more realistic near-term evolution is incremental: better edge placement, more efficient encoding, tighter session analytics, improved browser controls, and more direct web-to-game acquisition. A truly “infinite” phone is a longer bet because it depends on carriers, manufacturers, app architecture, identity, storage, billing, and privacy moving together.
Key Takeaways
- now.gg’s core value is remote Android execution, not simply a website that hosts games.
- The platform removes many local hardware and installation limits but makes network quality the primary performance variable.
- The 100 million figure is a 2024 company-reported registered-user milestone, not proof of 100 million active players in 2026.
- A 95% developer share can improve gross platform economics, but net profitability depends on all other payment, infrastructure, acquisition, and support costs.
- The privacy model reduces local execution risk while still centralizing account and usage data in a cloud service.
- Game availability can change; readers should verify the current catalog instead of trusting old deep links.
- Cloud gaming can delay device upgrades yet still consume more total energy per session than local play in some scenarios.
Conclusion
now.gg is most useful when understood narrowly and evaluated broadly. Narrowly, it solves one concrete technical problem: it lets a browser act as the endpoint for a remotely executed Android game. Broadly, that design changes where performance, privacy, economics, and platform risk live.
For players, the service can be a strong answer to weak hardware, blocked installs, limited storage, or cross-device convenience—provided the connection is stable and the desired title is currently available. For developers, the more interesting proposition is not just cloud play but lower-friction distribution and a published payment model that can leave a larger share of transaction revenue with the studio.
The weak assumption to avoid is that cloud removes trade-offs. It relocates them. Local CPU and storage become network latency. App installation becomes session dependence. Store distribution becomes cloud-platform dependence. That is why now.gg deserves a more serious 2026 evaluation than another “play without downloading” guide.
Frequently Asked Questions
What is now.gg?
now.gg is a mobile cloud platform that runs supported Android games on remote infrastructure and streams the interactive output to a user’s browser. The device mainly displays the stream and sends player input back, so local CPU, GPU, storage, and operating-system limits matter less than they do with local execution.
Is now.gg safe to use?
It is a legitimate cloud-gaming service, and remote execution reduces the need to download game files onto the device. Safety is not the same as zero data collection: now.gg’s privacy materials describe account information, cookies, analytics, and retention rules. Users should also protect game accounts with unique passwords and current authentication controls.
Is now.gg free in 2026?
The platform has historically offered ad-supported access, while nowPremium is currently advertised in supported regions at $0.99 per day for ad-free fullscreen play and proxy/VPN support. Availability, limits, and pricing can change by region, so the live subscription page should be checked before purchase.
Can I still play Roblox on now.gg?
Do not assume an old Roblox deep link still works. Historical now.gg pages describe browser play, but multiple 2026 checks report that the old Roblox app URL redirects and the title may not appear in the current catalog. Search now.gg’s live game listings first.
Does now.gg work on iPhone, iPad, Chromebook, Mac, or Linux?
now.gg’s model is browser-based and its public materials describe access across multiple operating systems and device types. Actual control support and game availability can vary by title, browser, region, and current platform configuration.
Is now.gg better than BlueStacks?
They solve different bottlenecks. A local emulator is better when the PC is powerful, the network is inconsistent, and the user wants predictable installed access. now.gg is better when installation or local hardware is the obstacle and the network connection is strong.
How does now.gg make money?
The business combines advertising, premium access, developer cloud services, payments, and distribution. For developers, now.gg advertises a 95% share on cloud in-app purchases and previously announced a 0% now.gg platform fee for purchases through now.gg-powered webshops, subject to current commercial terms.
Methodology
Research was conducted on October 7, 2026. A representative high-visibility ten-result sample for the focus query and close-intent variants was reviewed before drafting. The sample included Android Authority, Beebom, GeekChamp, iTechGuides, Smartupworld, Survey.GG, TechDemis, FinanceTimez, QuickRead, and Social Computing Journal. Search order varies by location, personalization, device, and index freshness, so this is a current competitive benchmark rather than a permanent global top ten.
The recurring competitor strengths were clear definitions, browser-play instructions, game examples, and basic pros/cons. The recurring gaps were deeper nowCloudOS architecture, the difference between registered users and active users, transaction-route economics, policy-level privacy details, sustainability trade-offs, and the risk of repeating stale game-specific links. The article structure was therefore built independently around those unresolved questions rather than mirroring any competitor’s section order.
Primary validation came from now.gg’s platform, payments, privacy, premium, and company materials; the March 20, 2024 PR Newswire announcement; and Lawrence Berkeley National Laboratory’s Green Gaming research. Third-party pages were used mainly to benchmark current search coverage and to verify the 2026 disagreement around legacy Roblox links. No hands-on gameplay test, latency benchmark, account signup, or payment transaction was performed for this draft.
Known limitations: now.gg does not publicly expose every current commercial term, regional entitlement, title-specific performance metric, or complete active-user figure. Catalog availability can change after publication. The 100 million user milestone is company-reported and refers to registered users. Energy findings from cloud-gaming research are scenario-dependent and should not be treated as a platform-specific carbon measurement.
Publication disclosure (use only after a human editor has completed the stated review): “This article was drafted with AI assistance and reviewed by a human editor before publishing. All data, citations, and claims have been independently verified against primary sources.”
References
Lawrence Berkeley National Laboratory. (n.d.). Cloud gaming. Green Gaming.
now.gg. (2021). now.gg launches mobile cloud. Brings gaming to the next billion.
now.gg. (2024, March 20). now.gg crosses 100M users, announces 0–5% platform fee for iOS, Android, PC, Mac and TV. PR Newswire.
now.gg. (2024). Privacy Policy and Terms of Use. Effective July 11, 2024.
now.gg. (n.d.). Cloud based mobile game monetization.
now.gg. (n.d.). nowCloudOS: Built on Distributed Android technology.
now.gg. (n.d.). How to subscribe to nowPremium.
Song, P., Lee, J., Abdelmoniem, A. M., & Mukhanov, L. (2025). Unlocking the power of 4G/5G mobile networks: An empirical dive into quality and energy efficiency in YouTube Edge services. Computer Networks, 267, 111344.
Machine learning models are trained functions that turn data into predictions, rankings, classifications, recommendations, or actions, but the sharpest practical lesson is this: a model can score brilliantly in a notebook and still be a bad decision system in production. The gap appears when the training data leaks future information, probabilities are poorly calibrated, the live population changes, latency is too high, or the model optimizes a metric that does not match the cost of a real mistake.
That is why another catalogue of linear regression, decision trees, support vector machines, and neural networks is not enough. Those families matter, but the useful question is not “Which algorithm is most advanced?” It is “Which assumptions can this model safely make, what data does it need, what happens when it is wrong, and what will it cost to keep trustworthy after deployment?”
A current high-visibility SERP sample reviewed for this guide included TechTarget, Dataquest, Snowflake, Coursera, Google Cloud, IBM, Alibaba Cloud, ClicData, GrowthGear, and Straive. Their common strengths are clear definitions, model-type taxonomies, algorithm examples, and selection advice. The recurring gap is operational judgment: calibration, leakage, monitoring, error cost, feedback loops, subgroup behavior, and the difference between a fitted model and the surrounding system. This guide is built around that gap rather than mirroring their section order.
What a Machine Learning Model Really Contains
At its core, a model is a parameterized function that maps an input x to an output ŷ: ŷ = fθ(x). Training changes the parameters θ so the output better matches an objective, usually by reducing a loss function on examples. That compact definition hides several concepts that are easy to blur together.
| Term | What it means | Example in a random forest |
| Algorithm | The procedure used to learn from data | The tree-building and ensemble procedure |
| Architecture or model family | The structural form of the predictor | Many decision trees combined |
| Parameters | Values learned from training data | Split thresholds and leaf predictions |
| Hyperparameters | Settings chosen around training | Number of trees, depth, feature sampling |
| Trained model | The fitted structure used for inference | The final forest applied to new records |
The distinction becomes more important in production. A deployed machine learning system also needs data collection, validation, feature transformation, a serving interface, monitoring, rollback or retraining logic, business rules, and often human review. The fitted model may be the mathematical center, but it is not the whole operational product.
That systems view connects directly to microservices architecture, because a model endpoint inherits the same questions about boundaries, dependencies, observability, and failure isolation as any production service.
Three Different Ways to Classify Models
Many explainers mix learning signals, output types, and model structures as if they were competing categories. They are different axes. A transformer can be self-supervised during pretraining, generative in output, and neural in architecture at the same time.
| Axis | Examples | What the axis answers |
| Learning signal | Supervised, unsupervised, semi-supervised, self-supervised, reinforcement | Where does the training signal come from? |
| Output or task | Regression, classification, ranking, forecasting, generation, representation, policy | What kind of result must the system produce? |
| Model structure | Linear, tree-based, kernel, neighbor, probabilistic, neural, graph | What assumptions and computation shape the prediction? |
This separation is more than vocabulary. It prevents false comparisons. “Supervised versus generative,” for example, is not a clean either-or choice; one describes how learning is supervised, while the other describes what distribution or output the model produces.
The Major Model Families—and the Trade-Off Each One Buys
Linear and generalized linear models
Linear regression, logistic regression, and regularized variants are strong baselines because their behavior is comparatively easy to inspect, train, and serve. They work best when relationships are reasonably additive or can be made useful through feature engineering. Their weakness is not “being old”; it is limited flexibility when the true relationship depends on complex interactions. Regularization such as ridge, LASSO, or elastic net is valuable because it restrains sensitivity to noisy or redundant signals.
Decision trees, bagging, and boosting
Trees divide the feature space with learned rules. A single tree can model nonlinearity and interactions but becomes unstable or overfit when allowed to grow deeply. Bagging methods such as random forests reduce variance by combining many partly independent trees. Boosting methods such as gradient-boosted trees, XGBoost, LightGBM, and CatBoost build models sequentially to correct prior errors. For structured tabular data, boosting is often a formidable baseline because it captures interactions without requiring the scale of deep learning.
Support-vector and nearest-neighbor models
Support vector machines can work well on small or medium high-dimensional problems, especially when a margin is meaningful and feature scaling is controlled. K-nearest neighbors makes a different bargain: almost no conventional training, but potentially expensive inference and a heavy dependence on the chosen distance metric. In high dimensions, distances become less informative, which is why “similar example” is not a neutral concept.
Probabilistic models
Naive Bayes, Bayesian models, Gaussian processes, mixture models, and related methods treat uncertainty as part of the prediction rather than an afterthought. That is useful when a decision threshold depends on risk. But probability output is not automatically reliable. A classifier can rank examples well while assigning systematically overconfident probabilities.
A concrete consumer-facing example is AI text detection: detector percentages are model outputs, not forensic proof, and their meaning depends on training data, thresholds, calibration, and the population being tested.
Neural networks and foundation models
Neural networks learn layered representations rather than relying entirely on manually designed features. Convolutional networks exploit spatial structure; recurrent networks and LSTMs model sequences; transformers use attention across tokens or patches; graph neural networks operate on relational structure; diffusion models support powerful generation. Foundation models extend the idea by pretraining broad representations that can be adapted by prompting, retrieval, fine-tuning, distillation, or tool use. Their capability does not remove the need to define uncertainty, evaluation, cost, and failure boundaries.
How Models Learn: The Steps That Decide Whether Evaluation Is Real
Define the decision before the prediction
A strong project begins with the action that follows the prediction. What is being predicted, at what moment, with which information, and what are the costs of a false positive and false negative? If the operational decision is unclear, optimizing AUC or accuracy can become sophisticated work on the wrong target.
Split data the way deployment will unfold
Training data fits parameters, validation data supports model and hyperparameter choices, and test data estimates final generalization. The split must match reality. Time-dependent problems often need chronological evaluation; grouped records may need to keep the same customer, patient, household, company, or device within one split. Otherwise the test set can contain information that is effectively already known.
Scikit-learn’s current common-pitfalls guidance is explicit that preprocessing learned from the test set creates data leakage and overly optimistic scores.
Treat representation as part of the hypothesis
Normalization, tokenization, imputation, feature extraction, embeddings, and image preprocessing determine what information reaches the model. A weak representation can create a hard ceiling even when the learning algorithm is powerful. Conversely, a better representation can let a simpler model outperform a more complex one.
Optimize one objective, evaluate the decision
Training losses such as squared error, cross-entropy, contrastive loss, ranking loss, or a reinforcement-learning reward tell the model what to improve mathematically. The deployment metric can be different. A fraud system trained with cross-entropy may ultimately be judged by dollars prevented, analyst workload, recall at a fixed false-positive budget, and customer friction.
Why Accuracy Is Often the Wrong Winner
Accuracy collapses different mistakes into one number. If 99% of transactions are legitimate, a classifier that always predicts “legitimate” reaches 99% accuracy while detecting no fraud. That is an extreme example, but the same problem appears whenever class imbalance or asymmetric error cost matters.
| Measure | Useful when | What it can hide |
| Precision | False alarms are expensive | Missed positives |
| Recall | Missing a true case is expensive | Operational burden from false positives |
| PR-AUC | Positive cases are rare | Choice of final decision threshold |
| ROC-AUC | Ranking across thresholds matters | Poor practical performance at the operating region |
| MAE / RMSE | Predicting continuous values | Business asymmetry of under- vs over-prediction |
| Calibration | Predicted probabilities drive decisions | Ranking quality by itself |
| Latency / throughput | Real-time serving matters | Statistical quality |
| Expected cost | Errors have monetary or operational consequences | Hard-to-price harms or long-term effects |
Calibration deserves special attention. If a model assigns roughly 0.70 probability to 100 similar cases, a well-calibrated system should see the event occur in about 70 of them over time. Scikit-learn’s calibration documentation makes the same distinction: a probability can be useful as a confidence level only when predicted probabilities line up with observed frequencies.
A Better Model-Selection Rule: Maximize Total Value, Not Score
There is no universally best model. The choice is conditional on the data, decision, error cost, infrastructure, and governance burden. A useful mental model is: total model value = prediction benefit − data cost − compute cost − maintenance cost − risk cost.
| Requirement | Often suitable starting points | Reason |
| Small structured dataset | Linear models, shallow trees, boosting | Strong baselines with modest data and compute |
| Tabular business data | Gradient boosting, random forests | Flexible nonlinear interactions |
| High-dimensional sparse text | Linear models, Naive Bayes, specialized transformers | Sparse-friendly or representation-rich |
| Images or multimodal inputs | CNNs, vision transformers, multimodal foundation models | Learn representations from raw media |
| Strict interpretability | Linear models, shallow trees, generalized additive models | Easier inspection and governance |
| Low-latency edge inference | Small trees, linear models, compressed networks | Predictable resource use |
| Explicit uncertainty | Bayesian methods, ensembles, calibrated classifiers | Decision-making can use risk estimates |
| Continually changing data | Online learning or monitored retraining | Adaptation becomes part of operation |
The baseline rule is ruthless but useful: if logistic regression performs almost as well as a large network, the complex model has not yet earned its extra cost. Google’s Rules of Machine Learning makes a similar engineering point, advising teams to build a solid end-to-end pipeline and start simple before adding complexity.
The surrounding data path matters too. Slow feature queries, missing indexes, or unstable joins can make an otherwise efficient model unusable; the same operational logic appears in Aperplexity’s database optimization guide.
Failure Modes That Benchmarks Commonly Miss
Leakage creates fake competence
Leakage occurs when training uses information that would not exist at prediction time, directly or indirectly. A random split can leak future patterns, preprocessing can fit on the full dataset, and labels can accidentally be encoded in features. The result is not merely an optimistic score; it is evidence that the evaluation experiment does not represent deployment.
Shortcut learning can look like intelligence
A model may exploit a correlate that is easy to learn but not stable or causal. Image models can latch onto scanner or site artifacts; risk models can use administrative behavior that changes when policy changes. Manual error analysis is one of the fastest ways to discover these shortcuts because aggregate metrics rarely tell you what signal the model actually used.
The label may encode an old decision
Labels are often treated as truth even when they are human judgments, delayed outcomes, proxies, or policy decisions. A hiring, fraud, credit, moderation, or quality label can reproduce historical practice rather than the underlying concept the team thinks it is learning. A more powerful model can amplify that mismatch more efficiently.
Training-serving skew breaks the laboratory contract
Google’s production guidance defines training-serving skew as a mismatch between training and serving inputs or transformations and recommends monitoring it explicitly. The practical rule is simple: train on what will actually exist at prediction time, transform it the same way, and test on recent data that resembles the next production window.
Deployment changes the environment
Once a model affects ranking, pricing, fraud controls, recommendations, or human review, people respond. Fraudsters adapt, customers change behavior, and employees learn how the system scores them. The model is no longer observing a passive world; it is participating in the process that generates future data.
That is where structured skepticism helps. Aperplexity’s critical thinking exercises use claim-evidence and alternative-explanation routines that translate well to manual model error review and post-deployment incident analysis.
A Five-Dimension Risk Test Before Deployment
A model that wins on one metric can still lose operationally. Before launch, score the candidate across five dimensions: predictive risk, data risk, operational risk, human risk, and change risk.
Predictive risk: How often is the model wrong, and how severe are the different error types?
Data risk: Are examples representative, current, correctly labeled, legally usable, and available at prediction time?
Operational risk: Can the model meet latency, throughput, availability, memory, and cost constraints?
Human risk: Can operators understand when to trust, challenge, or override the output?
Change risk: What happens when users, sensors, prices, policies, language, adversaries, or collection processes change?
NIST’s AI Risk Management Framework supports the broader principle behind this test: trustworthy AI requires risk management across design, development, deployment, use, and evaluation rather than a one-time accuracy check.
A Practical Workflow for Choosing and Operating a Model
- Define the real-world decision and when it must be made.
- List the information genuinely available at that moment.
- Quantify or rank the cost of each important error type.
- Establish a simple baseline before tuning complex models.
- Inspect the data for leakage, imbalance, missingness, sampling bias, and unstable proxies.
- Choose a validation design that mirrors deployment, including time and group structure.
- Compare more than one model family, not just hyperparameters within a favorite family.
- Measure statistical quality alongside latency, throughput, memory, interpretability, and cost.
- Check calibration, subgroup performance, and threshold sensitivity.
- Inspect individual errors manually and categorize their causes.
- Test on recent, external, or otherwise shifted data where possible.
- Document intended use, assumptions, known limitations, and conditions that should block use.
- Deploy monitoring for input drift, missingness, training-serving skew, model age, latency, and outcome quality.
- Create rollback and retraining rules before performance degrades.
For people turning this workflow into a career skill set, Aperplexity’s AI, cloud, and software engineering certification guide is most useful when credentials are paired with deployed projects that prove evaluation, monitoring, and operational judgment.
The Future of Machine Learning Models in 2027
The likely 2027 shift is not that every classical model disappears into a foundation model. It is that model choice becomes more explicitly economic and operational. Large pretrained models will continue to absorb more modalities and tasks, while smaller specialized models, distilled models, tree ensembles, and linear systems remain attractive where latency, privacy, interpretability, or predictable cost dominates.
The second shift is stronger lifecycle governance. NIST notes that AI RMF 1.0 is being revised and in April 2026 released a concept note for a trustworthy-AI profile in critical infrastructure. That direction reinforces a production reality already visible in engineering guidance: evaluation cannot stop at a held-out test set. Monitoring, traceability, change management, and human escalation become part of the model contract.
The uncertain part is how quickly tooling standardizes around those controls. Model registries, evaluation suites, drift checks, lineage, and automated retraining are improving, but there is no single universal stack. Teams should therefore optimize for portable evaluation logic and clear decision thresholds rather than tying model trust to one vendor dashboard.
Key Takeaways
- A trained model is only one component of a production machine learning system; data and serving pipelines can invalidate a good predictor.
- Separate learning signal, output type, and model structure instead of treating them as one taxonomy.
- Use accuracy only when the class balance and error costs make accuracy meaningful; otherwise choose metrics tied to the decision.
- Calibration matters whenever probabilities influence thresholds, staffing, pricing, triage, or risk acceptance.
- Leakage, shortcut learning, weak labels, skew, and feedback loops can create failure even when offline evaluation looks strong.
- Start with a simple baseline and make complexity earn its cost in measurable deployment value.
- Monitoring and rollback are not MLOps decoration; they are part of the model’s reliability design.
Conclusion
Machine learning models are easiest to understand when they are treated as decision systems under constraints rather than as a leaderboard of algorithms. Linear models, trees, ensembles, probabilistic methods, neural networks, and foundation models each buy different capabilities, but each also carries assumptions about data, computation, uncertainty, and maintenance.
The practical discipline is to work backward from the decision. Define what information exists at prediction time, what mistakes cost, what latency and interpretability are required, and how the environment can change after launch. Then build a baseline, validate honestly, inspect errors, and measure the system in production. A slightly weaker offline score can be the stronger real-world choice when it is cheaper, better calibrated, easier to audit, more stable across subgroups, or easier to roll back. That is the standard that turns machine learning from a demo into dependable infrastructure.
Frequently Asked Questions
What are machine learning models?
Machine learning models are fitted computational functions that learn parameters or structure from data and then use new inputs to produce predictions, rankings, classifications, representations, generated outputs, or actions. The model is distinct from the learning algorithm and from the larger production system that supplies data, serves predictions, monitors behavior, and handles retraining or human review.
What are the main types of machine learning models?
There is no single exhaustive list because models can be classified along different axes. By learning signal, common categories include supervised, unsupervised, semi-supervised, self-supervised, and reinforcement learning. By structure, major families include linear models, trees and ensembles, kernel methods, nearest-neighbor methods, probabilistic models, neural networks, and graph models.
What is the difference between a machine learning algorithm and a model?
An algorithm is the procedure used to learn from data; a model is the fitted result used for inference. For example, a tree-building algorithm chooses splits during training, while the final tree containing its learned thresholds and leaf values is the trained model.
Which machine learning model is best?
There is no best model independent of the task. The right choice depends on data size and structure, prediction target, error costs, interpretability, latency, compute budget, uncertainty requirements, and how often the environment changes. A simple model can be better if it achieves nearly the same decision value at much lower operational cost.
Why do machine learning models fail after deployment?
Common causes include data drift, concept drift, training-serving skew, leakage discovered too late, changing user behavior, stale labels, new sensors or data pipelines, adversarial adaptation, and feedback loops created by the model itself. Production monitoring is required because the code can stay unchanged while the environment changes.
What is overfitting in machine learning?
Overfitting occurs when a model captures noise, accidental correlations, or quirks of the training data that do not generalize. It usually appears as strong training performance and weaker performance on genuinely new data. Regularization, simpler models, more representative data, correct validation, and error analysis can reduce the risk.
Do neural networks always outperform simpler models?
No. Neural networks are powerful when representation learning is valuable and sufficient data and compute exist, especially for images, language, audio, and multimodal inputs. On many structured business datasets, boosted trees or even linear models can remain competitive while being cheaper, faster, and easier to govern.
Methodology
Research was conducted on October 7, 2026. I reviewed a representative current high-visibility SERP sample for “machine learning models” and close informational variants. The sample included TechTarget, Dataquest, Snowflake, Coursera, Google Cloud, IBM, Alibaba Cloud, ClicData, GrowthGear, and Straive. Search order varies by location, personalization, device, and index freshness, so this is a competitive snapshot rather than a permanent global top-10 claim.
The recurring competitor strengths were definitions, learning-type taxonomies, algorithm lists, examples, and basic selection guidance. The main content gap was operational decision quality: model-versus-system boundaries, calibration, error cost, leakage, training-serving skew, feedback loops, subgroup behavior, and lifecycle monitoring. The article structure was built independently around those gaps rather than copying any competitor’s heading sequence.
Factual validation prioritized current scikit-learn documentation on leakage, inspection, and calibration; Google’s Rules of Machine Learning and production monitoring guidance; NIST’s AI Risk Management Framework; and recent guidance on common machine-learning pitfalls. I did not run a new benchmark or production experiment for this article, so performance claims are framed as conditional guidance rather than universal rankings. Model behavior remains dependent on data, implementation, thresholds, and deployment context.
This article was drafted with AI assistance and reviewed by a human editor before publishing. All data, citations, and claims have been independently verified against primary sources.
References
- Bergmann, D. (2025, September 18). What are machine learning algorithms? IBM.
- Google. (n.d.). Rules of Machine Learning: Best practices for ML engineering. Google for Developers. Retrieved October 7, 2026.
- Google. (n.d.). Production ML systems: Monitoring pipelines. Google for Developers. Retrieved October 7, 2026.
- Kapoor, S., & Narayanan, A. (2024). Avoiding common machine learning pitfalls: Patterns. Patterns.
- National Institute of Standards and Technology. (2023). Artificial Intelligence Risk Management Framework (AI RMF 1.0) (NIST AI 100-1).
- National Institute of Standards and Technology. (2026). AI Risk Management Framework. Retrieved October 7, 2026.
- scikit-learn developers. (2026). Common pitfalls and recommended practices. scikit-learn documentation.
- scikit-learn developers. (2026). Probability calibration. scikit-learn 1.9.1 documentation.
- scikit-learn developers. (2026). Inspection. scikit-learn 1.9.1 documentation.
Cloud Gaming in 2026 is no longer mainly a question of whether streaming games can work; it can. The sharper question is what players give up when a remote data center becomes the console. That trade is easy to miss because the visible benefit is simple—less local hardware—while the hidden costs sit in networks, water and electricity demand, licensing, platform economics, and dependence on a service that can change or close.
Most high-visibility guides still center on definitions, service rankings, speed requirements, and the familiar latency debate. Those are useful entry points, but they understate how much the model has changed. A cloud session is a real-time distributed system: the game runs on a GPU server, inputs travel upstream, frames are encoded, transported, decoded, and displayed, and every weak link can become part of the player experience. A modern connection can be fast on a speed test and still feel poor if latency varies from moment to moment.
The infrastructure side also deserves more scrutiny. Berkeley Lab’s 2024 U.S. Data Center Energy Usage Report estimated about 65 billion liters of direct data-center water consumption in 2023. That figure should not be misrepresented as a cloud-gaming number—the report does not break out gaming workloads—but it shows why ‘no console required’ does not mean ‘no physical footprint.’ Compute has simply moved elsewhere.
This guide therefore treats cloud gaming as a systems and ownership problem, not merely a service-comparison problem. It covers what the current search results get right, what they usually miss, and how to decide whether the model fits a particular kind of player.
What Current Cloud Gaming Guides Get Right—and Miss
A current SERP sample is remarkably consistent. Pages from telecoms, storage brands, cloud-service review sites, and gaming explainers generally answer four questions well: what cloud gaming is, which services exist, what connection speed is recommended, and how latency affects play. The weakness is structural. Many pages stop at the device in the player’s hand instead of following the workload into the data center and the licensing contract behind it.
| Common SERP angle | What it answers well | What it often misses |
| What is cloud gaming? | Clear explanation of remote rendering and streamed video | How many infrastructure dependencies replace the local console |
| Best services | Catalogs, device support, tiers, resolution | Business durability, delisting risk, and portability |
| Internet requirements | Bandwidth and headline latency | Jitter, packet loss, route quality, Wi-Fi contention, decoder delay |
| Pros and cons | Convenience versus input lag | Resource use, ownership control, regulatory power, shutdown risk |
| Future of gaming | 5G, edge computing, better codecs | Whether economics and rights make the model sustainable |
How Cloud Gaming Actually Works
The game does not run on the phone, laptop, television, or thin client. It runs on a remote machine with CPU and GPU resources. The client captures input, sends it to the server, receives an encoded video stream, decodes it, and presents the next frame. That sounds like video streaming, but the timing constraint is far stricter because the viewer is controlling the scene in real time.
The latency budget is a chain, not one number
End-to-end responsiveness includes local input delay, uplink transit, server simulation and rendering, video encoding, network transit back to the player, decoding, display processing, and the screen’s own scan-out. A 2026 Computer Networks study emphasizes that cloud-gaming quality depends on throughput, latency, packet loss, graphics settings, and how platforms adapt streaming behavior to network conditions.
That is why monitoring only an endpoint is not enough. Aperplexity’s Status Probe guide makes the same systems point in a different context: a service can return a healthy status while the user journey is still slow or degraded. For cloud play, a connection can be technically ‘up’ while jitter makes aiming or timing feel inconsistent.
Bandwidth still matters, but stability matters more
NVIDIA’s current GeForce NOW system requirements scale from 15 Mbps for 720p/60 to much higher rates for high-resolution, high-frame-rate streaming, while also recommending Ethernet or 5 GHz Wi-Fi and less than 80 ms network latency to an NVIDIA data center. Those figures are useful ceilings and floors, not guarantees of feel. A stable 35 ms path can be easier to play on than one bouncing between 25 and 90 ms.
The Environmental Blind Spot Is the Data Center
The environmental argument around cloud gaming is usually framed as electricity. Water is the less visible constraint because many data centers use water directly for cooling, while additional water can be consumed indirectly through electricity generation. Berkeley Lab estimates that direct U.S. data-center water consumption rose to roughly 65 billion liters in 2023 and projects materially higher totals under future growth scenarios.
Cloud gaming does not have a clean standalone water number
This is where weaker articles overreach. Public data-center reports aggregate many workloads: enterprise computing, web services, AI, storage, and more. There is no defensible national figure that says ‘cloud gaming used X gallons.’ The correct conclusion is narrower: every streamed gaming session consumes remote compute and network resources, so cloud gaming inherits the physical constraints of the facilities serving it.
The newer Berkeley Lab 2025 update projects data centers could account for 11.8% of U.S. electricity use by 2030 in its reference case, with a scenario range of 9.5% to 15.3%. Gaming is only one workload inside that total, but competition for GPU capacity, power, cooling, and grid connections affects the economics of any GPU-heavy service.
Location changes the sustainability story
A liter of cooling water does not have the same local consequence everywhere. The meaningful sustainability question is not only how efficient a data center is, but where it is built, what cooling system it uses, what the local watershed can support, and what energy source powers it. For players, these details are invisible. For platform operators, they increasingly shape siting and cost.
You Do Not Just Buy a Game—You Buy a Chain of Access
Digital ownership discussions become sharper in the cloud because the player may not possess a local executable, a permanent build, or any way to keep playing after a service change. But the ownership model varies. Subscription catalogs grant temporary access; owned-library services may stream games licensed through third-party stores; remote-PC services provide a virtual machine but still depend on platform and game licenses.
Stadia is the case study every cloud gamer should remember
Google announced in September 2022 that Stadia would wind down and that players would retain access until January 18, 2023. It also refunded Stadia hardware bought through the Google Store and game and add-on purchases made through the Stadia store. The official shutdown announcement matters because it demonstrates two things at once: consumer protection can soften a shutdown, and a cloud library can still be dependent on one company’s strategic decision.
The lesson is not ‘never buy digital games.’ It is to separate payment from control. Ask whether a purchase survives a service exit, whether the game exists in another store, whether save data can move, and whether there is a local fallback.
A practical ownership hierarchy
| Access model | What the player controls | Main weakness |
| Local physical or DRM-light copy | Local installation and media or files | Hardware compatibility, patches, disc/media loss |
| Local digital purchase | Local installation while license/store remains valid | Account and DRM dependence |
| Owned-library cloud streaming | Store entitlement plus remote streaming access | Both store rights and streaming support must remain |
| Subscription cloud catalog | Access while subscription and catalog rights remain | Titles can rotate out; no permanent entitlement |
| Remote cloud PC | Virtual machine access; user may install supported titles | Provider cost, policy limits, game anti-cheat compatibility |
Latency Has Improved; Variance Is the Harder Problem
The old binary claim—local is responsive, cloud is laggy—is too crude for 2026. Edge infrastructure, faster codecs, better scheduling, and higher-quality access networks have narrowed the baseline gap for many players. Yet physics has not disappeared. A cloud input must still travel to a remote machine and the resulting frame must travel back.
Competitive play exposes the remaining distance
For slower strategy, turn-based, role-playing, and many single-player games, consistent cloud latency can be perfectly acceptable. Competitive shooters, rhythm games, fighting games, and high-speed platformers expose delay and jitter much more aggressively. Local rendering can eliminate the network round trip between input and game simulation; cloud delivery cannot.
This is also why backend architecture matters. Aperplexity’s Microservices Architecture guide explains how distributed systems accumulate network boundaries, observability needs, and failure modes. A cloud-gaming stack is not necessarily built as microservices end to end, but the same engineering truth applies: every additional dependency must be measured because a small delay in several places becomes a visible delay at the screen.
Accessibility Is a Real Advantage—With Conditions
Cloud gaming can lower one major accessibility barrier: the need to own and physically use a high-end local machine. A lightweight laptop, phone, browser client, television, or handheld may become a front end for far more demanding games. That flexibility can matter for players who already rely on customized seating, mounting, switch controls, or adaptive inputs.
Input flexibility matters more than the cloud label
Microsoft’s Xbox Accessibility Guideline for input recommends support for standard controllers, adaptive controllers, keyboards, mice, switch access, voice input, and other assistive technologies where appropriate. The cloud can make compute location irrelevant, but the client still has to recognize and pass through the input method correctly.
Browser clients create both opportunity and complexity. Aperplexity’s ChromiumFX guide is a useful reminder that browser-embedded experiences depend on runtime versions, security updates, input handling, and codec support. A service that works in one browser or television generation can still lose compatibility later.
Cloud accessibility should be evaluated end to end
| Layer | Accessibility question | Why it matters |
| Game design | Can controls be remapped and timing demands adjusted? | Streaming cannot fix inaccessible game rules |
| Client device | Does it support the required controller or assistive input? | The front end may become the blocking layer |
| Cloud service | Does the session pass input reliably and expose accessibility settings? | Feature parity may differ across clients |
| Network | Is latency stable enough for the player’s control method? | Assistive workflows can be more sensitive to timing |
| Account/platform | Can settings, saves, and profiles follow the player? | Device flexibility is weaker if configuration is not portable |
Emerging Markets: Cloud Gaming Can Leapfrog Hardware, but Networks Decide
The strongest economic case for cloud gaming may be where gaming PCs and current consoles are expensive relative to local incomes. A phone-first player can theoretically rent high-end compute instead of buying it. That resembles other ‘leapfrog’ technologies: infrastructure is centralized and the user accesses the capability through a cheaper endpoint.
The catch is that broadband quality is not the same as broadband availability
A market can have widespread 4G or fiber coverage and still deliver uneven cloud gaming because peering, international routes, congestion, data caps, household Wi-Fi, and distance to the provider’s nearest region determine the real path. The cloud model therefore shifts affordability from a one-time device purchase toward recurring connectivity and service costs.
Local device constraints do not disappear entirely either. The client still needs a reliable decoder, sufficient memory, compatible browser or app support, and responsive input. Aperplexity’s swap file explainer covers the broader point that low-memory devices can stay functional by leaning on storage, but sustained memory pressure still hurts responsiveness. Cloud gaming reduces GPU requirements far more than it eliminates all local requirements.
The Platform Wars Are Really About Rights and Distribution
Cloud gaming became an antitrust issue because control of major game rights can determine which streaming services have attractive catalogs. The UK Competition and Markets Authority blocked Microsoft’s original Activision Blizzard acquisition structure in April 2023 over cloud-gaming concerns. The restructured deal transferred Activision’s cloud-streaming rights outside the EEA to Ubisoft before the CMA cleared it.
The CMA’s September 2023 decision is important because regulators were not arguing about whether streaming technology worked. They were arguing about who would control the content rights that make a cloud platform competitive. That is a deeper constraint than bitrate or resolution.
Why this matters to players
A technically excellent service with a weak catalog can fail to matter. A dominant catalog owner can shape licensing terms, device access, and bundling. In other words, cloud gaming is a distribution market as much as a computing technology. The competitive question is who can offer the right games, in the right territories, on acceptable terms, at infrastructure costs that still support a viable business.
Beyond Consumer Gaming: The Same Stack Has Other Uses
Remote interactive rendering is useful beyond entertainment. The same general architecture can support virtual workstations, simulation, training, streamed 3D design, education labs, and interactive visualization. That does not mean every cloud-gaming platform can be repurposed directly; security, session persistence, data governance, input devices, and application licensing differ. The transferable asset is the low-latency remote-rendering stack.
The economics improve when expensive hardware is shared
A centrally managed GPU fleet can be attractive when users need bursts of high-end compute rather than permanent local capacity. The operator can schedule, upgrade, and monitor shared hardware while the user keeps a simpler endpoint. But utilization has to be high enough to justify the capital and energy costs. Idle premium GPUs are expensive inventory.
The same browser and delivery discipline that improves ordinary web software still matters at the edge. Aperplexity’s Web Development Best Practices guide emphasizes measurable performance, accessibility, security, and failure recovery—the same qualities a cloud client needs if it is supposed to feel invisible to the player.
Who Should Choose Cloud Gaming in 2026?
Cloud gaming is not a universal replacement for local hardware. It is a different cost and control model. The best fit depends on what the player values most.
| Player profile | Cloud fit | Reason |
| Casual or single-player gamer with good broadband | Strong | Convenience and low local hardware requirements usually outweigh small response penalties |
| Frequent traveler or multi-device player | Strong | Progress and compute can follow the account across endpoints |
| Budget-constrained player near a provider region | Potentially strong | Avoids large upfront GPU/console cost if recurring fees and data are affordable |
| Competitive esports player | Weak to mixed | Even good cloud performance adds network distance and variance |
| Collector or preservation-focused player | Weak | Service and license dependence conflict with long-term control |
| Player with adaptive input needs | Case-by-case | Can be excellent if the full client-to-game input path supports the required device |
The Future of Cloud Gaming in 2027
The 2027 story will probably be less about a dramatic latency breakthrough and more about economics. Technical quality is improving, but cloud gaming competes for the same data-center power, GPU capacity, cooling infrastructure, and network investment being pulled by AI and other accelerated workloads. Berkeley Lab’s 2025 update expects U.S. data-center electricity demand to continue rising rapidly, which makes resource efficiency a business requirement rather than a marketing extra.
Platforms are also likely to become more selective about where and how they offer premium streaming. Device support, session limits, resolution tiers, game rights, and regional availability can all be adjusted to manage cost. That means cloud gaming may grow without becoming a single universal ‘Netflix for games.’ Multiple access models are more plausible: subscriptions, owned-library streaming, console extensions, and remote-PC products serving different users.
The technical frontier will remain edge placement, adaptive encoding, route optimization, and better prediction of changing network conditions. But the harder constraint is coordination: platform rights, infrastructure cost, and service durability must improve together. A faster codec cannot fix a missing game license, and a huge catalog cannot fix an unprofitable server fleet.
Key Takeaways
- Cloud gaming replaces high-end local hardware with a dependency on remote GPUs, networks, codecs, and platform availability.
- Data-center water and electricity demand matter, but current public reports do not isolate cloud gaming’s share; avoid fake precision.
- Stadia proved that refunds can protect buyers financially while still leaving long-term access dependent on the platform.
- In 2026, jitter and route consistency often matter more than headline bandwidth once minimum speed is met.
- Accessibility can improve through device flexibility and adaptive input support, but only when the entire client-to-game path works.
- Cloud gaming is also a rights market: the Microsoft–Activision case showed that content control can shape competition.
- Choose cloud for convenience and flexibility; choose local hardware when low-latency control, offline play, or preservation matters most.
Conclusion
Cloud gaming has matured enough that the old question—‘does it work?’—is no longer very useful. For many genres and many households, it does. The decision now sits in the trade: local hardware cost versus recurring service dependence, device flexibility versus network sensitivity, instant access versus weaker long-term control.
The hidden infrastructure matters because the cloud is physical. Remote GPUs consume electricity, data centers need cooling, networks have finite capacity, and every millisecond of distance has consequences. The ownership layer matters for the same reason: when the executable and service both live elsewhere, access depends on contracts and platform strategy.
That does not make cloud gaming a bad model. It makes it a specialized one. It is strongest when the player values convenience, low upfront hardware cost, and cross-device access. It is weakest when the goal is permanent possession, offline resilience, or the lowest possible response time. In 2026, choosing well means judging the entire system—not just the picture quality.
Frequently Asked Questions
Is cloud gaming worth it in 2026?
Yes for many players with stable low-latency broadband, especially if they value device flexibility and want to avoid a large hardware purchase. It is less attractive for competitive esports, offline play, long-term preservation, or users far from a provider region.
How much internet speed does cloud gaming need?
Requirements vary by service and resolution. NVIDIA currently lists 15 Mbps for 720p/60 and higher rates for higher resolutions and frame rates. Speed alone is not enough: stable latency, low packet loss, and a clean Wi-Fi or Ethernet path often matter more once the bandwidth minimum is met.
Does cloud gaming use more electricity than local gaming?
It can shift and sometimes increase energy use because the workload runs in a data center and the video stream must also be encoded and transported. A universal per-hour comparison is not defensible because hardware efficiency, resolution, codec, network, server utilization, and local device power vary widely.
Does cloud gaming use a lot of water?
Cloud gaming relies on data centers, and many data centers consume water for cooling, but current public reports do not isolate cloud gaming’s share. Berkeley Lab estimated roughly 65 billion liters of direct U.S. data-center water consumption in 2023 across all workloads.
Do you own games you play through cloud gaming?
It depends on the access model. A subscription catalog usually grants temporary access. An owned-library service may stream a game tied to a separate store entitlement. Either way, streaming availability can still depend on licensing, region, and platform support.
Can cloud gaming replace a gaming PC or console?
For casual, story-driven, strategy, and many single-player games, it can replace much of the practical need for high-end local hardware. It is a weaker substitute for latency-sensitive competition, mod-heavy workflows, offline play, and users who want maximum control over files and hardware.
Is cloud gaming better for accessibility?
It can be, because powerful games can run on lighter devices and adaptive input setups may work across more endpoints. But accessibility is not automatic; the game, client device, cloud platform, controller path, and network all have to support the player’s needs.
Methodology
Research was conducted on October 6, 2026. I reviewed a representative current high-visibility SERP sample for “cloud gaming,” including Kingston, T-Mobile, Cloudwards, Cloud Loadout, Techgenyz, iTechGuides, TechExplain, The Core ITech, Techopedia, and IEEE/Wikipedia-style reference coverage. Search order varies by location, personalization, device, and index freshness, so this is a competitive sample rather than a permanent global ranking.
The recurring competitor strengths were definitions, service comparisons, internet requirements, latency, and basic pros/cons. The recurring gaps were data-center resource constraints, the lack of workload-specific water accounting, access and preservation risk, jitter versus headline latency, accessibility across the full input path, and cloud-gaming rights as an antitrust issue. The article structure was built around those gaps rather than copying any competitor’s section order.
For factual validation, I prioritized Lawrence Berkeley National Laboratory and U.S. Department of Energy data-center reports, Google’s Stadia shutdown announcement, the UK Competition and Markets Authority’s Microsoft–Activision cloud-gaming decisions, Microsoft accessibility guidance, NVIDIA’s current GeForce NOW requirements, and a 2026 peer-reviewed Computer Networks study. Internal links were checked as live aperplexity.com pages before insertion.
This article was drafted with AI assistance and reviewed by a human editor before publishing. All data, citations, and claims have been independently verified against primary sources.
References
- Competition and Markets Authority. (2023, September 22). New Microsoft/Activision deal addresses previous CMA concerns in cloud gaming.
- Google. (2022, September 29). A message about Stadia and our long term streaming strategy.
- Lawrence Berkeley National Laboratory. (2024). 2024 United States Data Center Energy Usage Report.
- Lawrence Berkeley National Laboratory. (2026). United States Data Center Energy Usage Report: 2025 Update.
- Lyu, M., Wang, Y., & Sivaraman, V. (2026). Systematic assessment of cloud game adaptability for network conditions and user experience. Computer Networks, 281, 112214.
- Microsoft. (2026). Xbox Accessibility Guideline 107: Input.
- NVIDIA. (2026). System Requirements for GeForce NOW Cloud Gaming.
- Xbox. (2026). Xbox Cloud Gaming.
-
 Technology1 month ago
Hitomi la in 2026: Domain Status, Safety and Risks
-

 Technology1 month ago
ThomsonKids.com: Website Guide, Topics & Trust Check
-

 General1 month ago
Voozon.com: What It Is and How the Platform Works
-

 Business1 month ago
incabizgrowth.com Review: Content, Trust & Use
-

 Technology1 month ago
thesindi com Review: What TheSindi.com Really Offers
-

 Technology2 weeks ago
Scrolller in 2026: How It Works, Risks and Alternatives
-

 Business1 month ago
5starsstocks.com Review: Features, Trust and Safety
-
 Technology3 weeks ago
Web Development Best Practices: A 2026 Quality System